

Jev makes agent evaluation cheap. Beacon turns it into cross-harness memory
Coding agents are getting much better at solving complex engineering tasks. But they still have a basic problem: they forget.
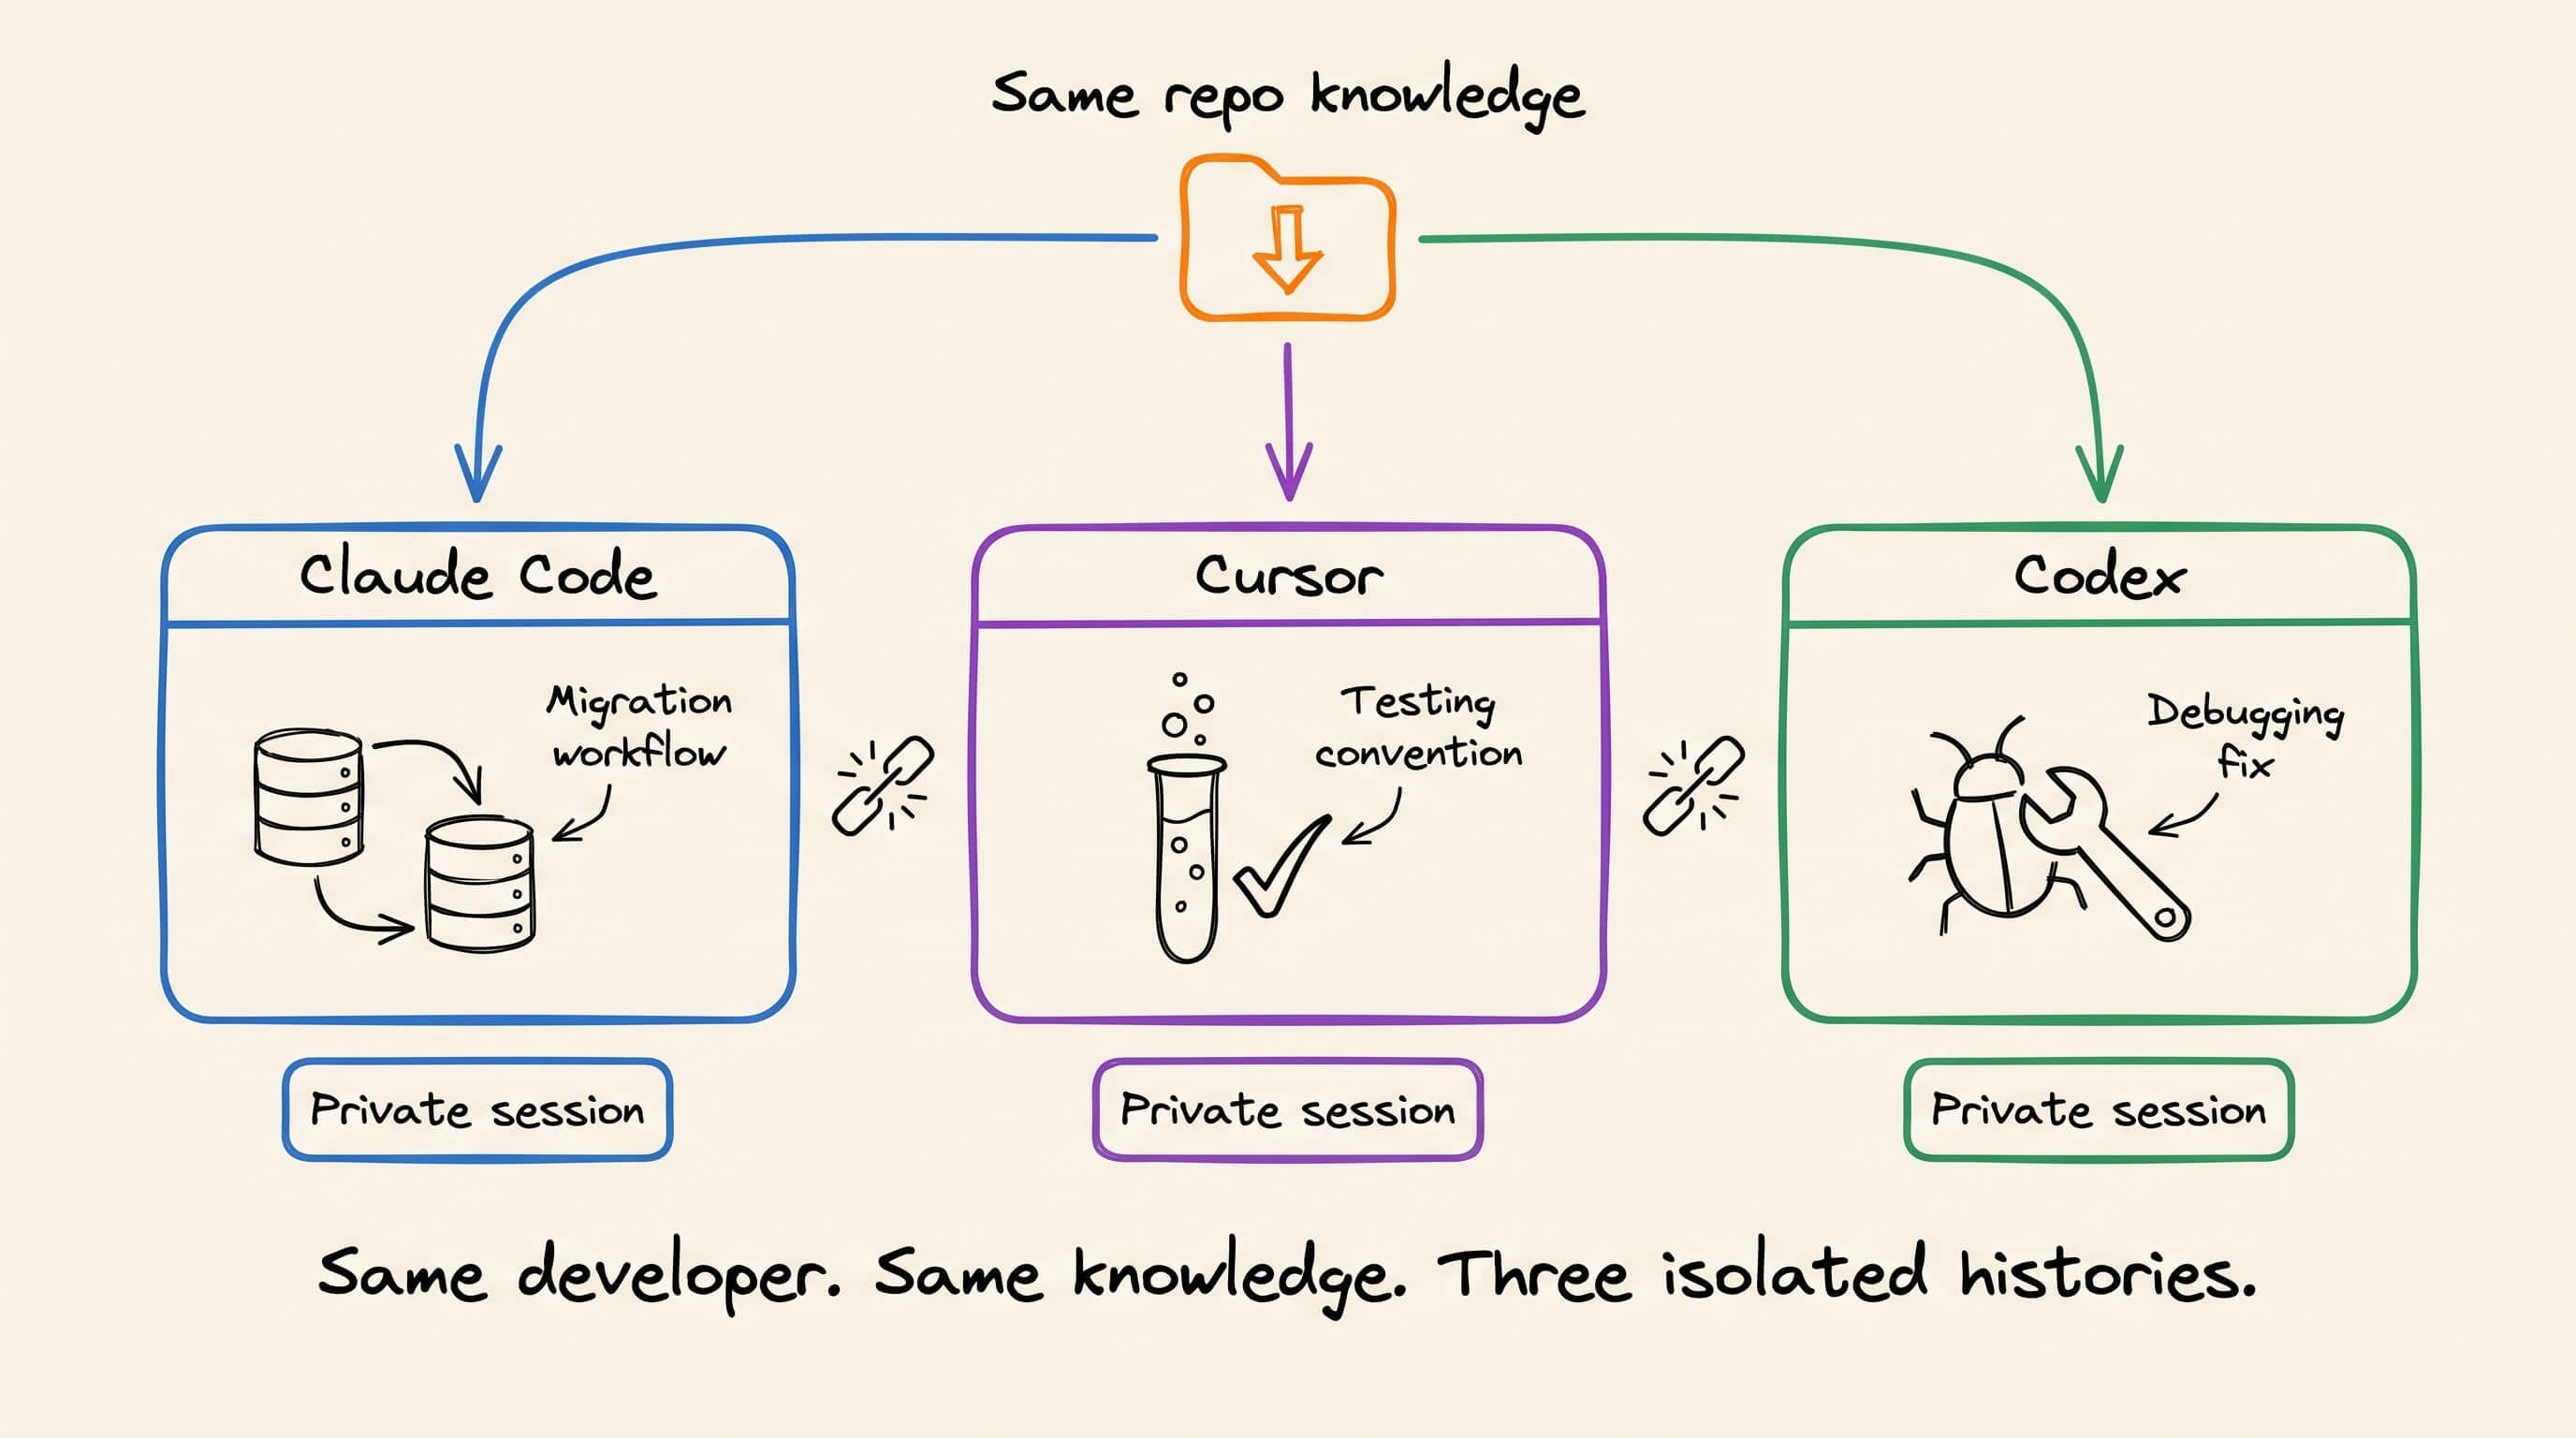
You might spend 30 minutes showing Claude Code how your repo handles migrations. Later, you correct Cursor on the same testing convention. Then Codex runs into a similar debugging problem and has to rediscover the solution from scratch.
Each agent session creates useful knowledge, but most of that knowledge stays trapped inside individual transcripts.
And with new models like Jev making fast evaluation of agent runs dramatically cheaper, it is suddenly much more practical to ask:
Which of those runs are actually worth learning from?
Beacon, built by Asymptote Labs, puts that signal to work.
Beacon is an open-source telemetry and memory layer that captures agent activity across Claude Code, Codex, Cursor, OpenCode, Cline, and 19+ other agent harnesses.
It can use Jev to evaluate those traces, identify the highest-signal runs, and extract recurring workflows, corrections, and debugging patterns.
Those patterns can then be turned into skills that future agents can use.
Here’s the repo: github.com/Asymptote-Labs/agent-beacon
(don’t forget to star it ⭐)
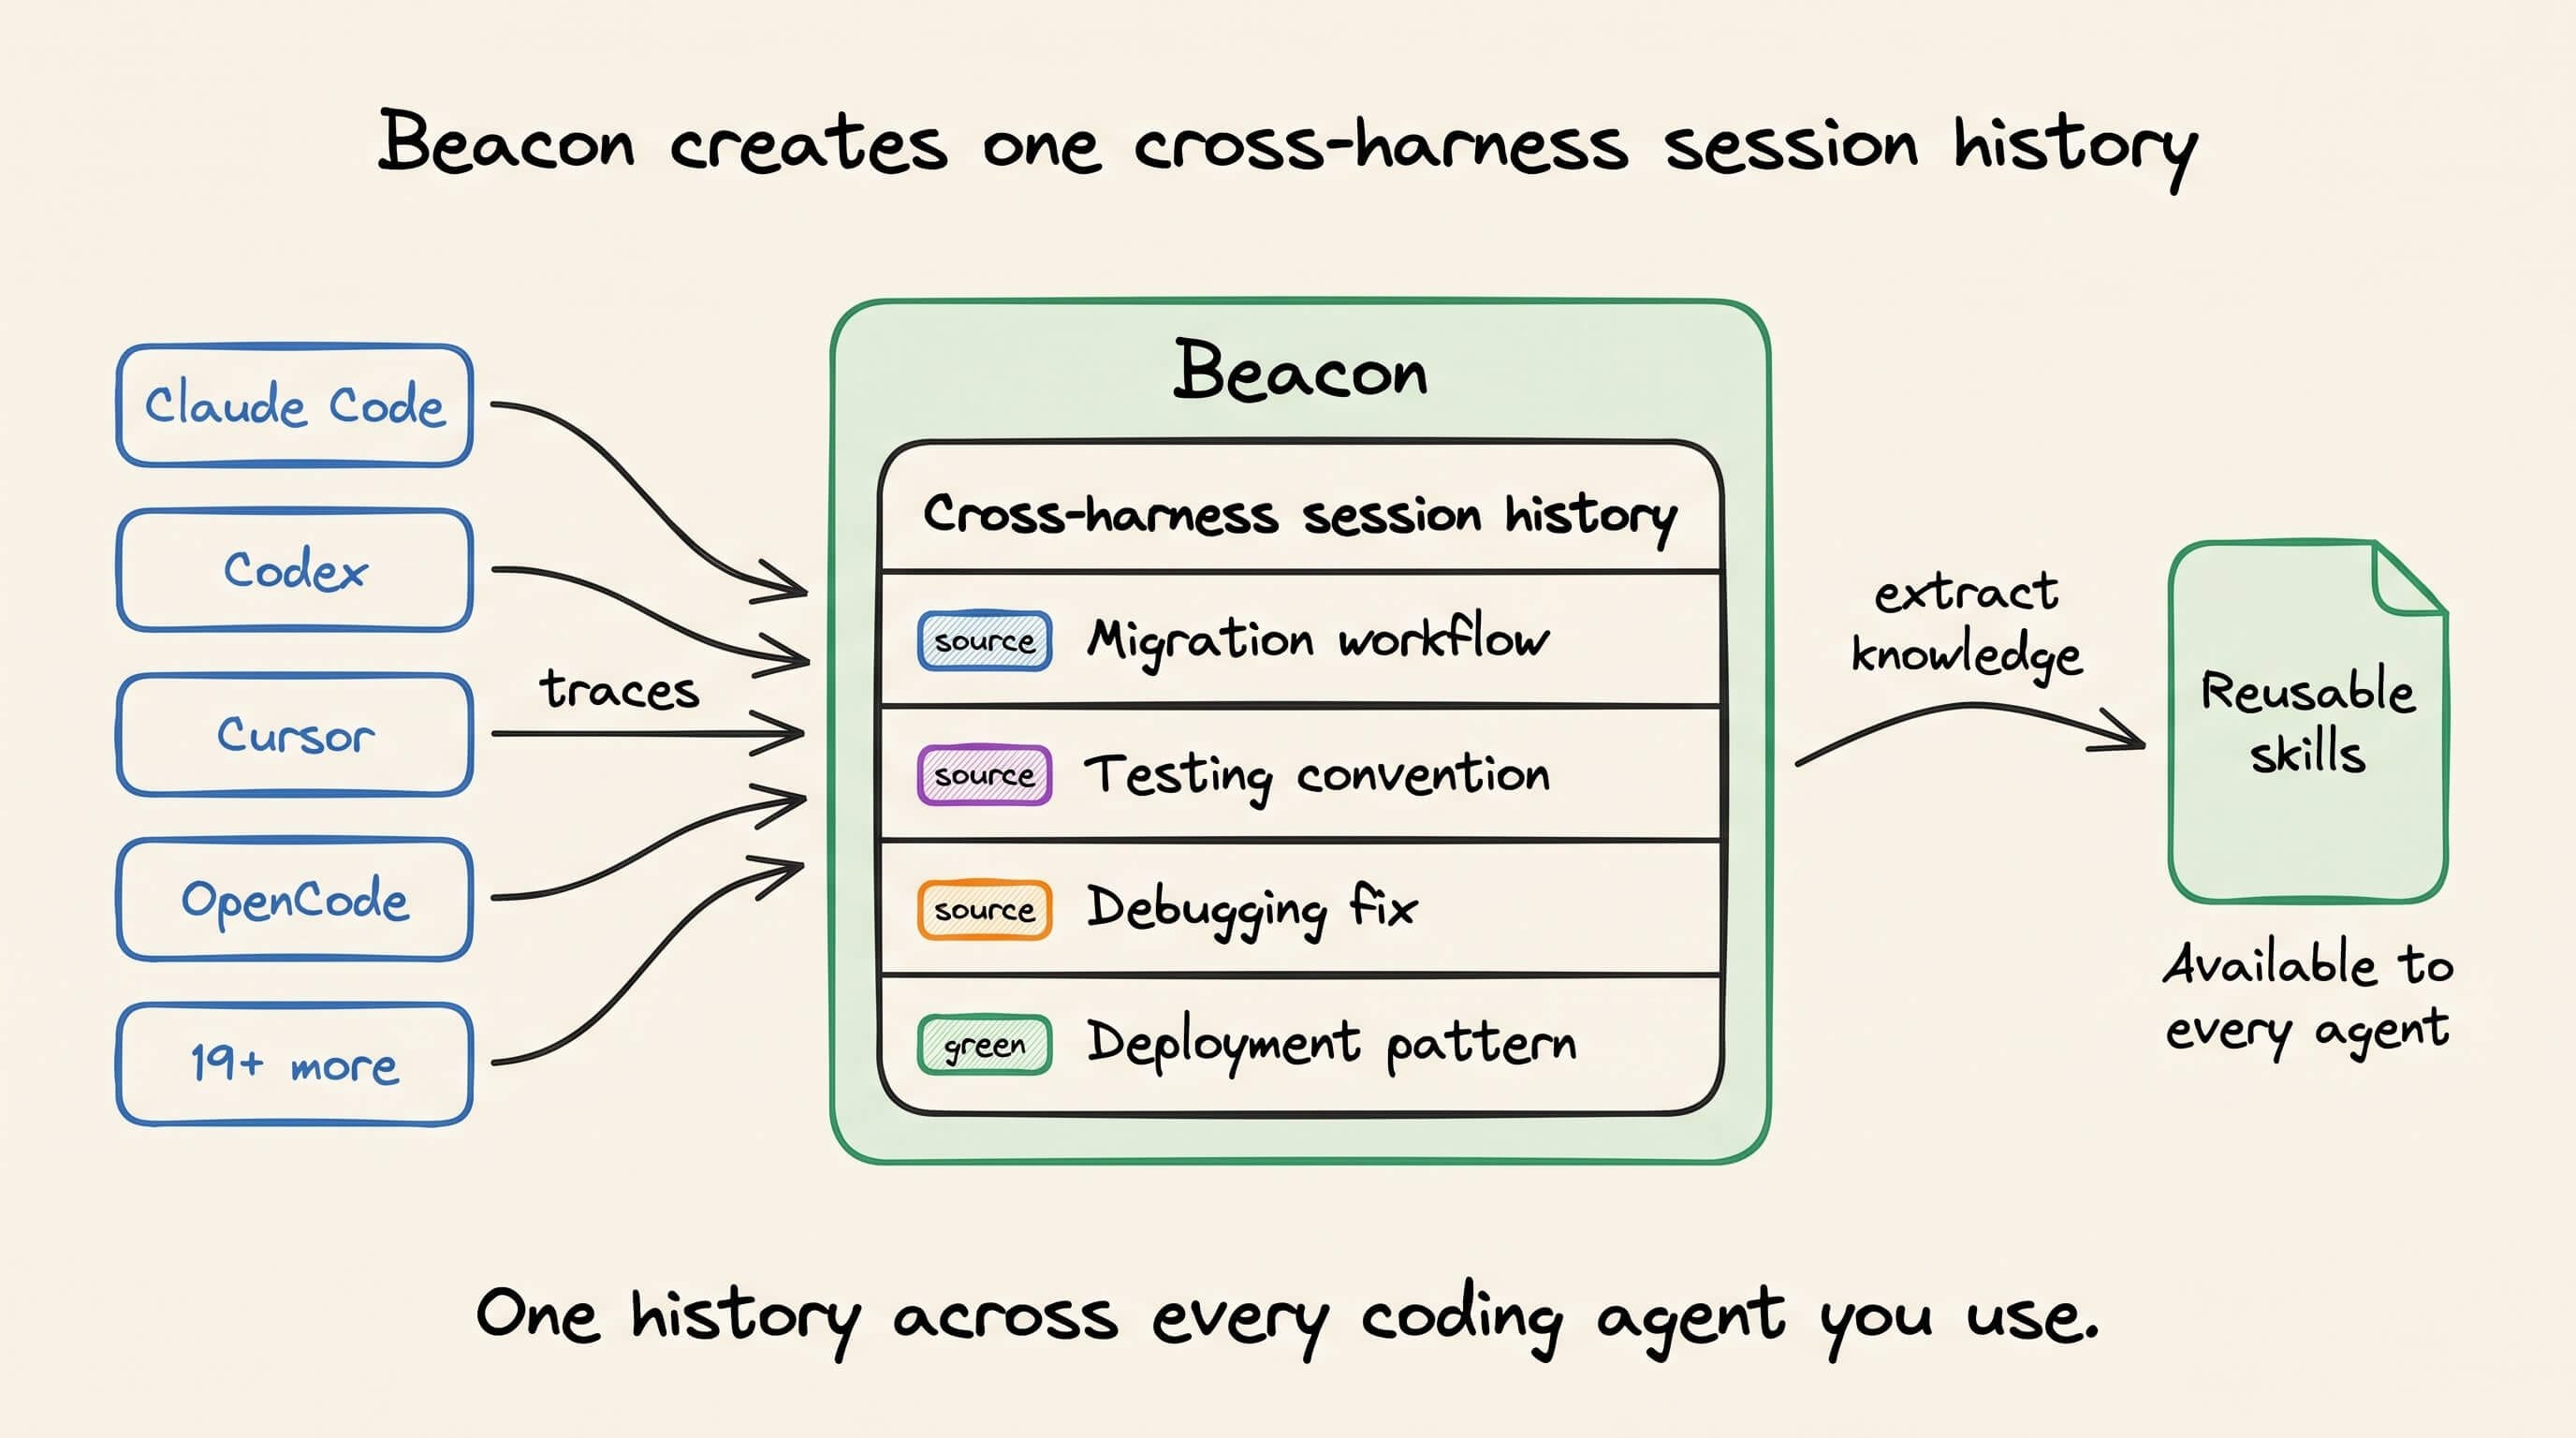
The important part is that Beacon sits across the harness layer.
Your Claude Code sessions can teach Codex.
Your Cursor debugging can improve OpenCode.
A workflow solved once can become reusable everywhere.
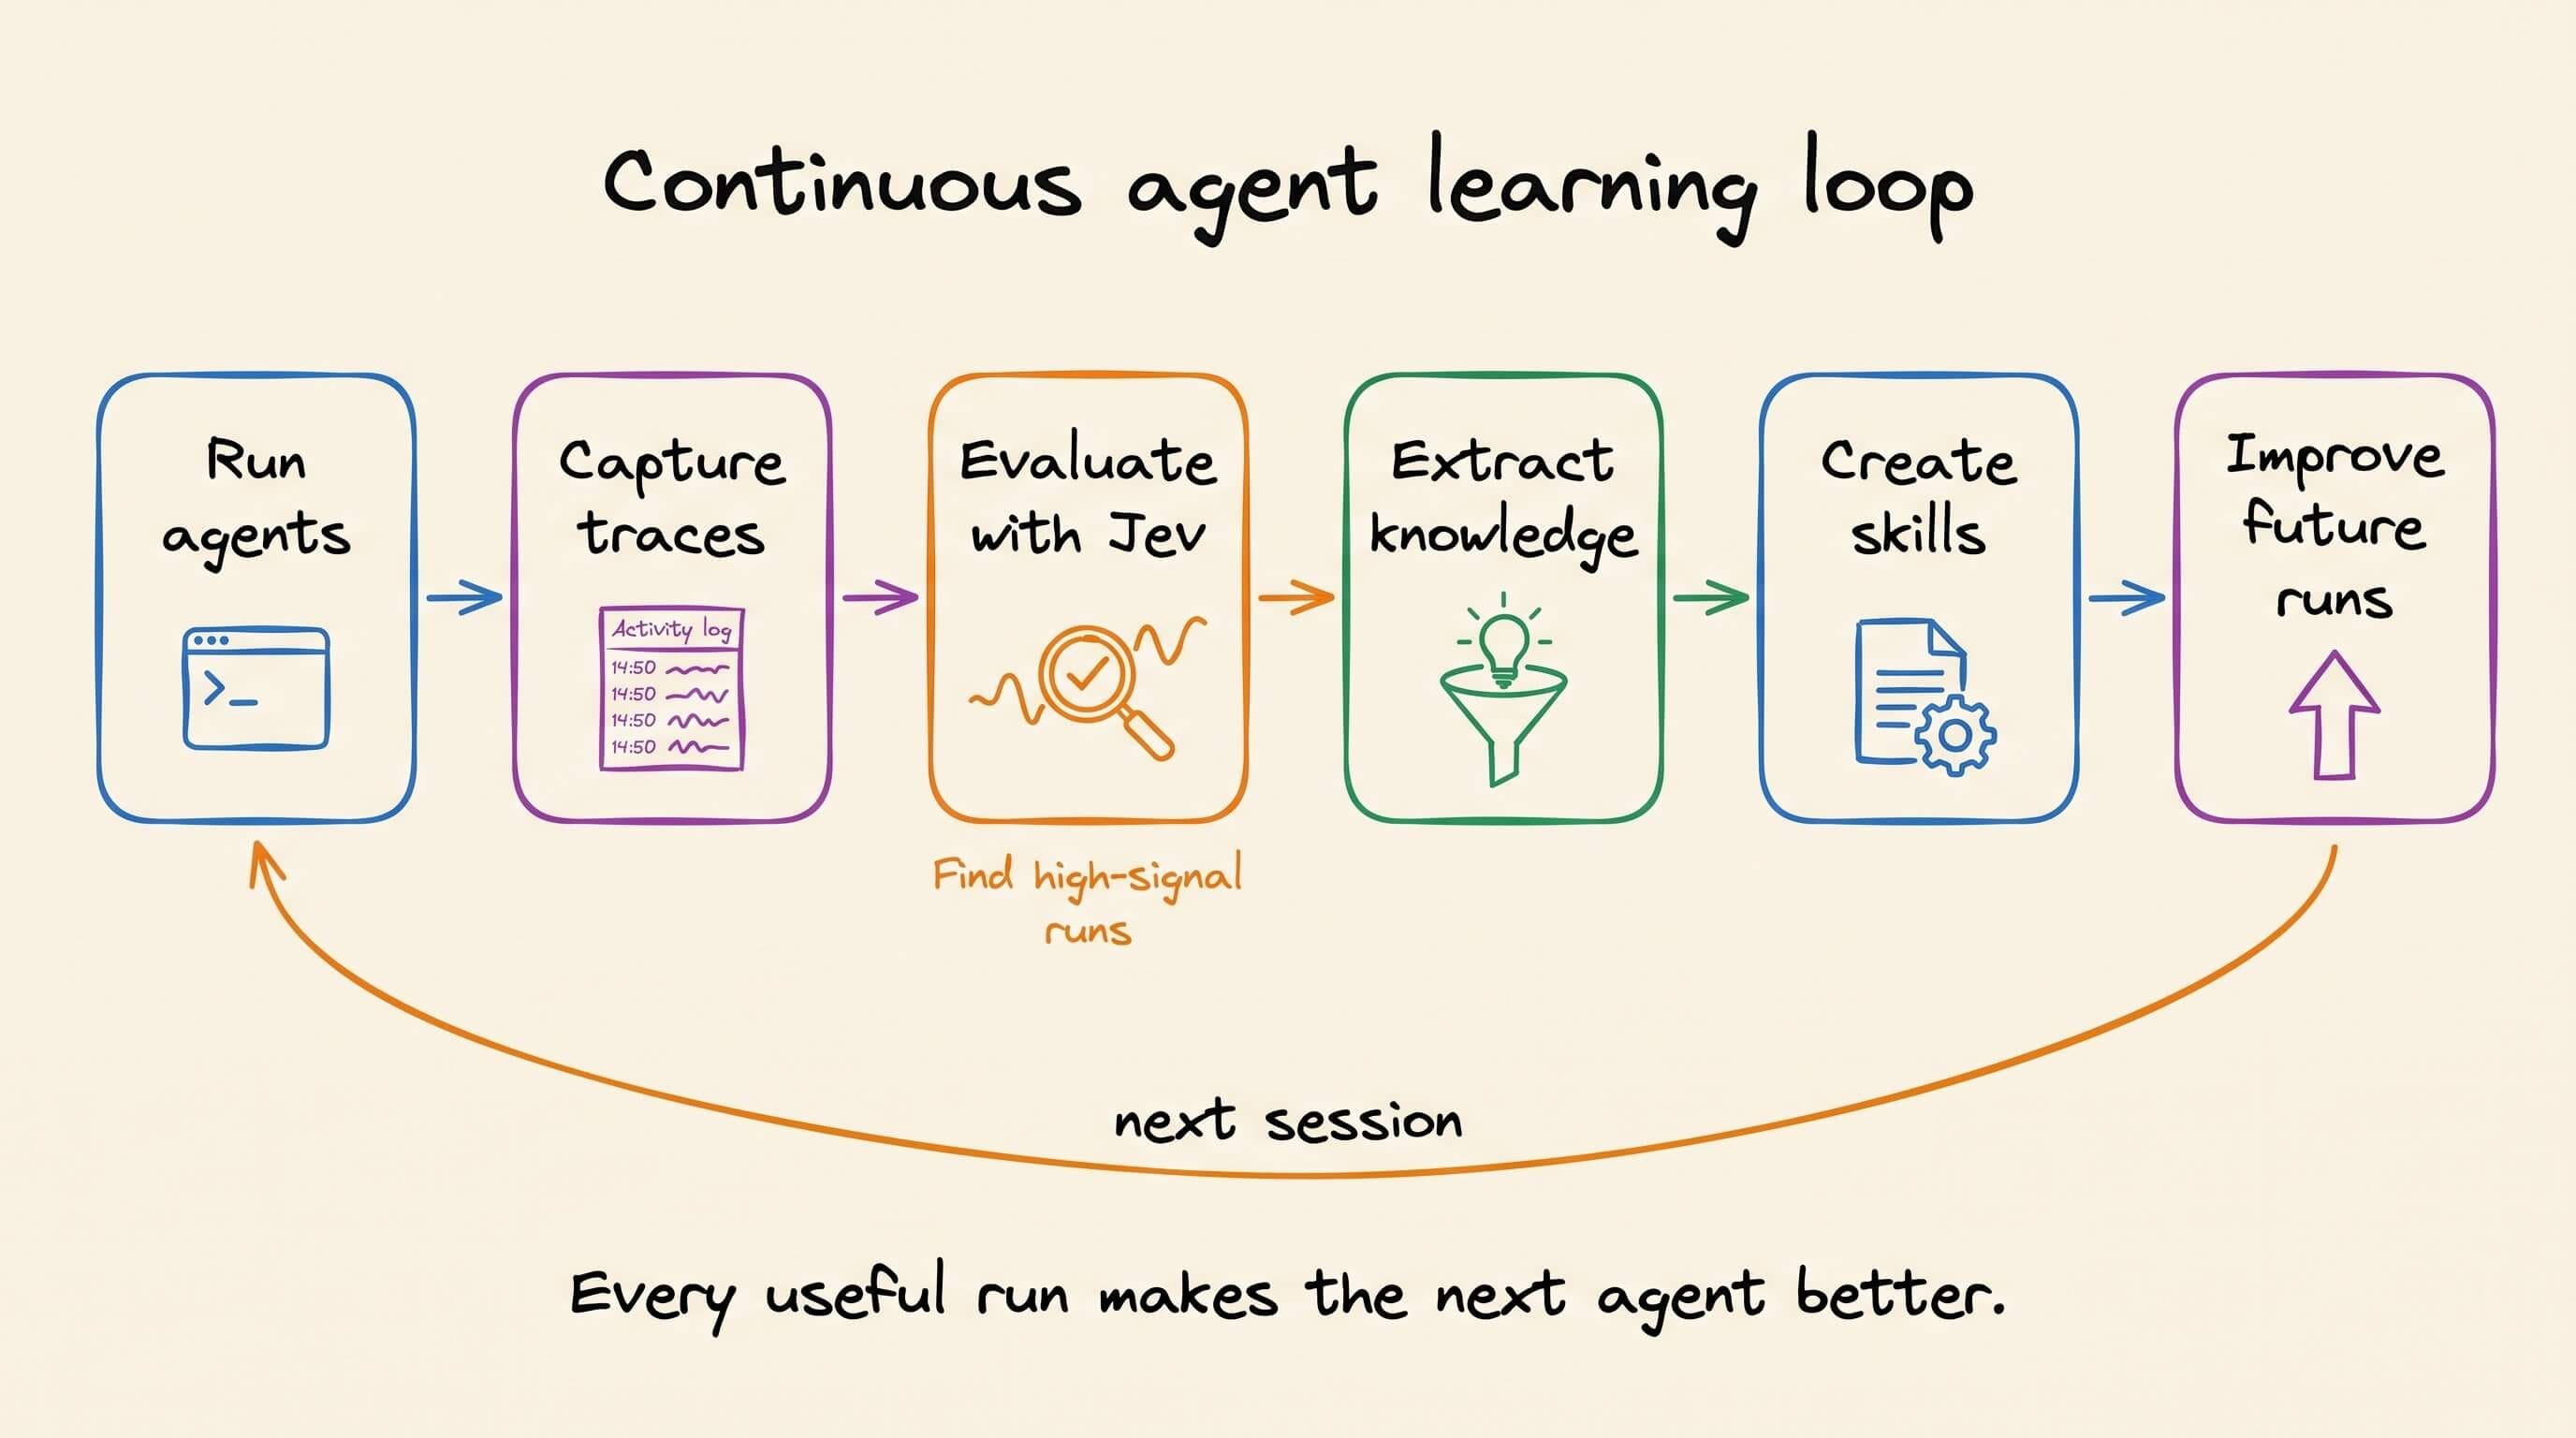
The loop looks like this:
Run agents → capture traces → evaluate with Jev → extract knowledge → create skills → improve future runs
Now imagine that across an entire engineering organization.
One engineer spends an hour debugging an obscure infrastructure issue. Normally, the useful parts of that work disappear into their terminal history, a Slack thread, or an agent transcript nobody else ever reads.
Beacon can turn that successful trace into reusable knowledge for the next engineer, regardless of which coding agent they use.
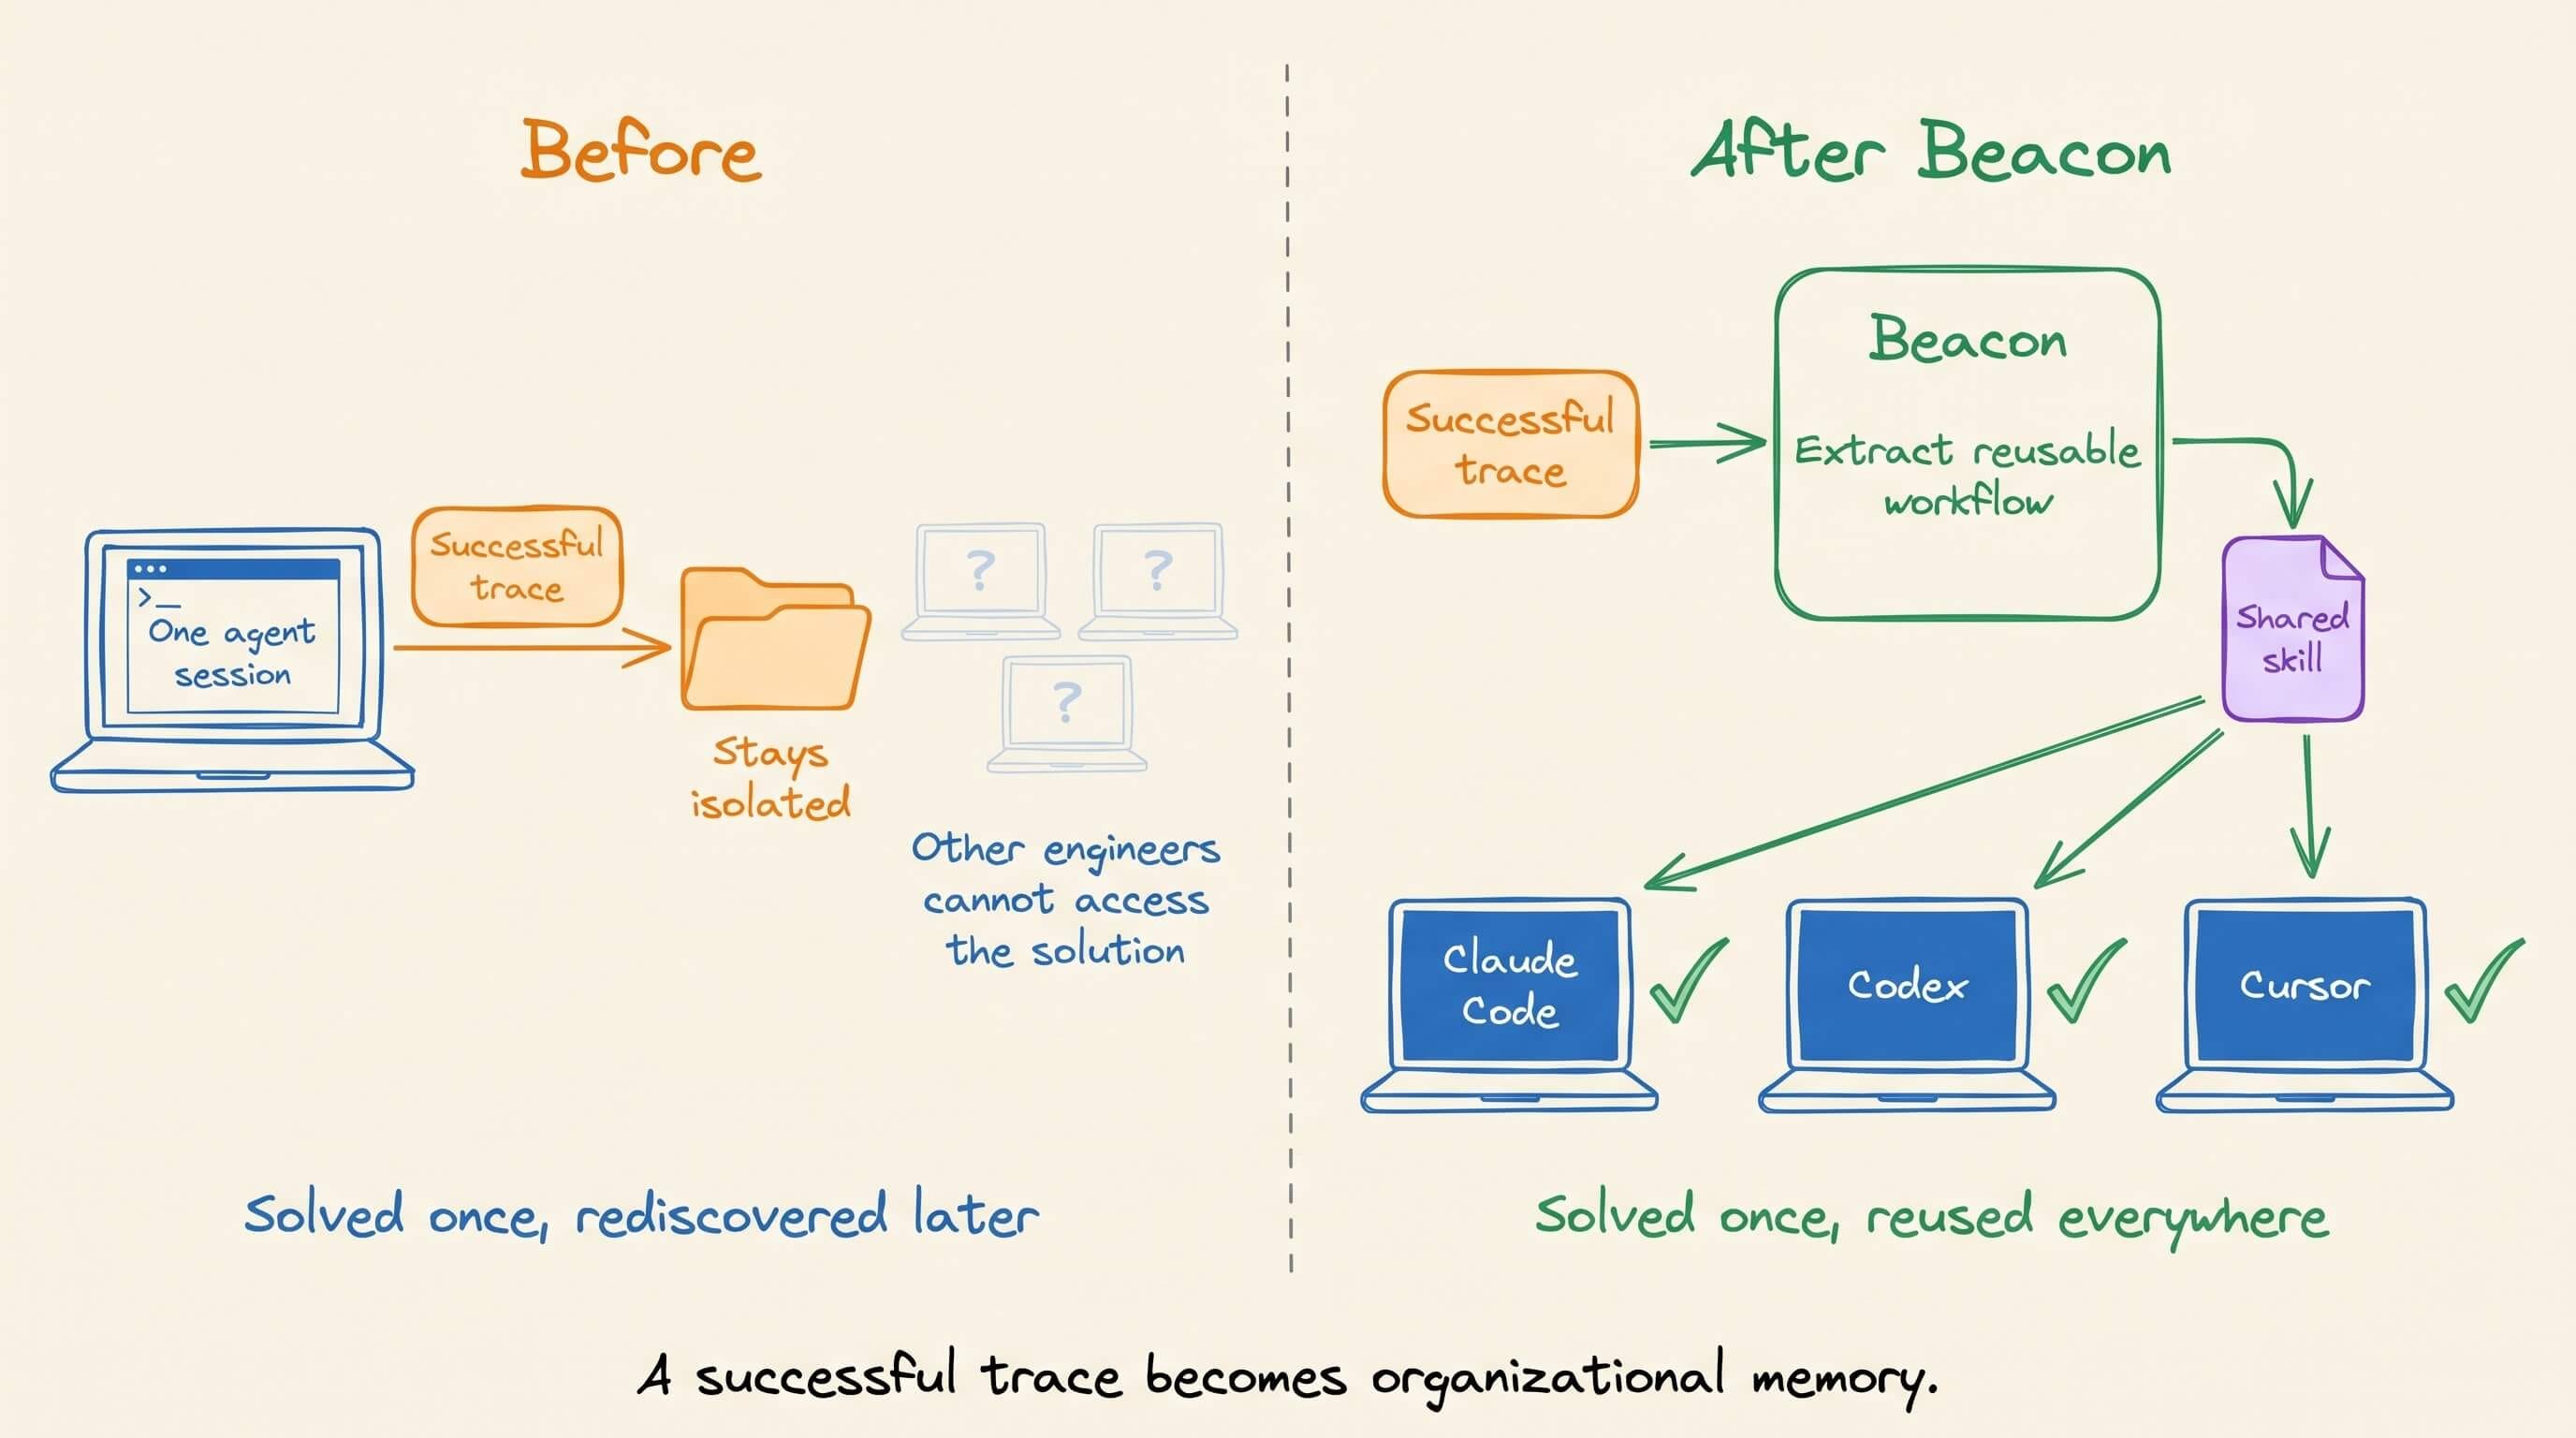
This turns agent traces into something closer to a continuously growing knowledge base for engineering work. And because Beacon supports multiple harnesses, the knowledge is not locked inside a single AI coding tool.
You can switch agents without throwing away everything your previous agents learned.
That is the core idea:
A problem solved by one agent never needs to be learned from scratch by another.
Jev makes it cheap to determine what is worth learning from.
Beacon makes that knowledge portable across every agent you use.
Beacon is fully open source, so you can try it with the coding agents you already use.
(don’t forget to star it ⭐️)
More on Jev below👇
Jev, clearly explained:
TypeSafe AI released Jev on September 15, 2026. It cannot hold a conversation, write code, or generate a useful paragraph. The narrow interface is the product.
Software makes thousands of small judgments: Is this ticket urgent? Which model should handle this request? Is this shell command dangerous? Teams often send each one to a general-purpose LLM, then parse and validate the generated answer.
Jev takes a different interface. Unstructured state goes in. Typed answers and probabilities come out. The relevant question is whether some LLM calls should have been bounded decisions in the first place.
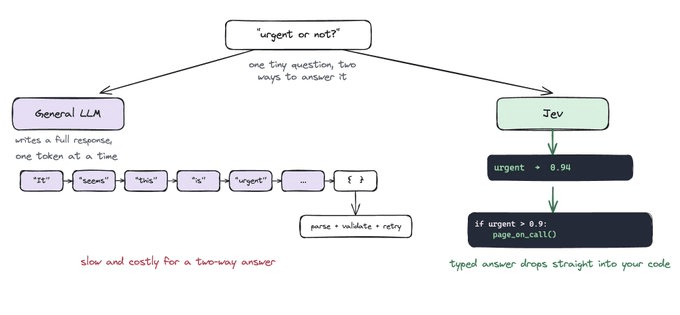
Let’s dive in to learn more!
Generation is expensive control flow
Tool calling and structured outputs removed a lot of brittle parsing, but the model underneath is still generative.
Even when the answer is one word, such as “billing”, it produces tokens sequentially.
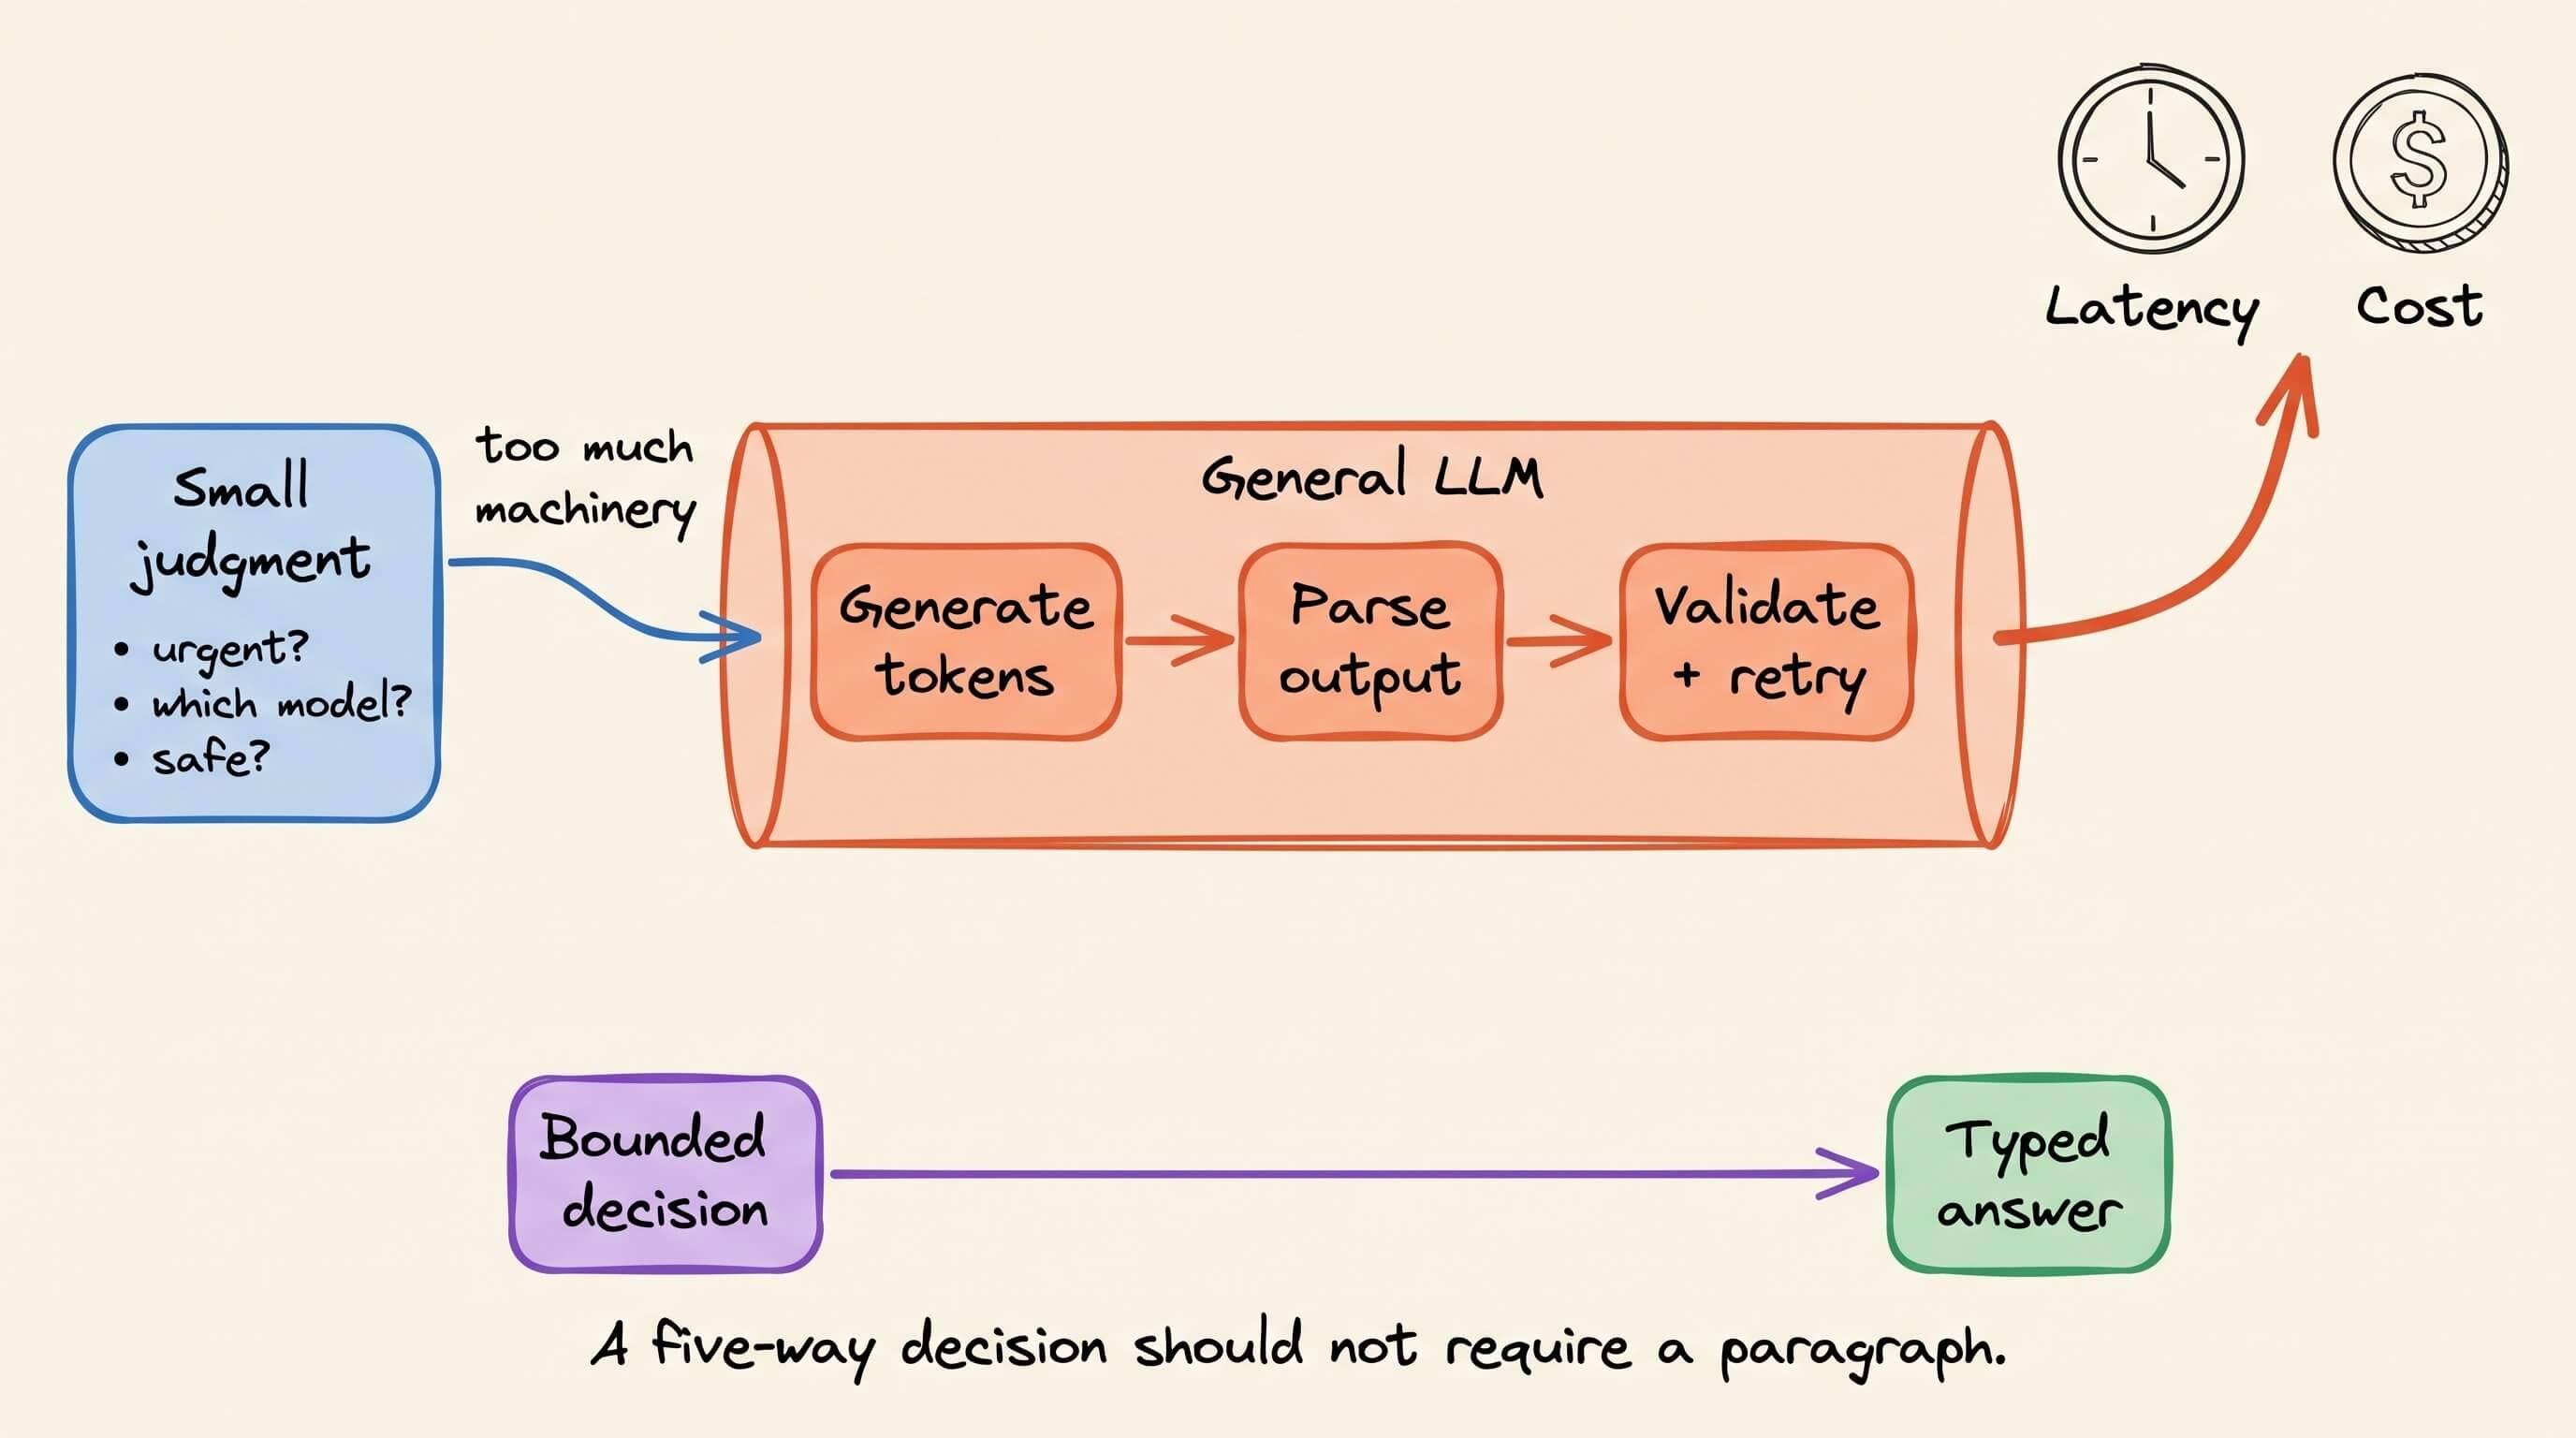
Now put that inside an agent loop.
while not done:
    action = llm(context)
    result = run_tool(action)
    context += result
One agent run may call the model repeatedly to select tools, detect risk, judge results, and decide when to stop. These calls require judgment, not prose. Jev targets them directly.
The interface: state, typed questions, and distributions
Jev is a semantic decision engine. You send it two things:
State, which is the text or JSON that describes the current situation.
Questions, which are the decisions you want it to make about that state.
Every question declares its answer shape in advance. Jev supports three primitives:
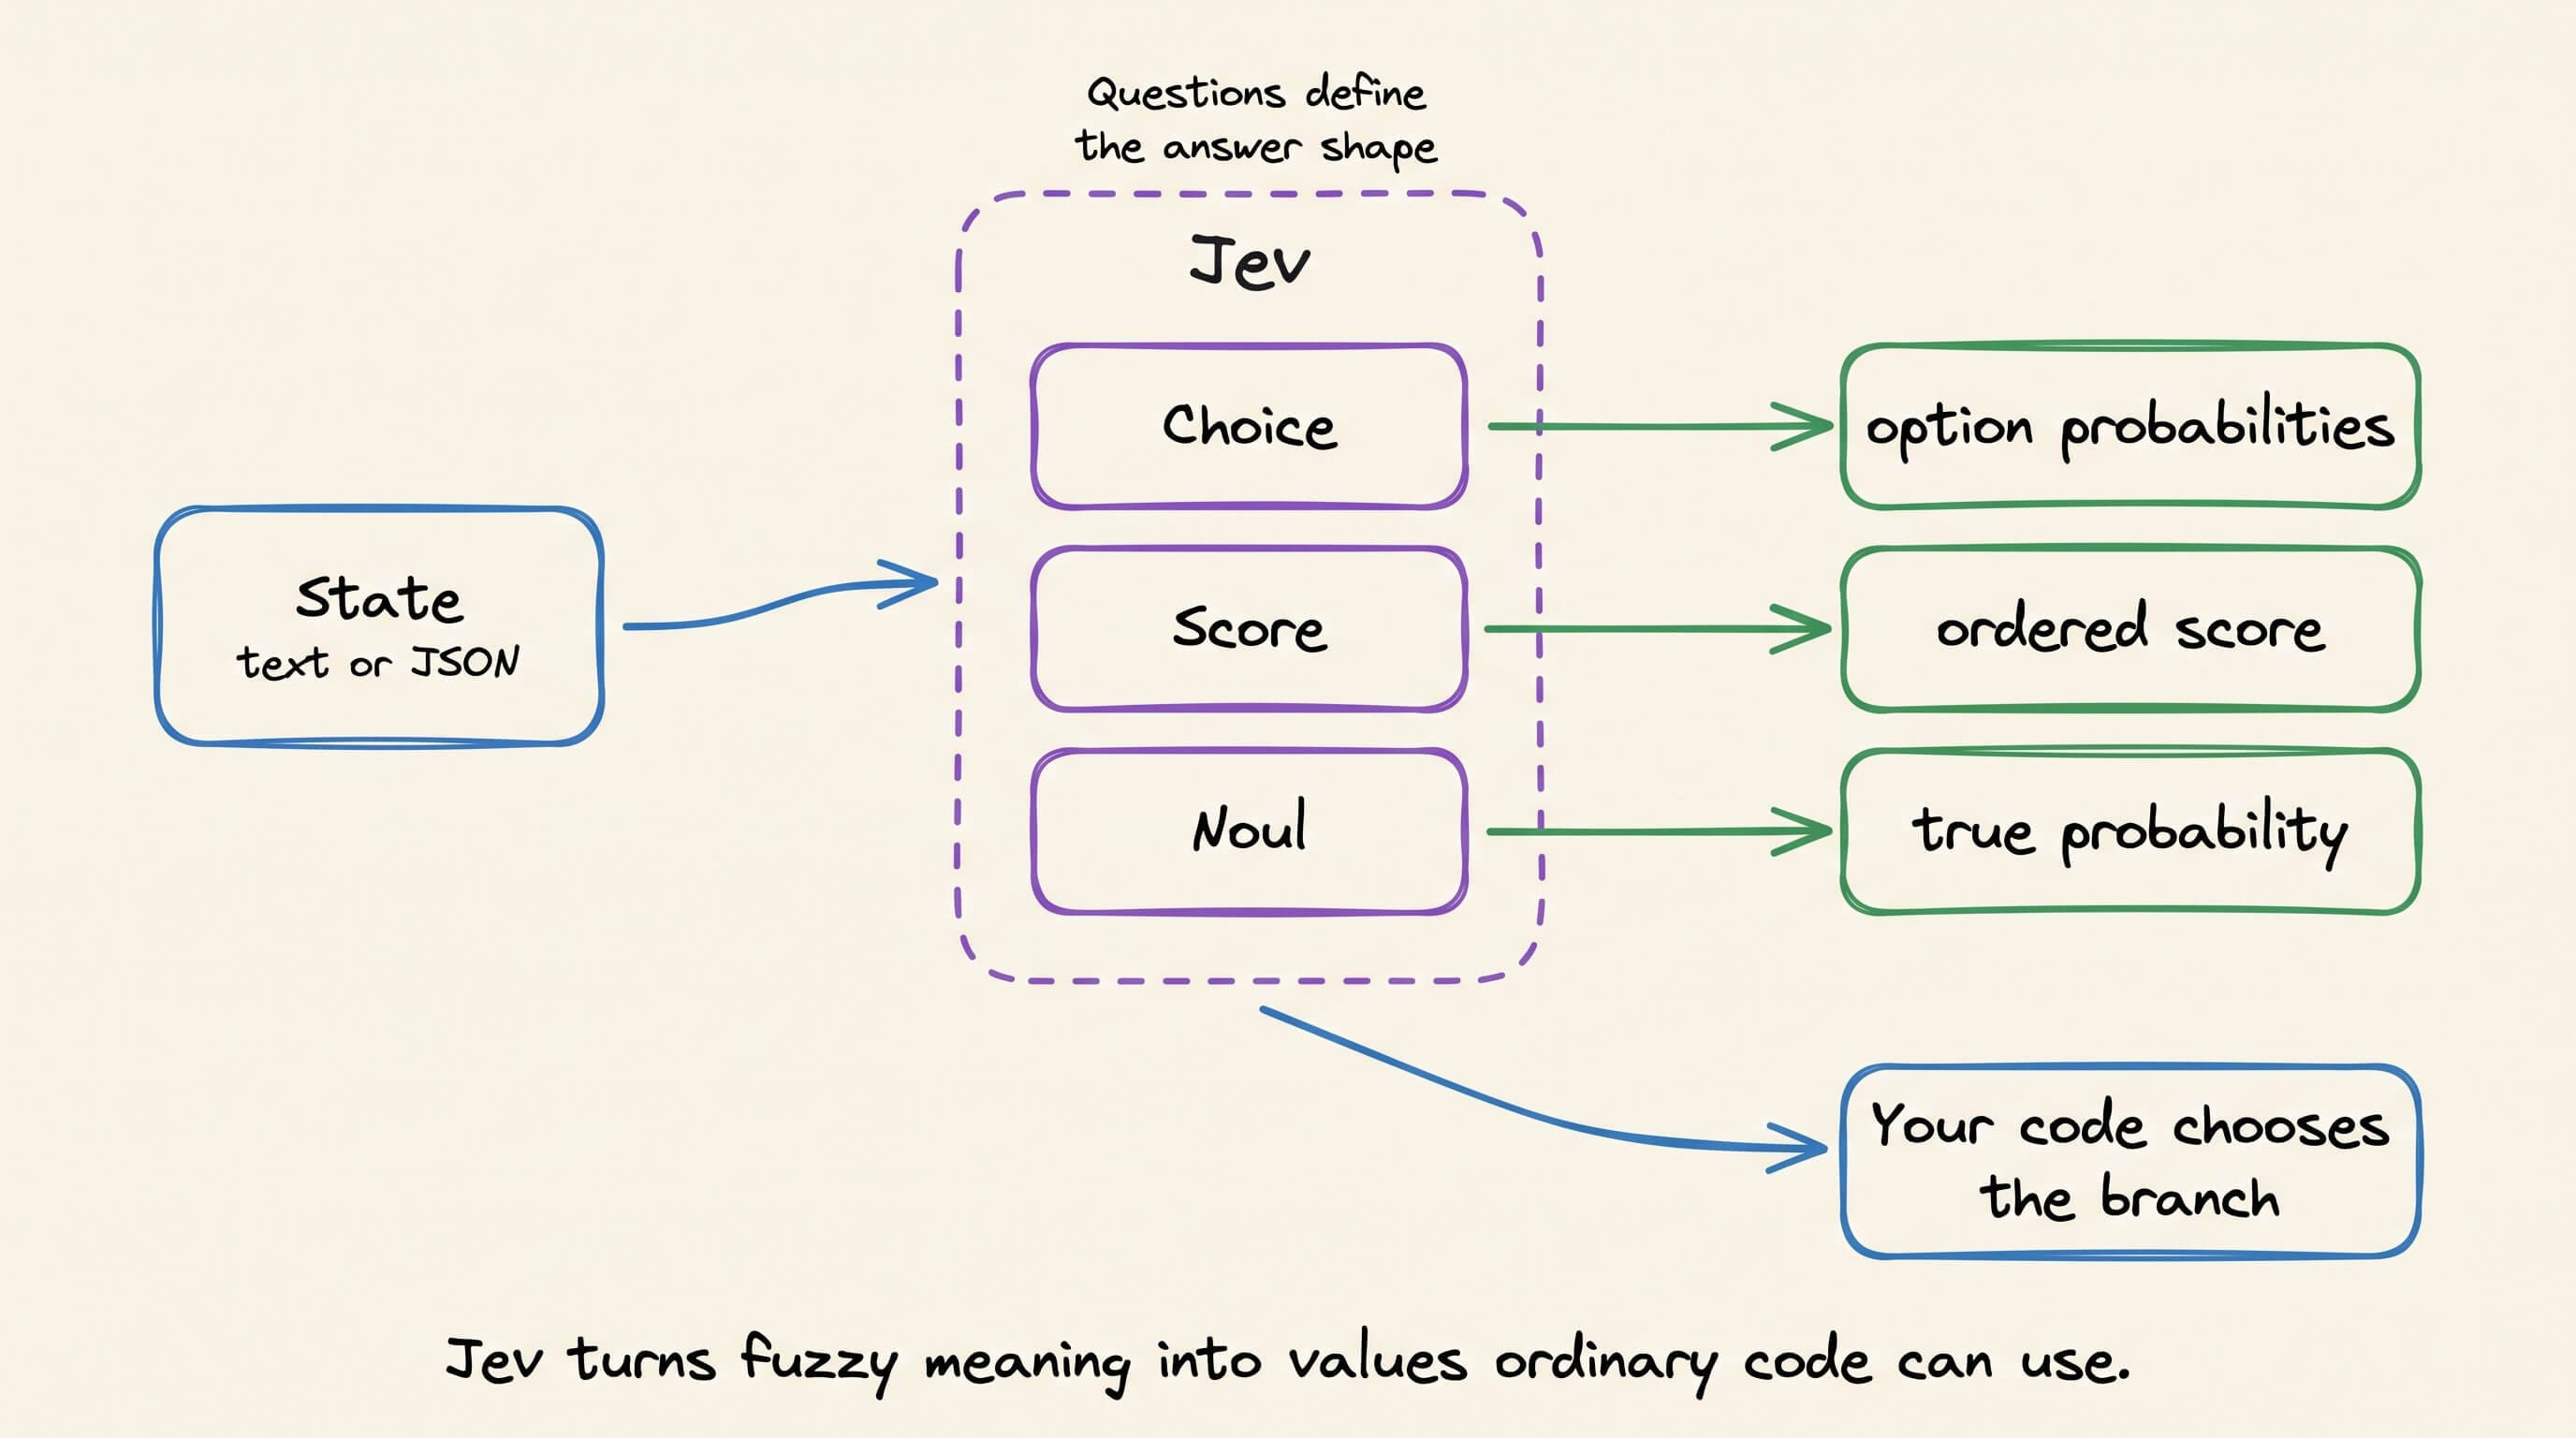
Choice picks one option from a list and returns a probability for every option.
Score places the input on an ordered scale such as low, medium, and high.
Noul answers a yes-or-no question by returning the probability that it is true.
Noul is TypeSafe’s name for its Boolean decision type. It returns a number between 0 and 1.
{
  "model": "jev-latest",
  "state": "The deploy failed twice and customers are seeing 500s.",
  "questions": {
    "urgent": {
      "type": "noul",
      "instructions": "Does this need attention right now?"
    },
    "owner": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "engineering": "Product failures and outages",
        "billing": "Charges, invoices, and refunds",
        "sales": "Pricing and new accounts"
      }
    }
  }
}
The response contains an urgency probability and a distribution over the three teams. The schema prevents undeclared answers, but it cannot repair a bad taxonomy. If billing and engineering overlap in the rubric, Jev must choose between ambiguous categories.
Your program keeps control:
if urgent > 0.9 and owner == "engineering":
    page_on_call()
elif confidence < 0.6:
    send_to_human_review()
else:
    add_to_queue(owner)
Code owns the branches. Jev estimates which branch matches language that cannot be reduced to exact conditions.
TypeSafe says Jev evaluates questions in parallel. That helps when the questions are independent. If one answer determines the next question, keep that dependency in code rather than evaluating unused branches.
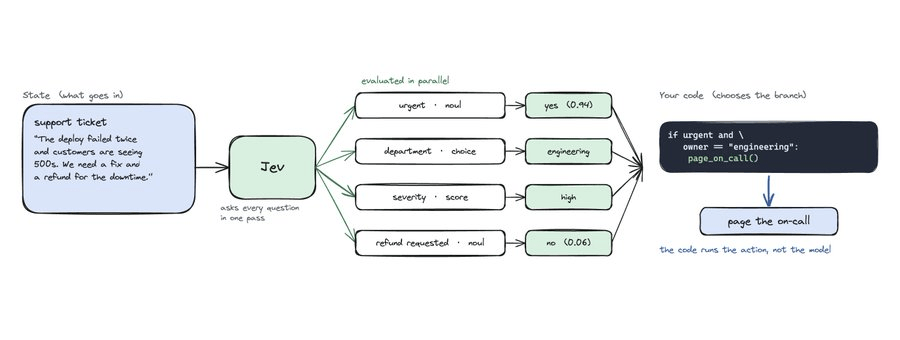
The company reports latency of 70 to 500 milliseconds and a price of $0.042 per million input tokens, with no charge for output. Its claims of up to 200 times lower latency and 400 times lower cost come from favorable internal comparisons, not production capacity data.
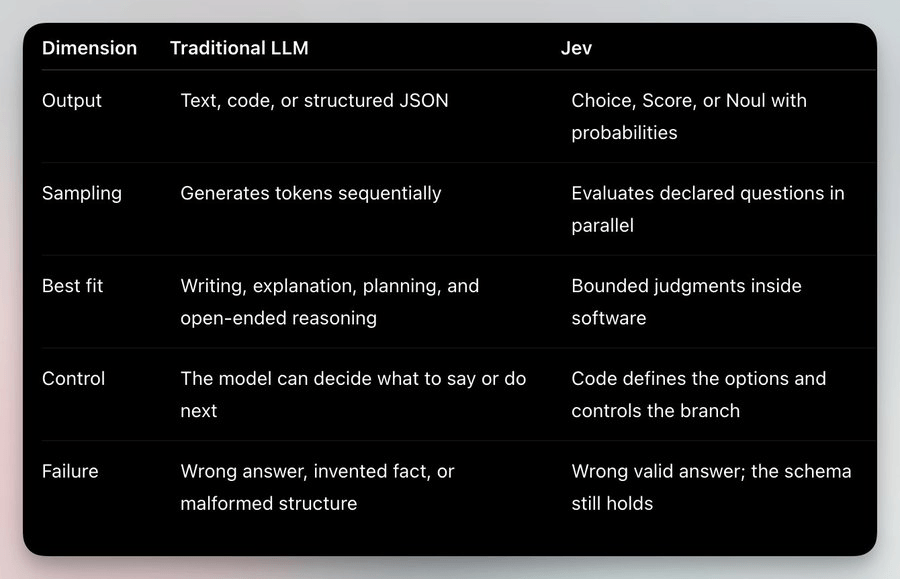
Scoring fixed outcomes avoids token generation, output parsing, and some retries.
Why confidence exists in control flow
Suppose Jev routes a ticket to billing. The label tells you what won. The distribution tells you how close the race was.
{
  "choice": "billing",
  "probabilities": {
    "billing": 0.52,
    "technical": 0.46,
    "sales": 0.02
  },
  "confidence": 0.18
}
Billing won by six points. Automatic routing would be reckless.
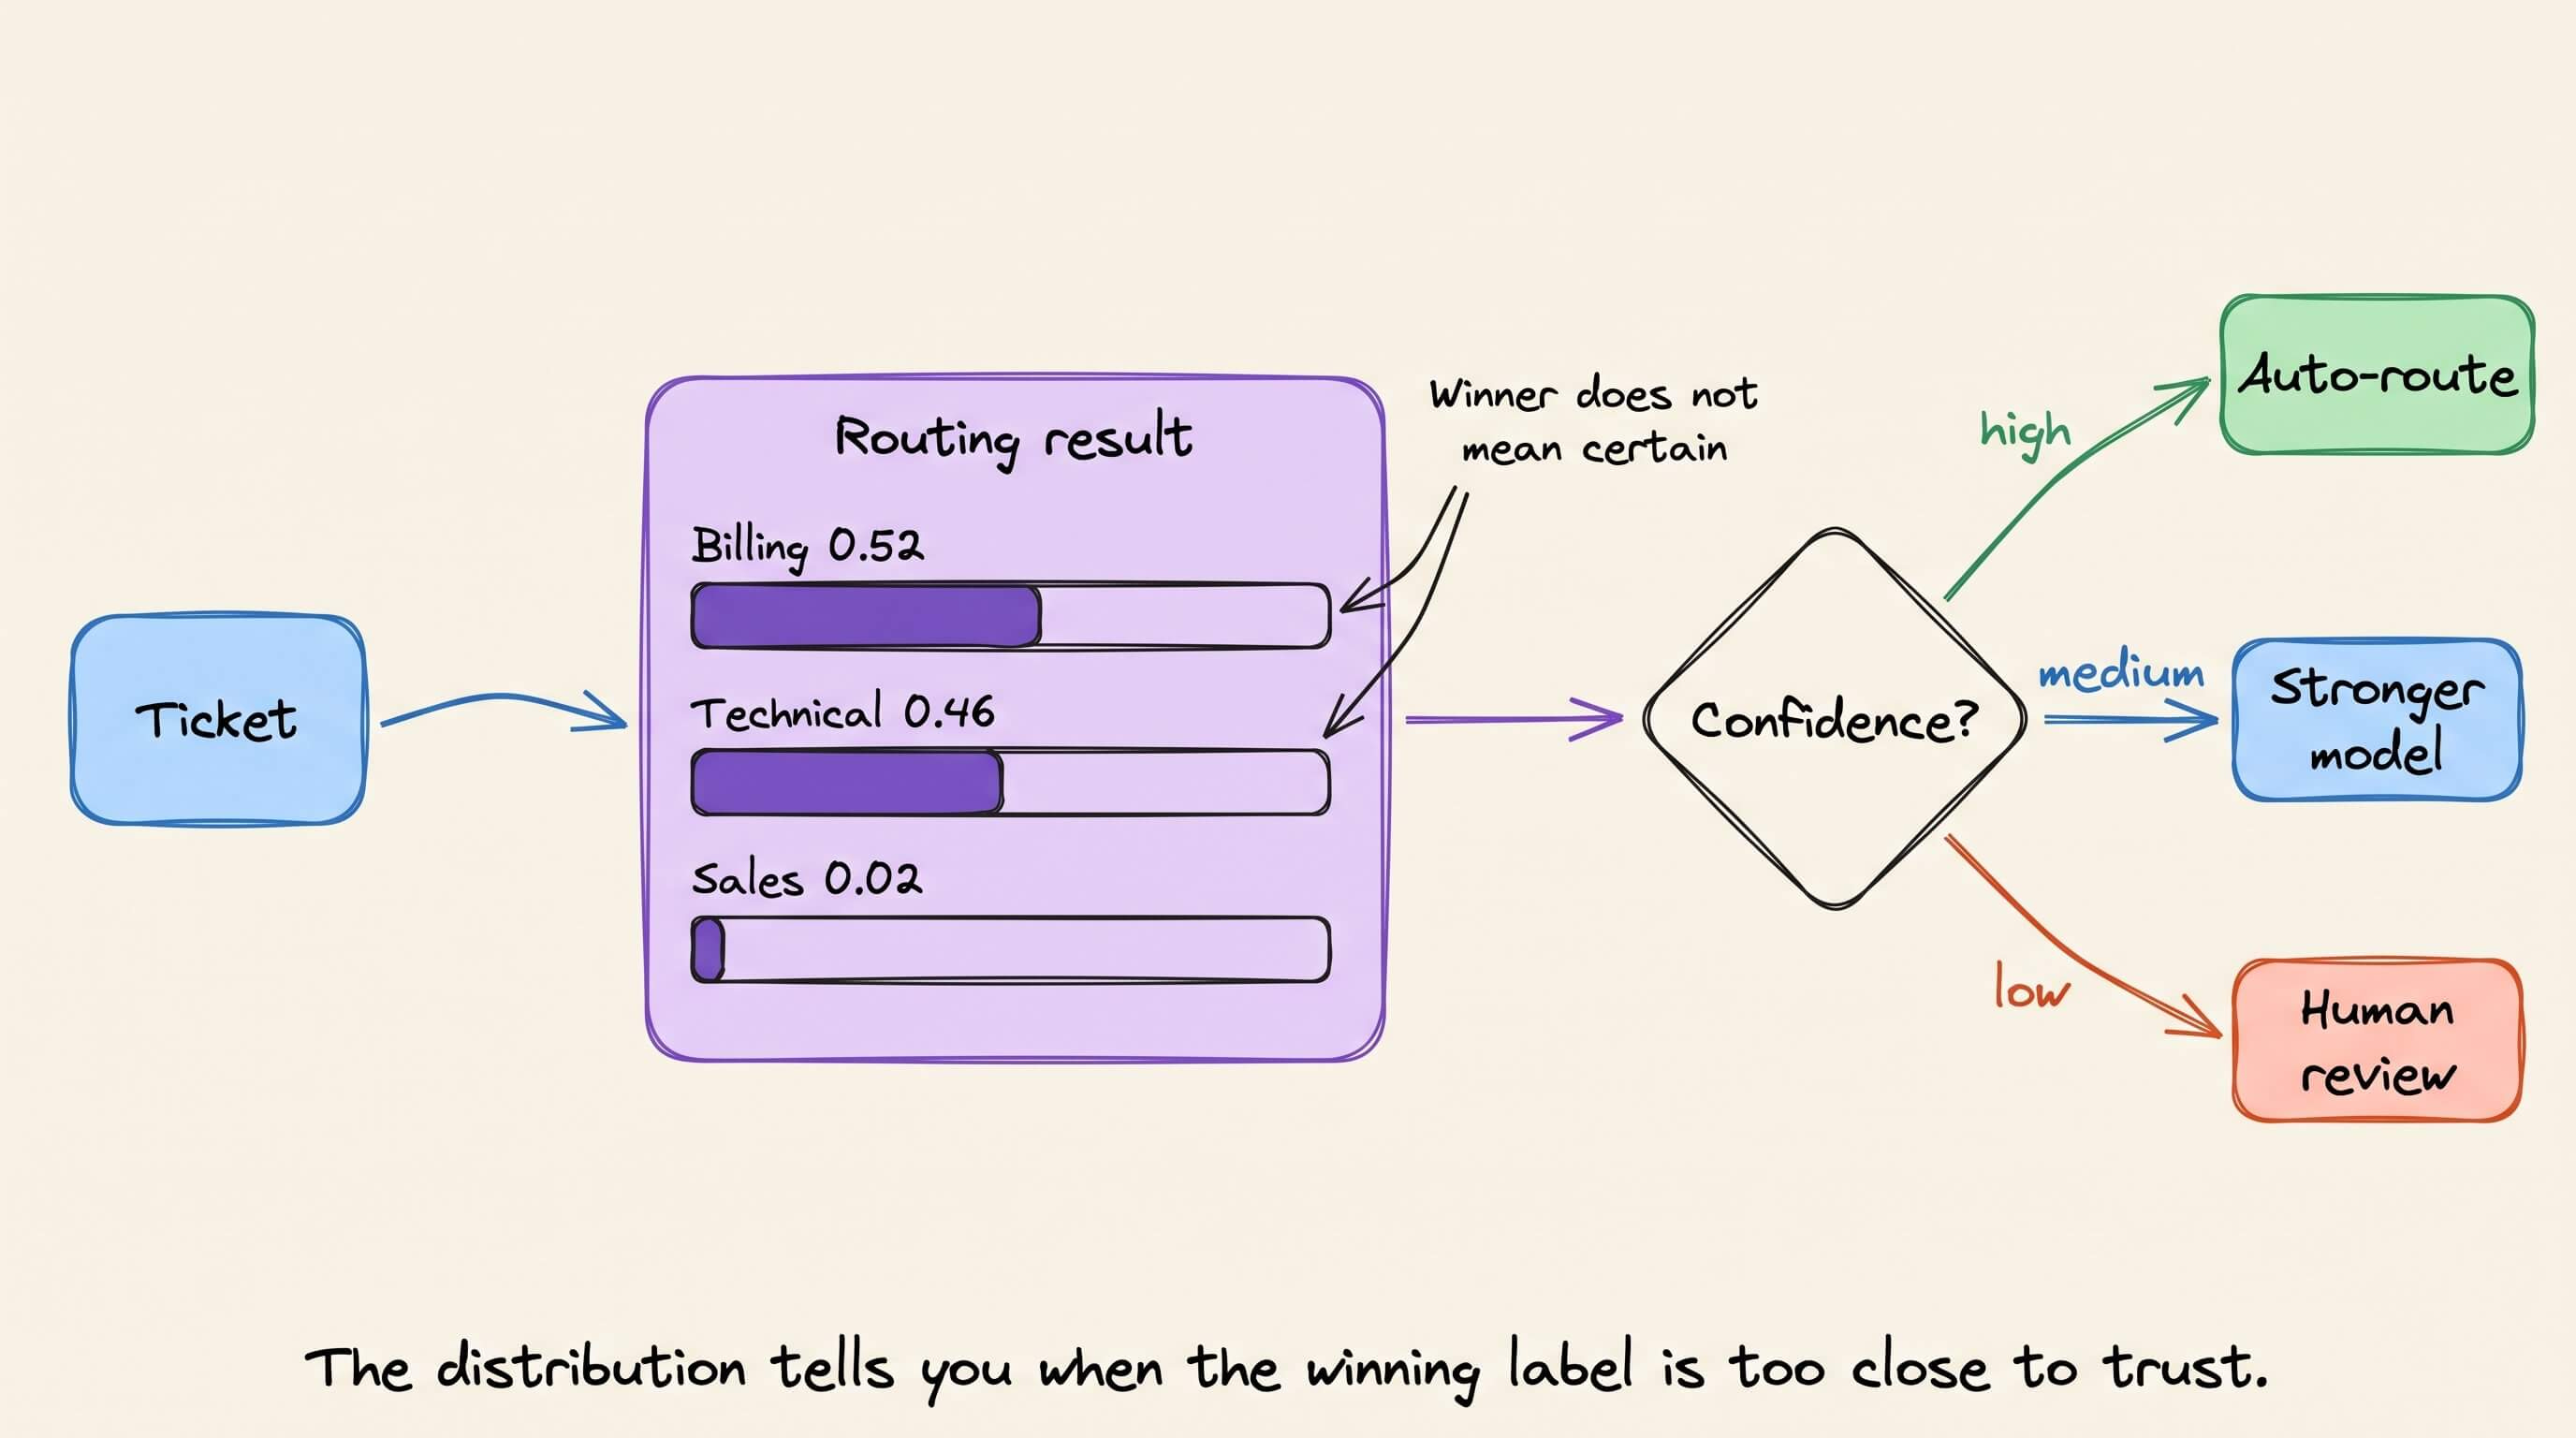
The application needs an abstention policy in addition to a winning label:
Act automatically when confidence is high and the consequence is small.
Ask for confirmation or call a stronger model when confidence is middling.
Send the case to a person or gather more information when confidence is low.
Thresholds belong in code and should reflect consequence. A dashboard label can tolerate weaker evidence than a command that deletes data.
TypeSafe trains Jev using Reinforcement Learning for Calibrated Decisions, or RLCD, so predicted confidence should track observed accuracy. That relationship must hold on your traffic. Measure it separately for each decision type and recheck it after changes to the model, questions, or input distribution.
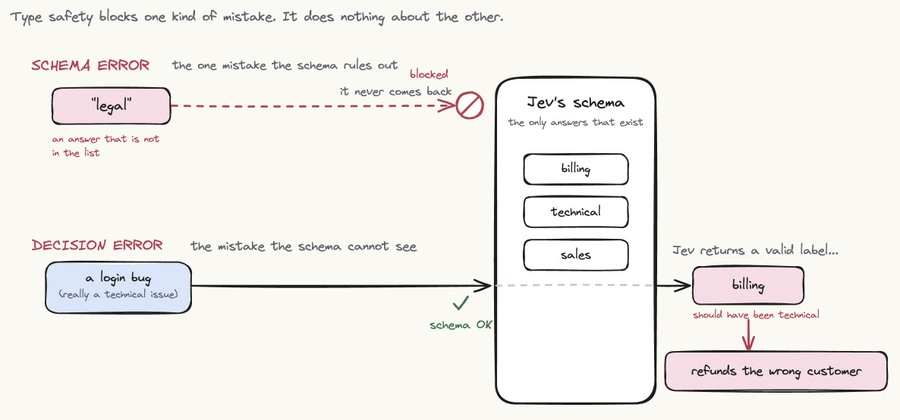
TypeSafe also says Jev cannot hallucinate. More precisely, it cannot break the declared output schema. It can still choose the wrong valid option with high confidence. Type safety prevents malformed output, not bad judgment.
Using Jev inside an agent
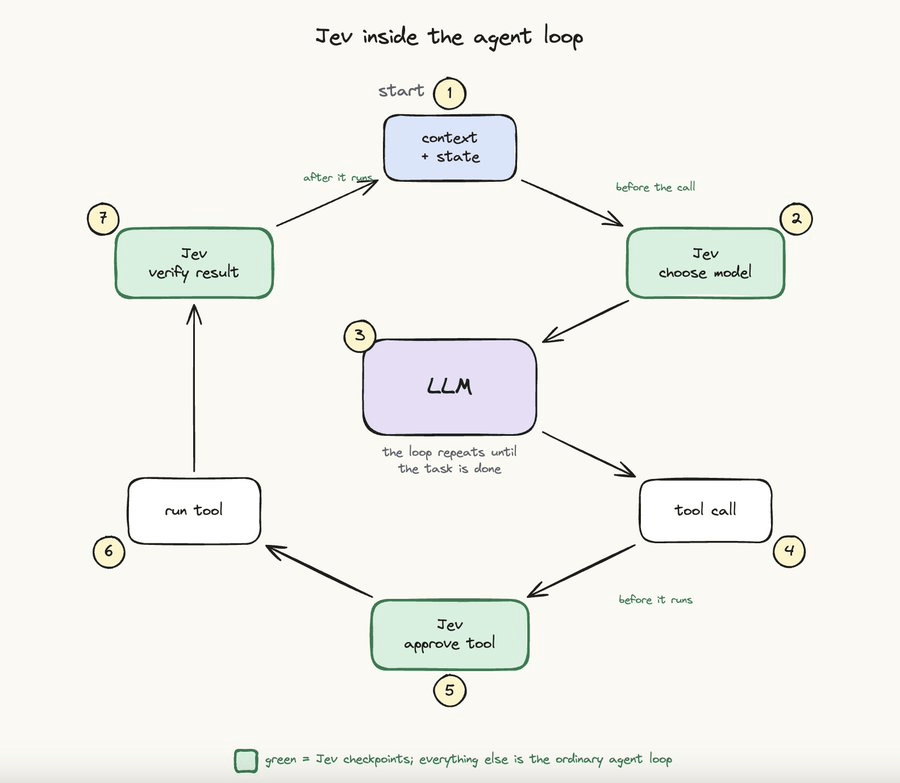
Jev belongs beside an LLM. The LLM plans, writes, explains, and uses tools. Jev handles repeated decisions around that work.
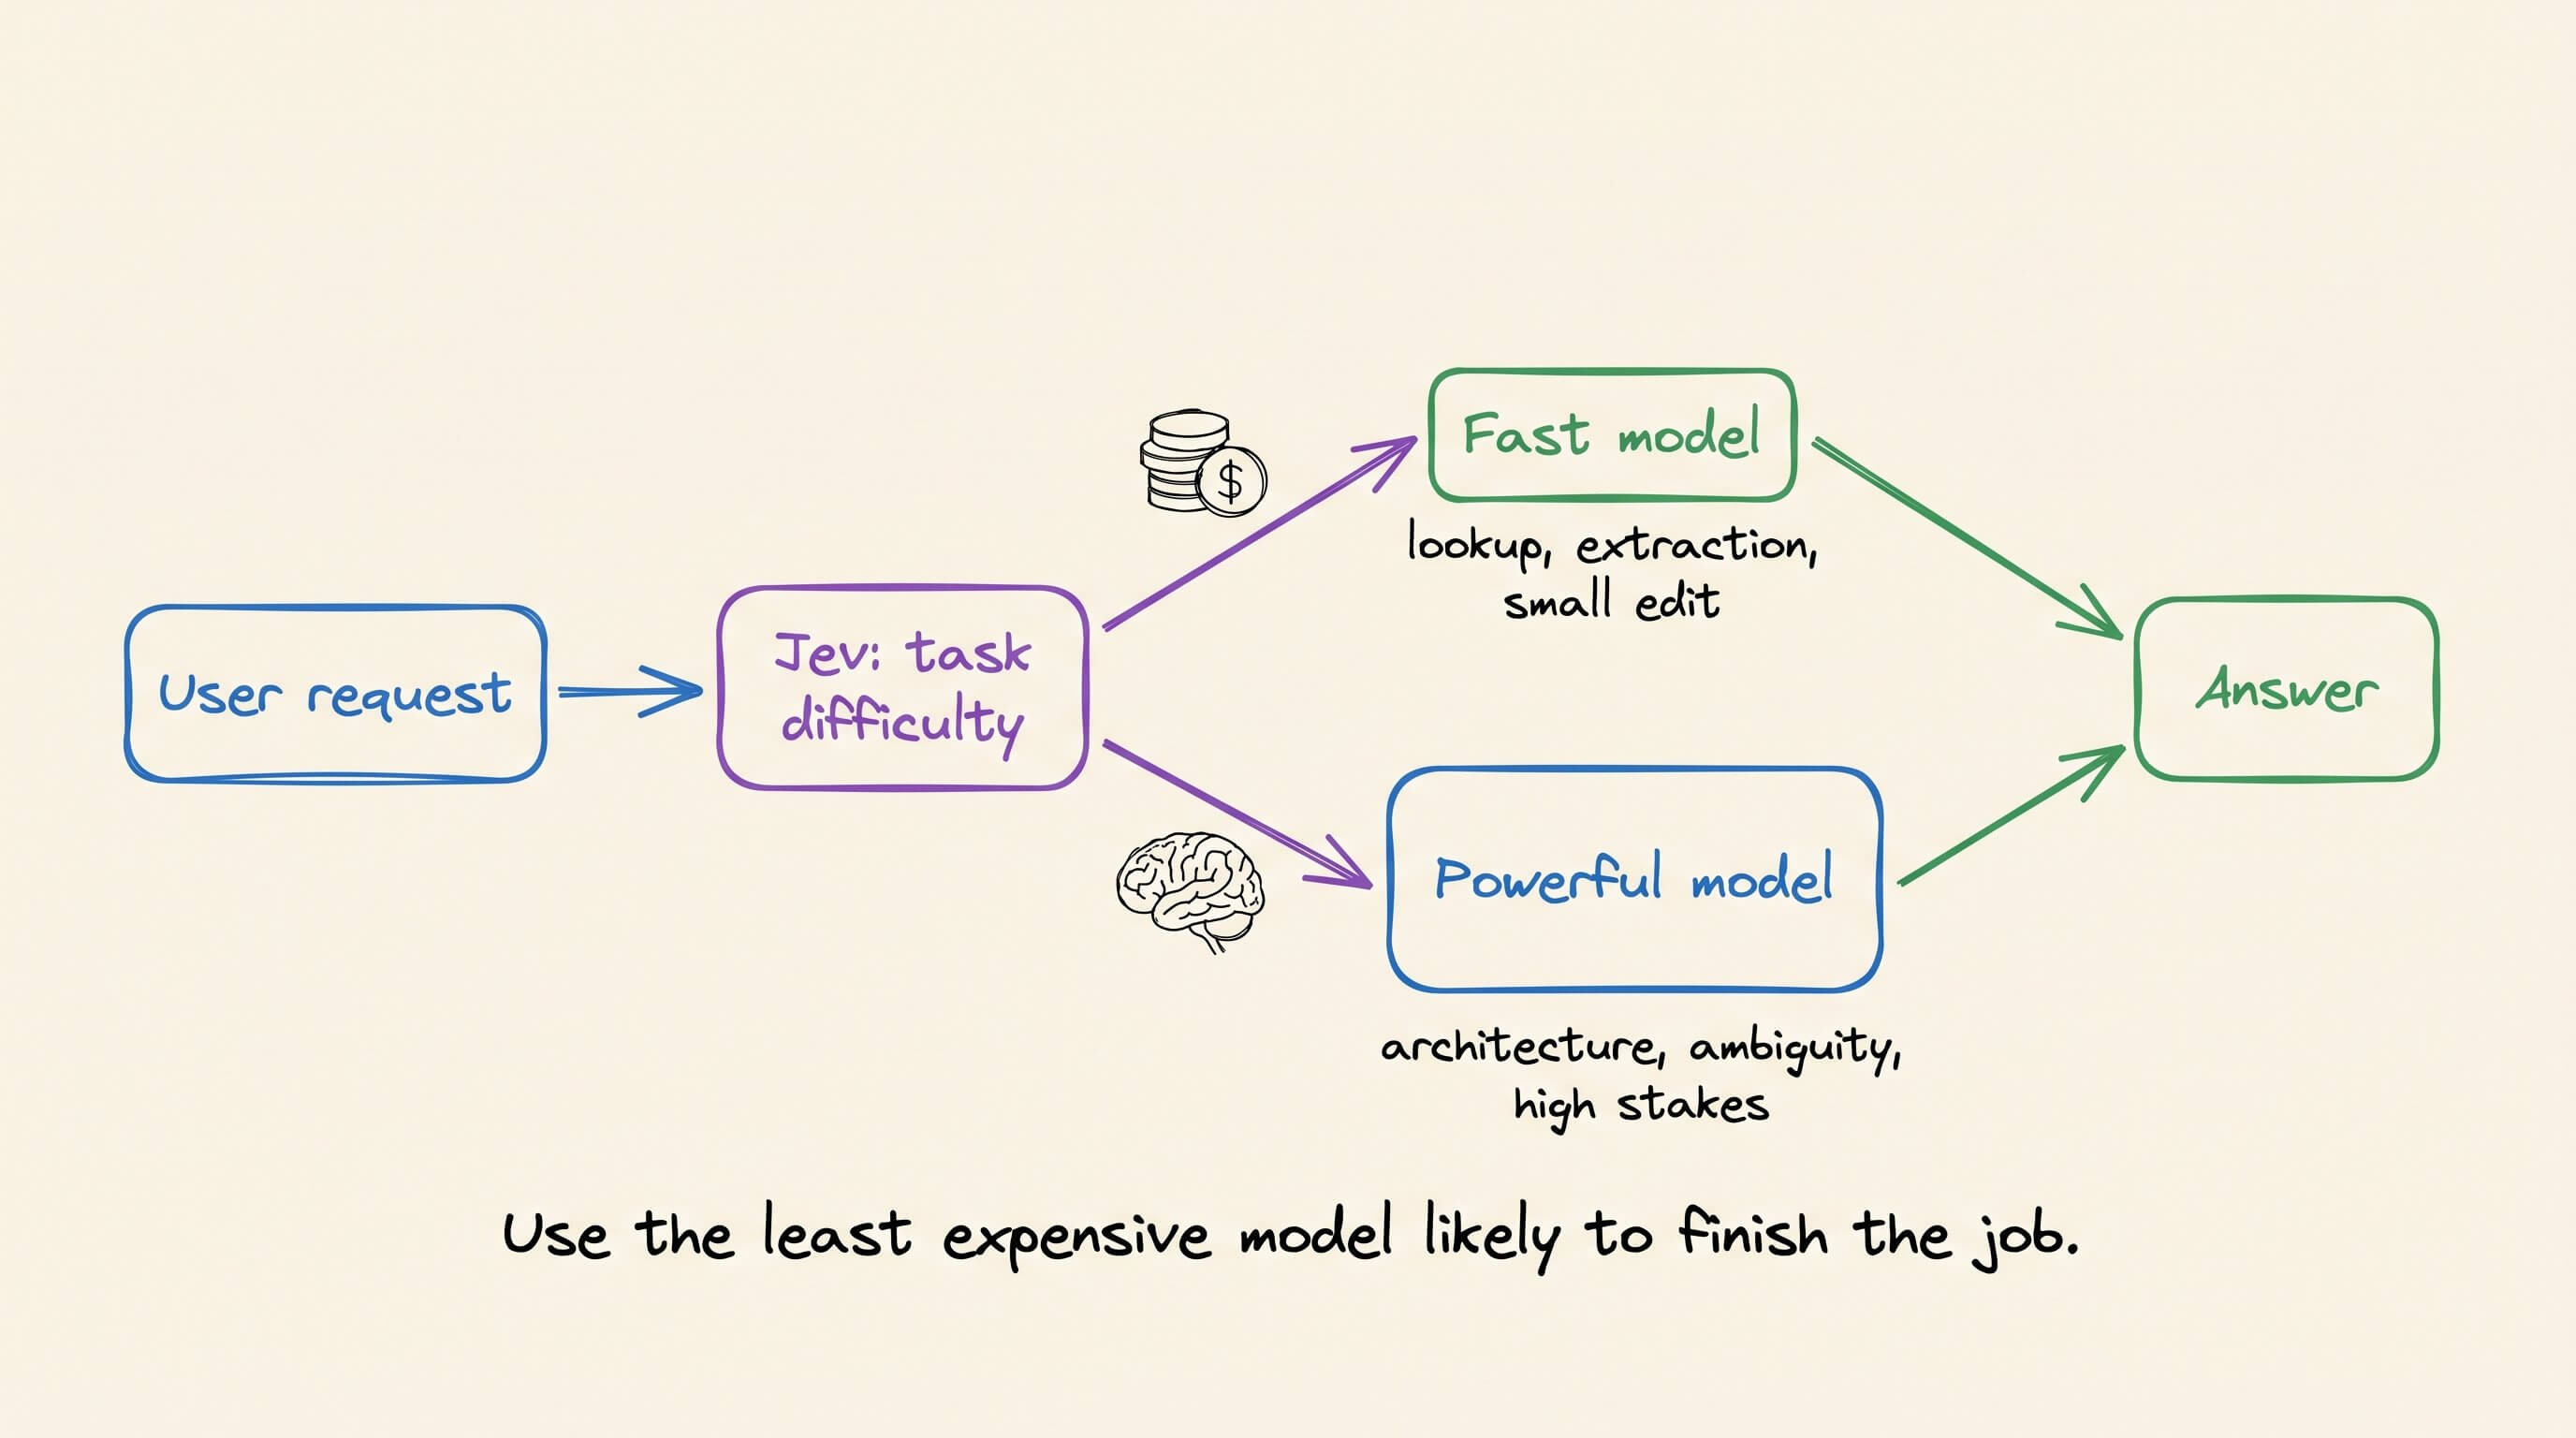
1) Model routing
A simple lookup does not need the same model as an architecture review. Jev can score a request and choose the least expensive model likely to complete it.
route = jev.choice(
    state=user_request,
    options={
        "fast": "Lookups, extraction, and small local edits",
        "powerful": "Architecture, ambiguity, and high-stakes work",
    },
)

model = fast_model if route == "fast" else powerful_model
The router chooses a model. It does not answer the request.
Pre-execution tool risk classification
Before an agent runs a shell command, Jev can classify it as read-only, reversible, or destructive. Separate questions can check whether it deletes files, changes Git history, touches production, or leaves the repository.
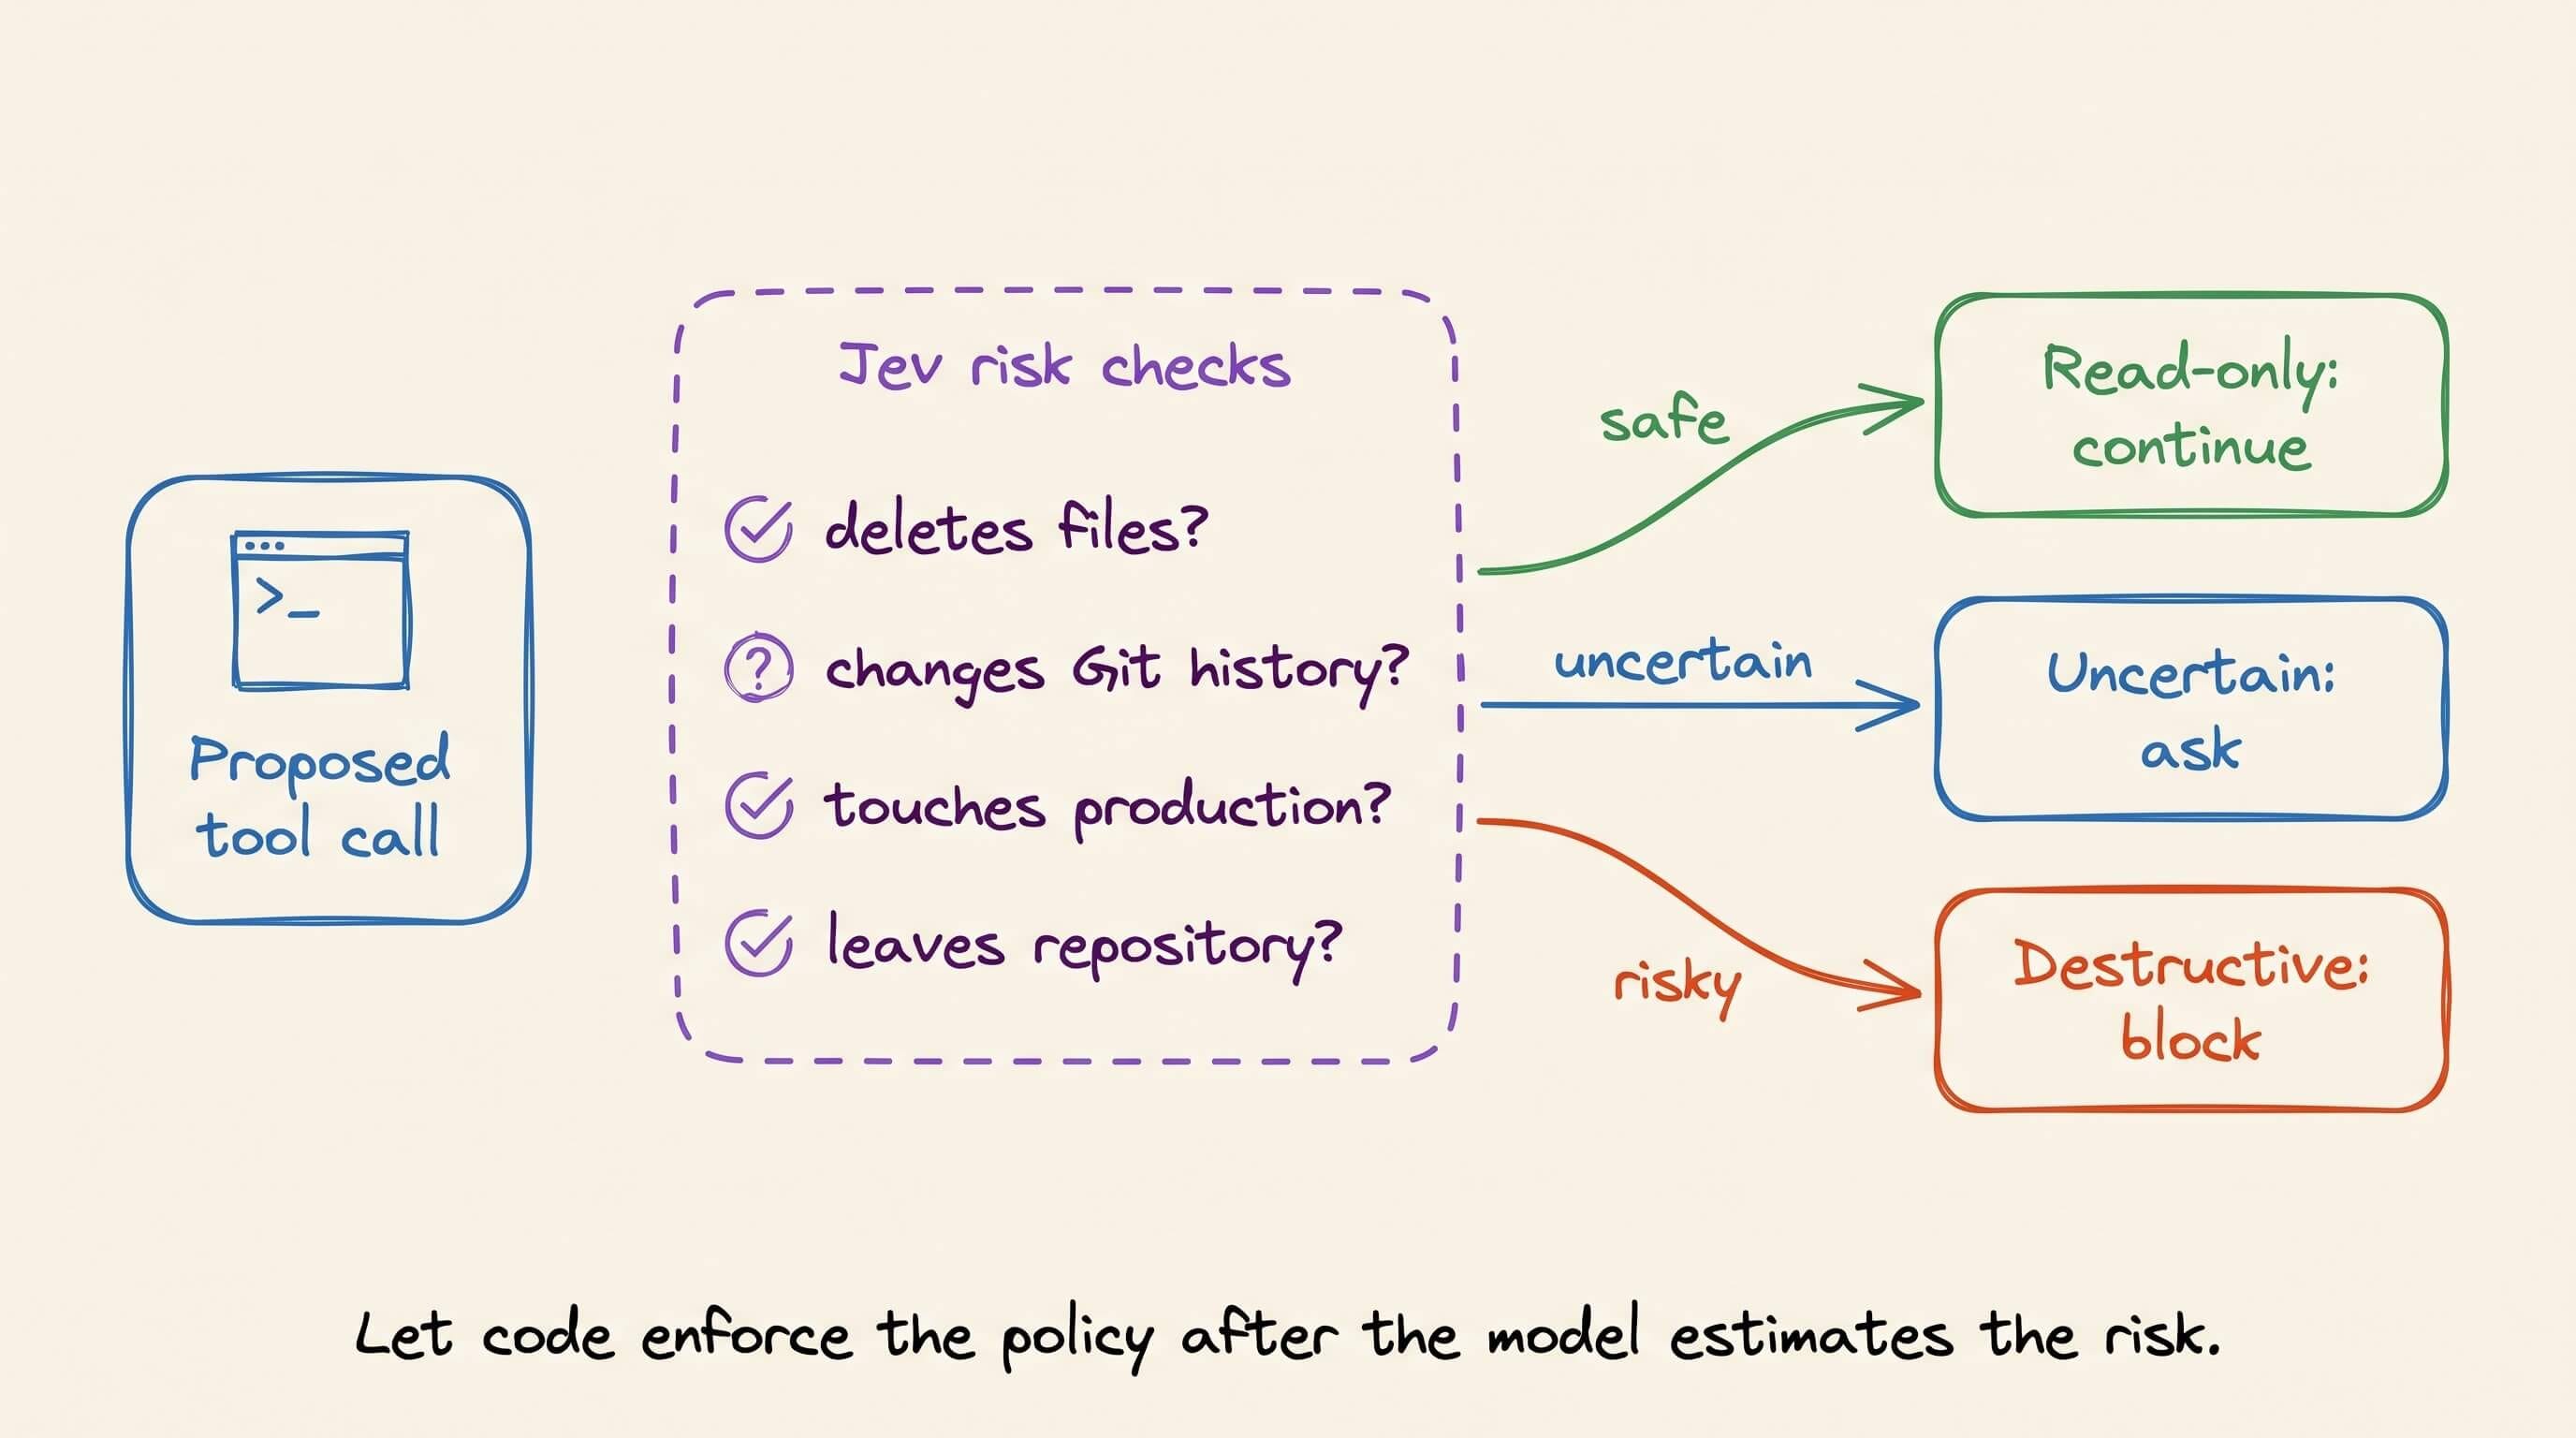
High-confidence read-only actions can continue. Destructive or uncertain actions pause for approval. LangChain’s Jev integration implements this check in middleware.
Post-execution semantic checks
Jev can check whether an agent is repeating itself, whether an output follows policy, or whether a result needs review. It should never replace a hard test. Use it only where the rule depends on meaning.
Problems Jev can solve
A workload is ideal when its output set is closed, a reviewer can label examples quickly, and the decision occurs often enough to justify another model dependency.
1) Request classification and routing
Jev can classify intent, urgency, department, spam, and customer frustration. One request can score several properties of the same ticket, while code combines the results into the routing policy.
2) Retrieval relevance and citation support
Embeddings retrieve related text. They do not establish that a passage answers the query or supports a claim. Jev can score those conditions before generation and remove irrelevant context.
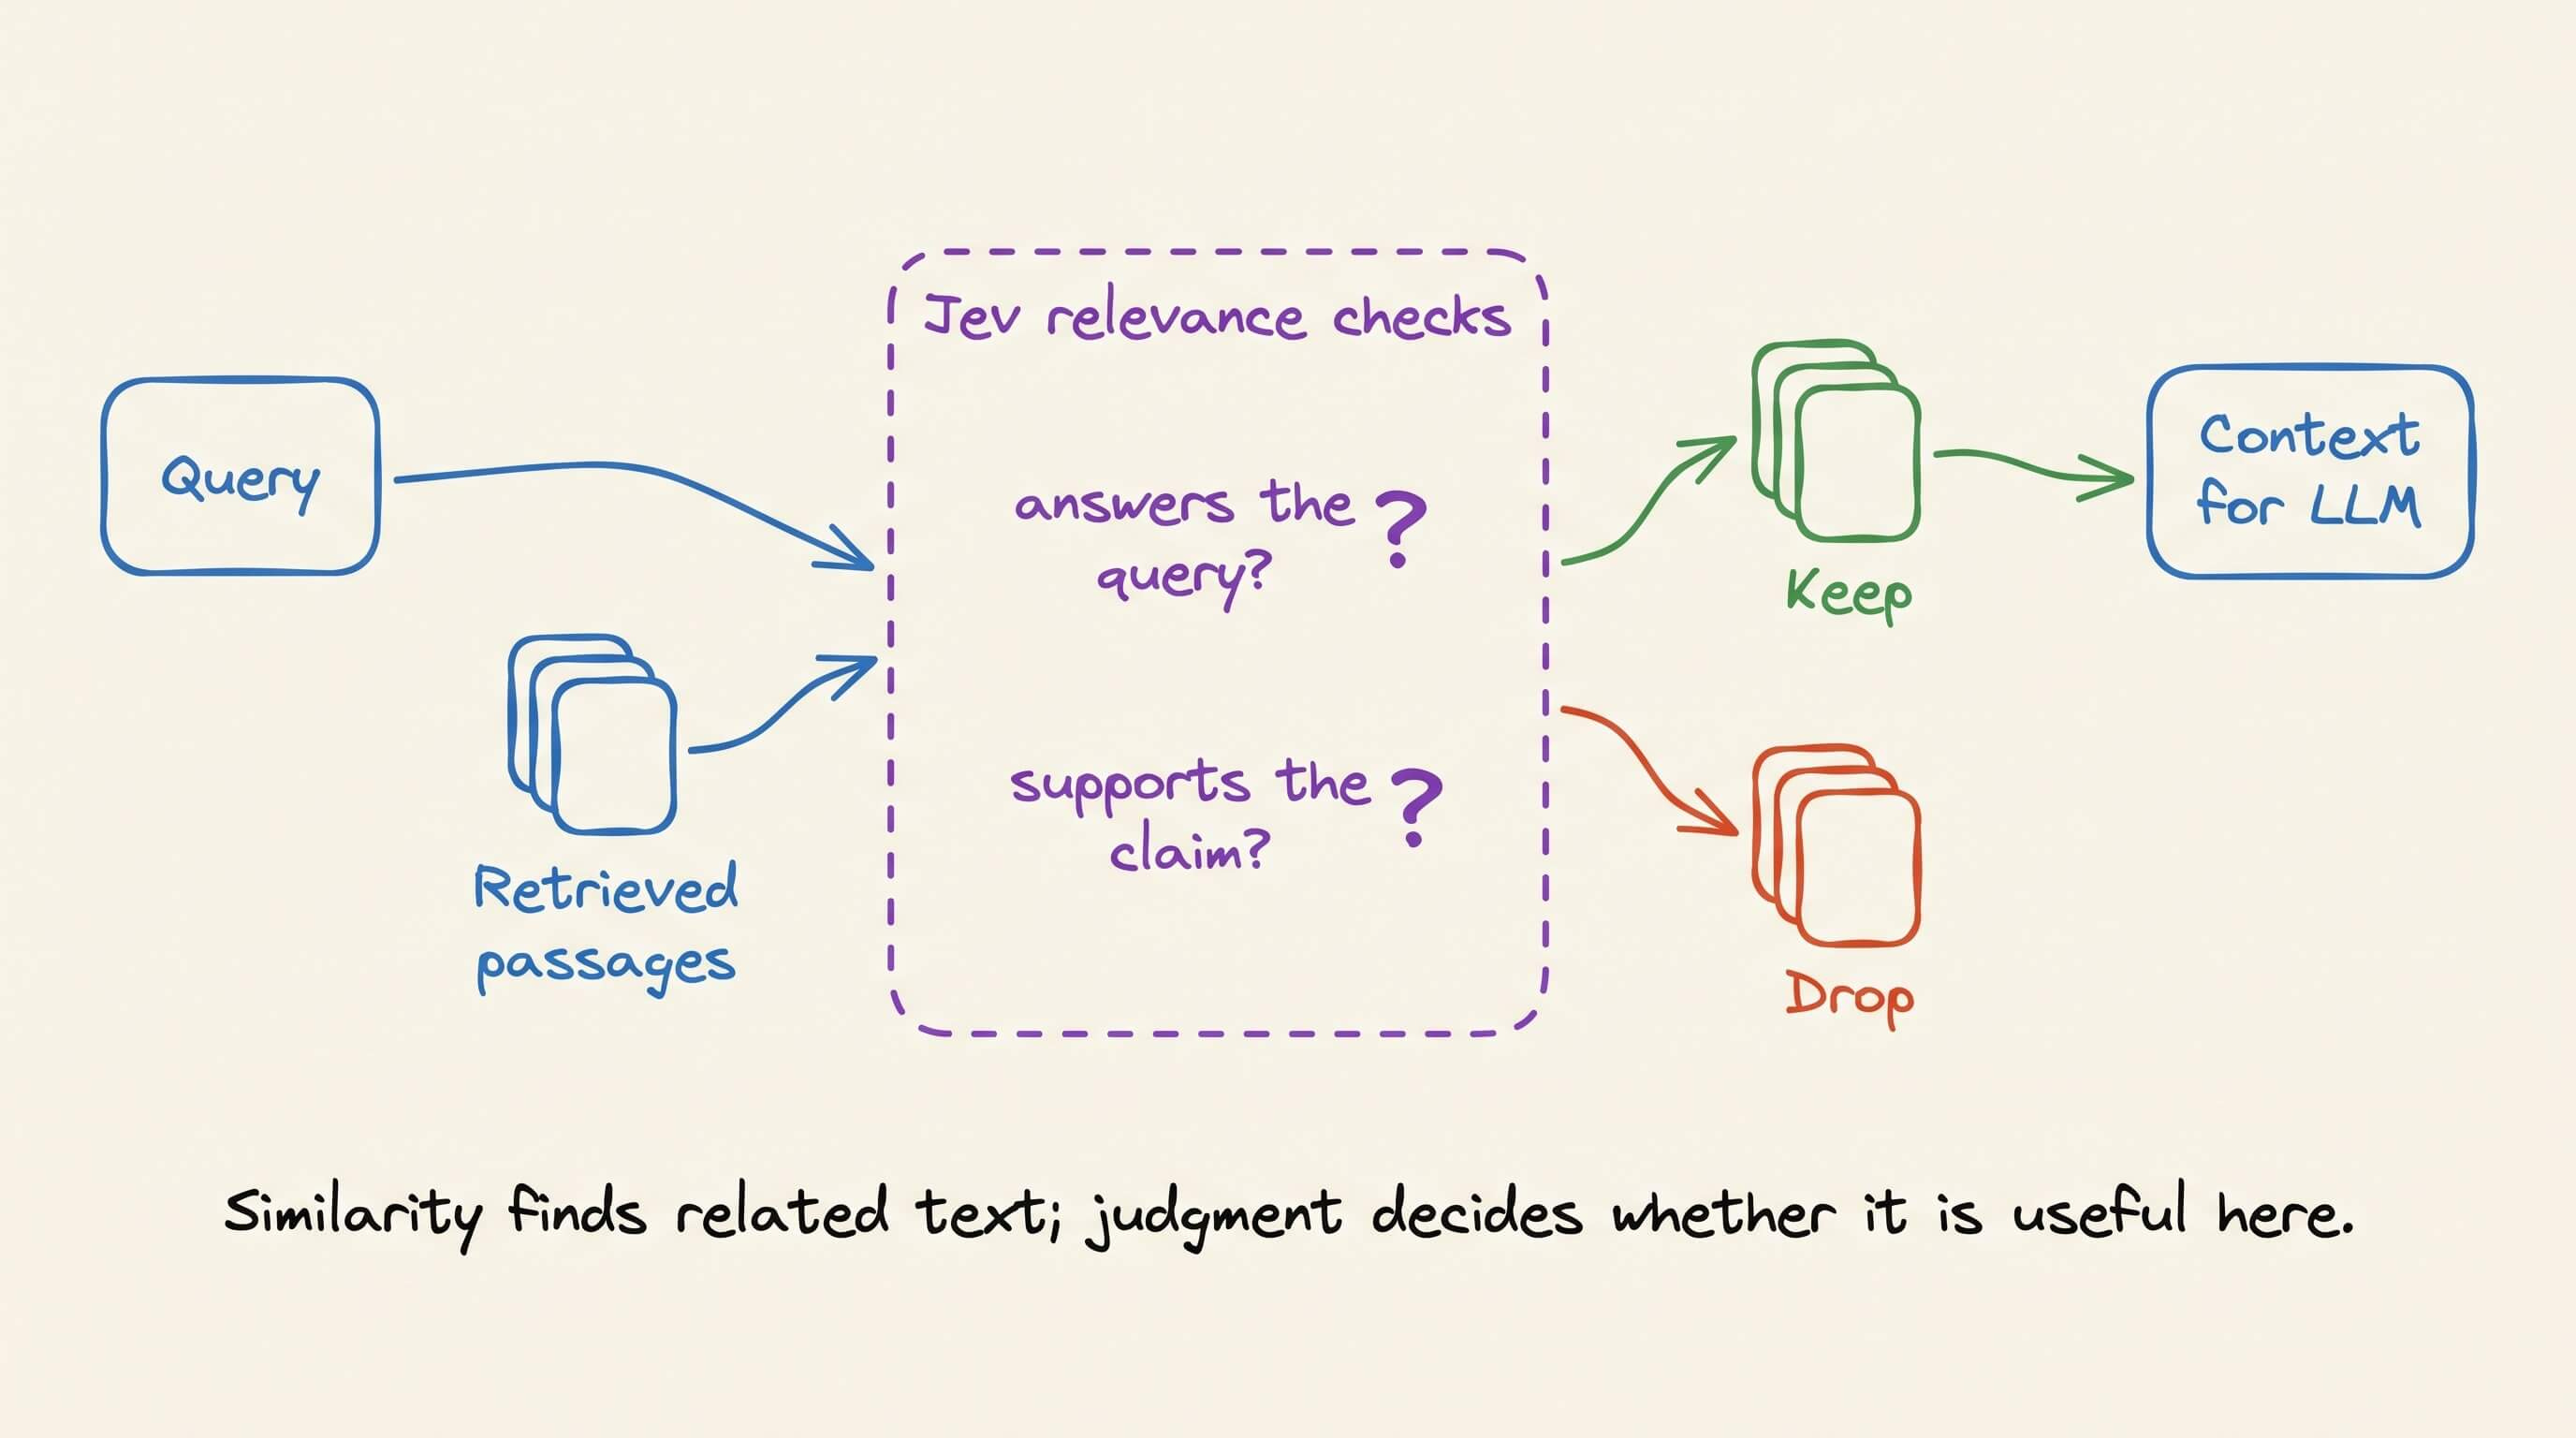
Embeddings are excellent at finding semantically related text. Jev can make the narrower decision of whether a particular passage is useful for this question.
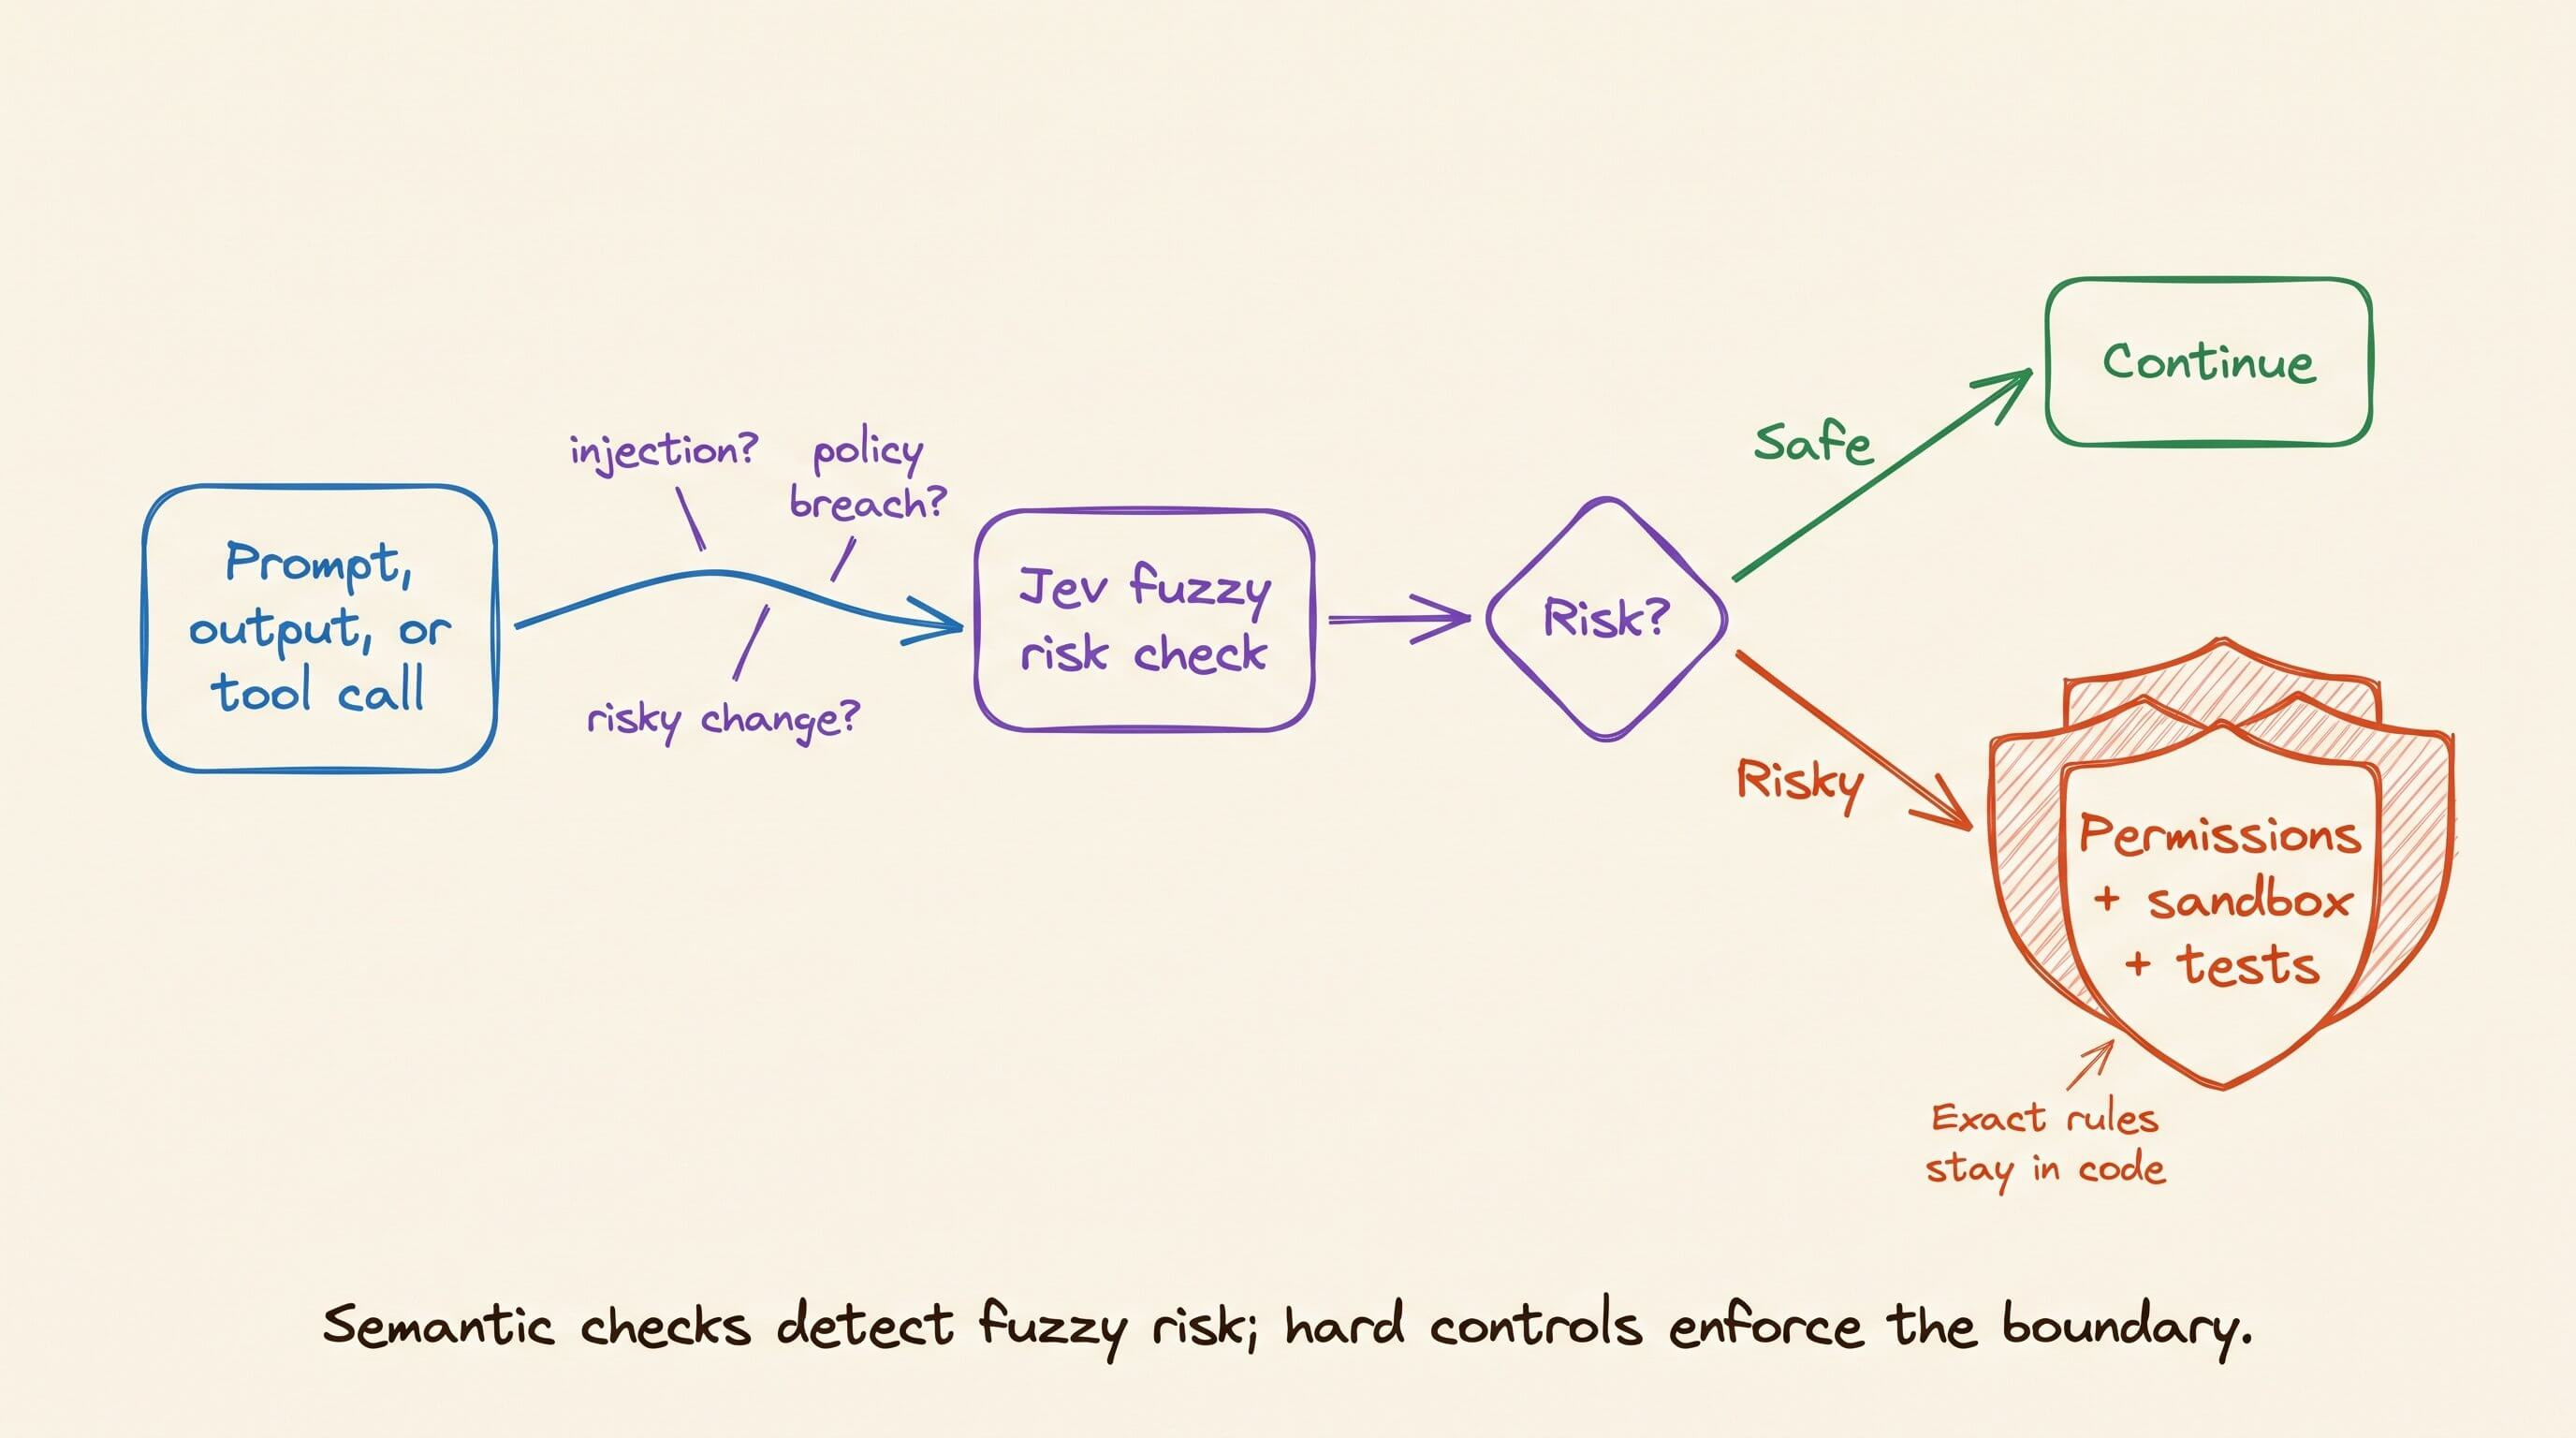
3) Semantic checks at enforcement boundaries
Jev can screen for prompt injection, policy violations, and risky tool calls. Its scores can inform an enforcement boundary, but they should not become one. Permissions, sandboxes, allowlists, and tests must enforce exact rules.
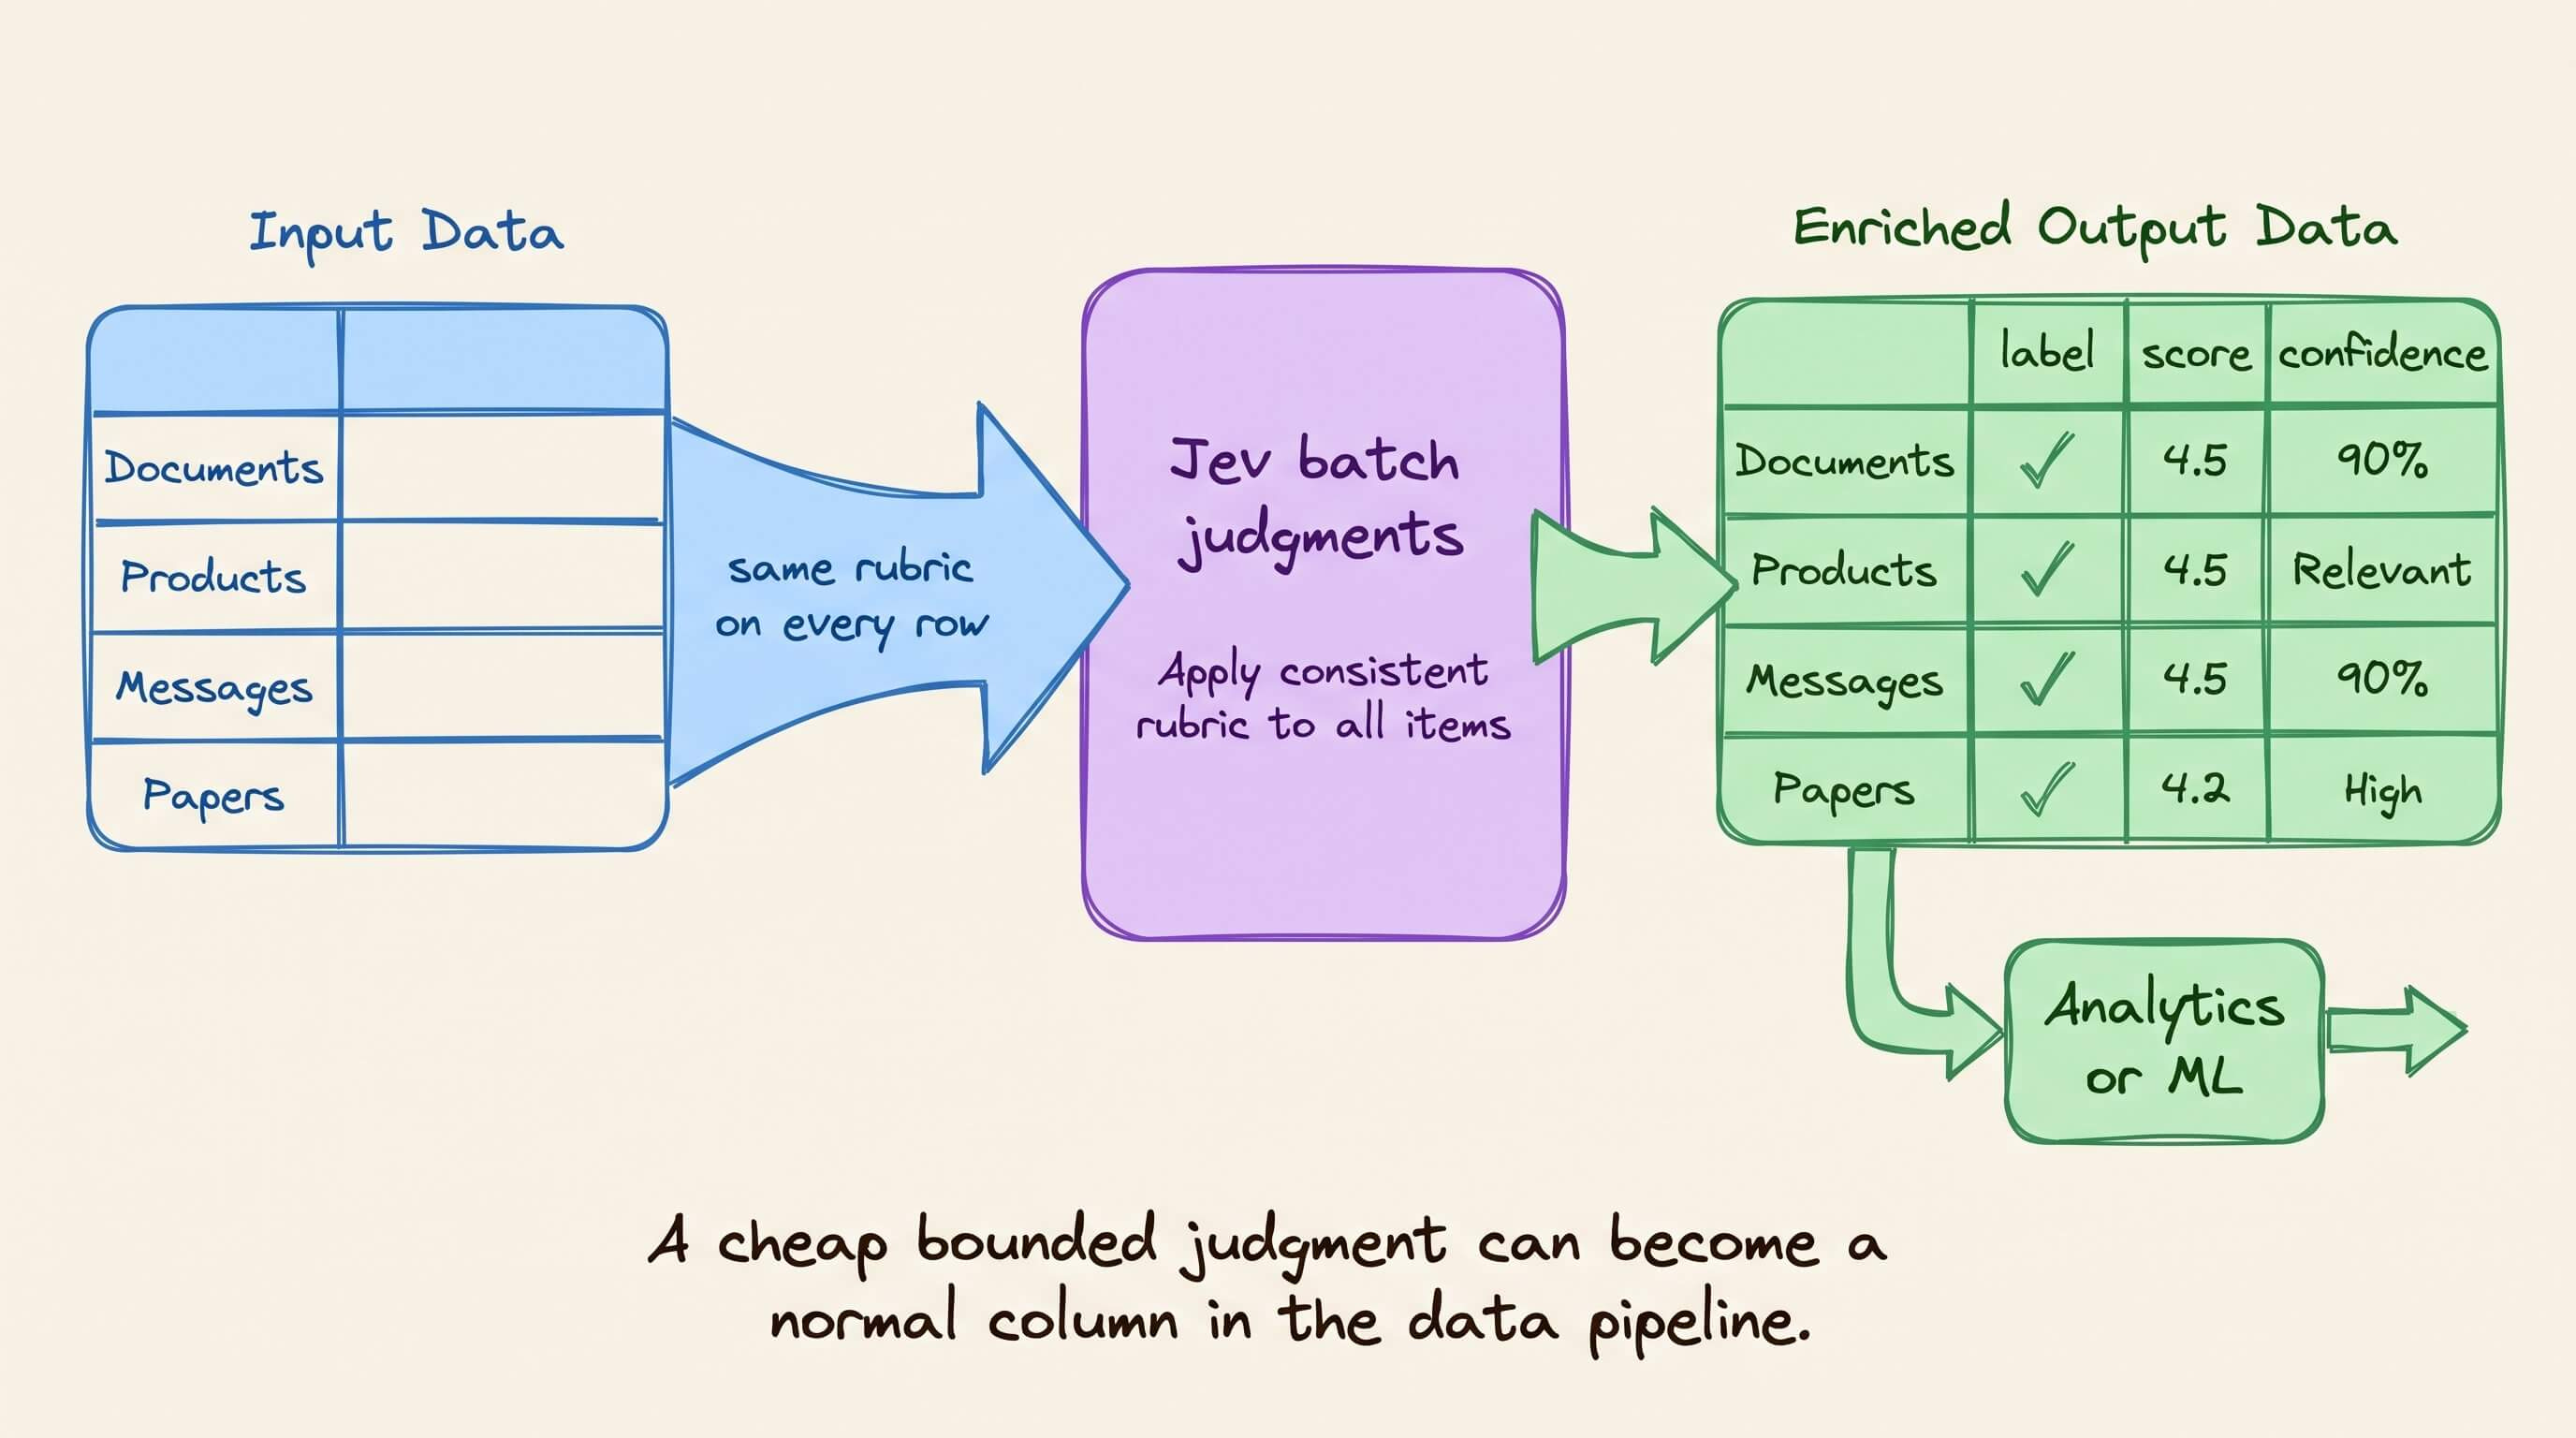
4) Corpus-scale semantic enrichment
Jev can label documents, products, and customer messages or turn free text into features for another model. Low per-call cost can make semantic scoring practical across every row of a dataset.
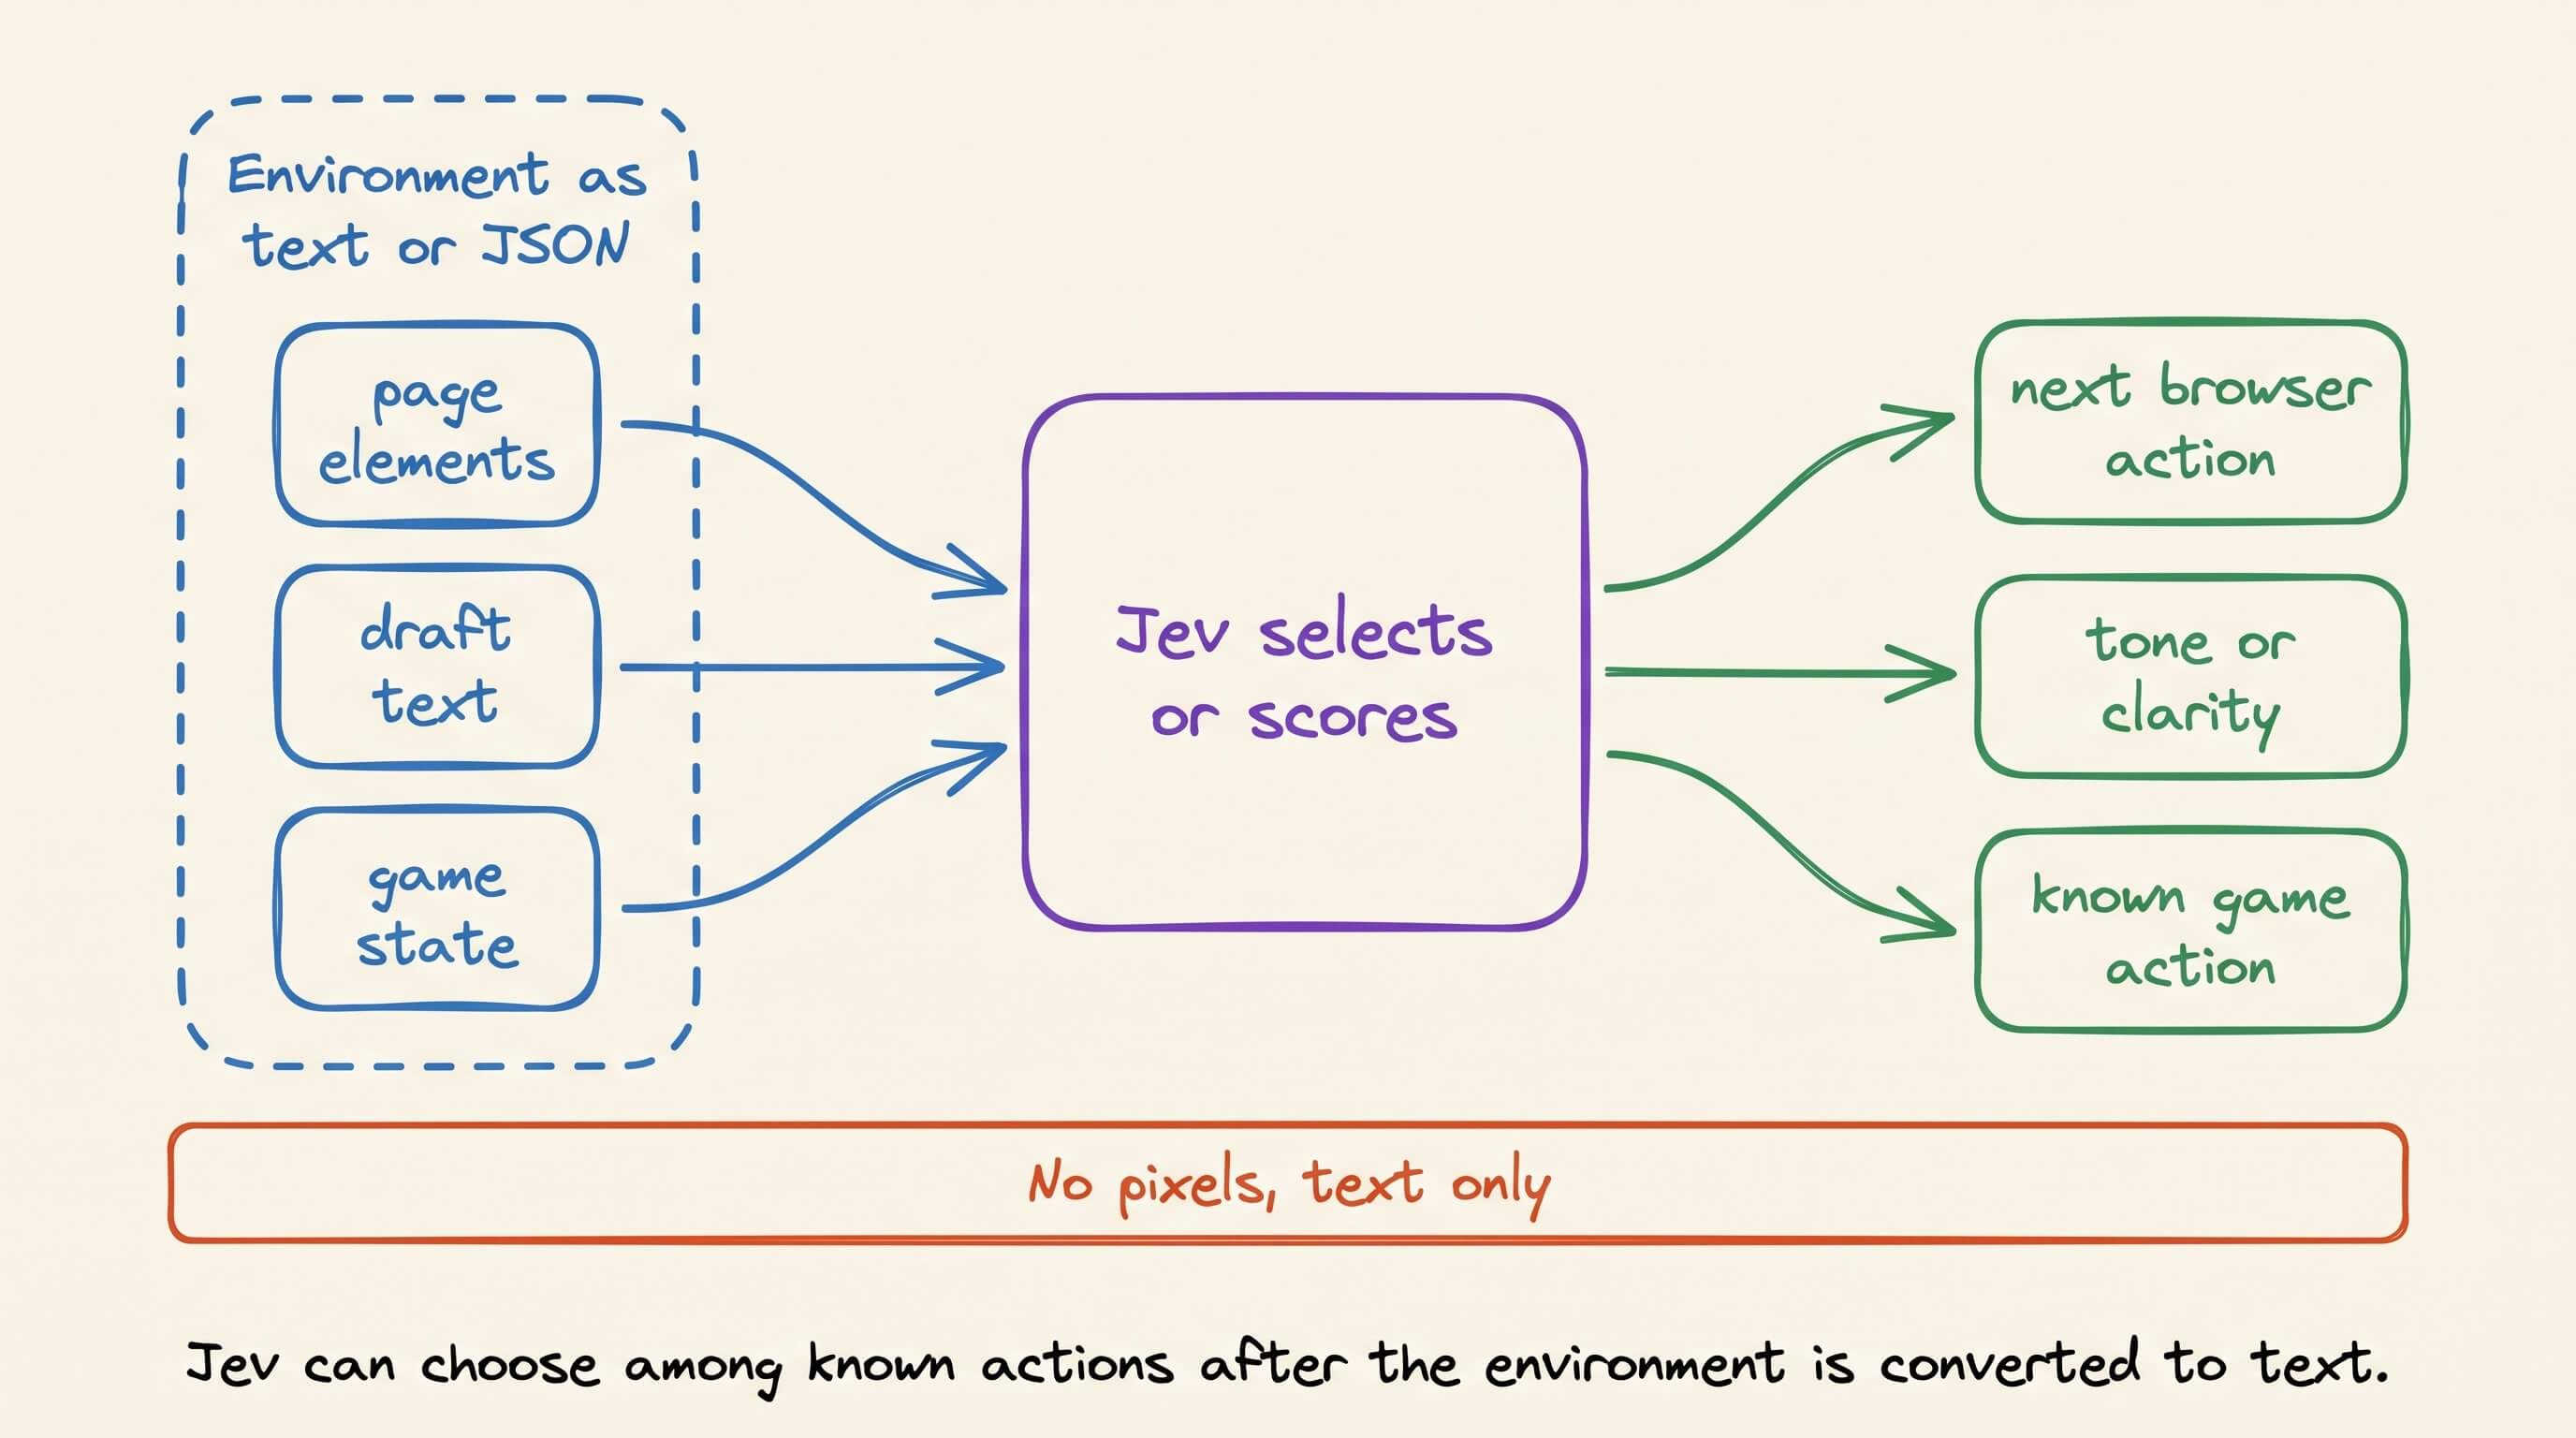
5) Real-time interfaces
Jev can choose among known browser actions or actions from structured game state. It is text-only, so the environment must first be represented as text or JSON.
Failure modes and exclusion criteria
Reject Jev when the task cannot be expressed as a stable set of outcomes.
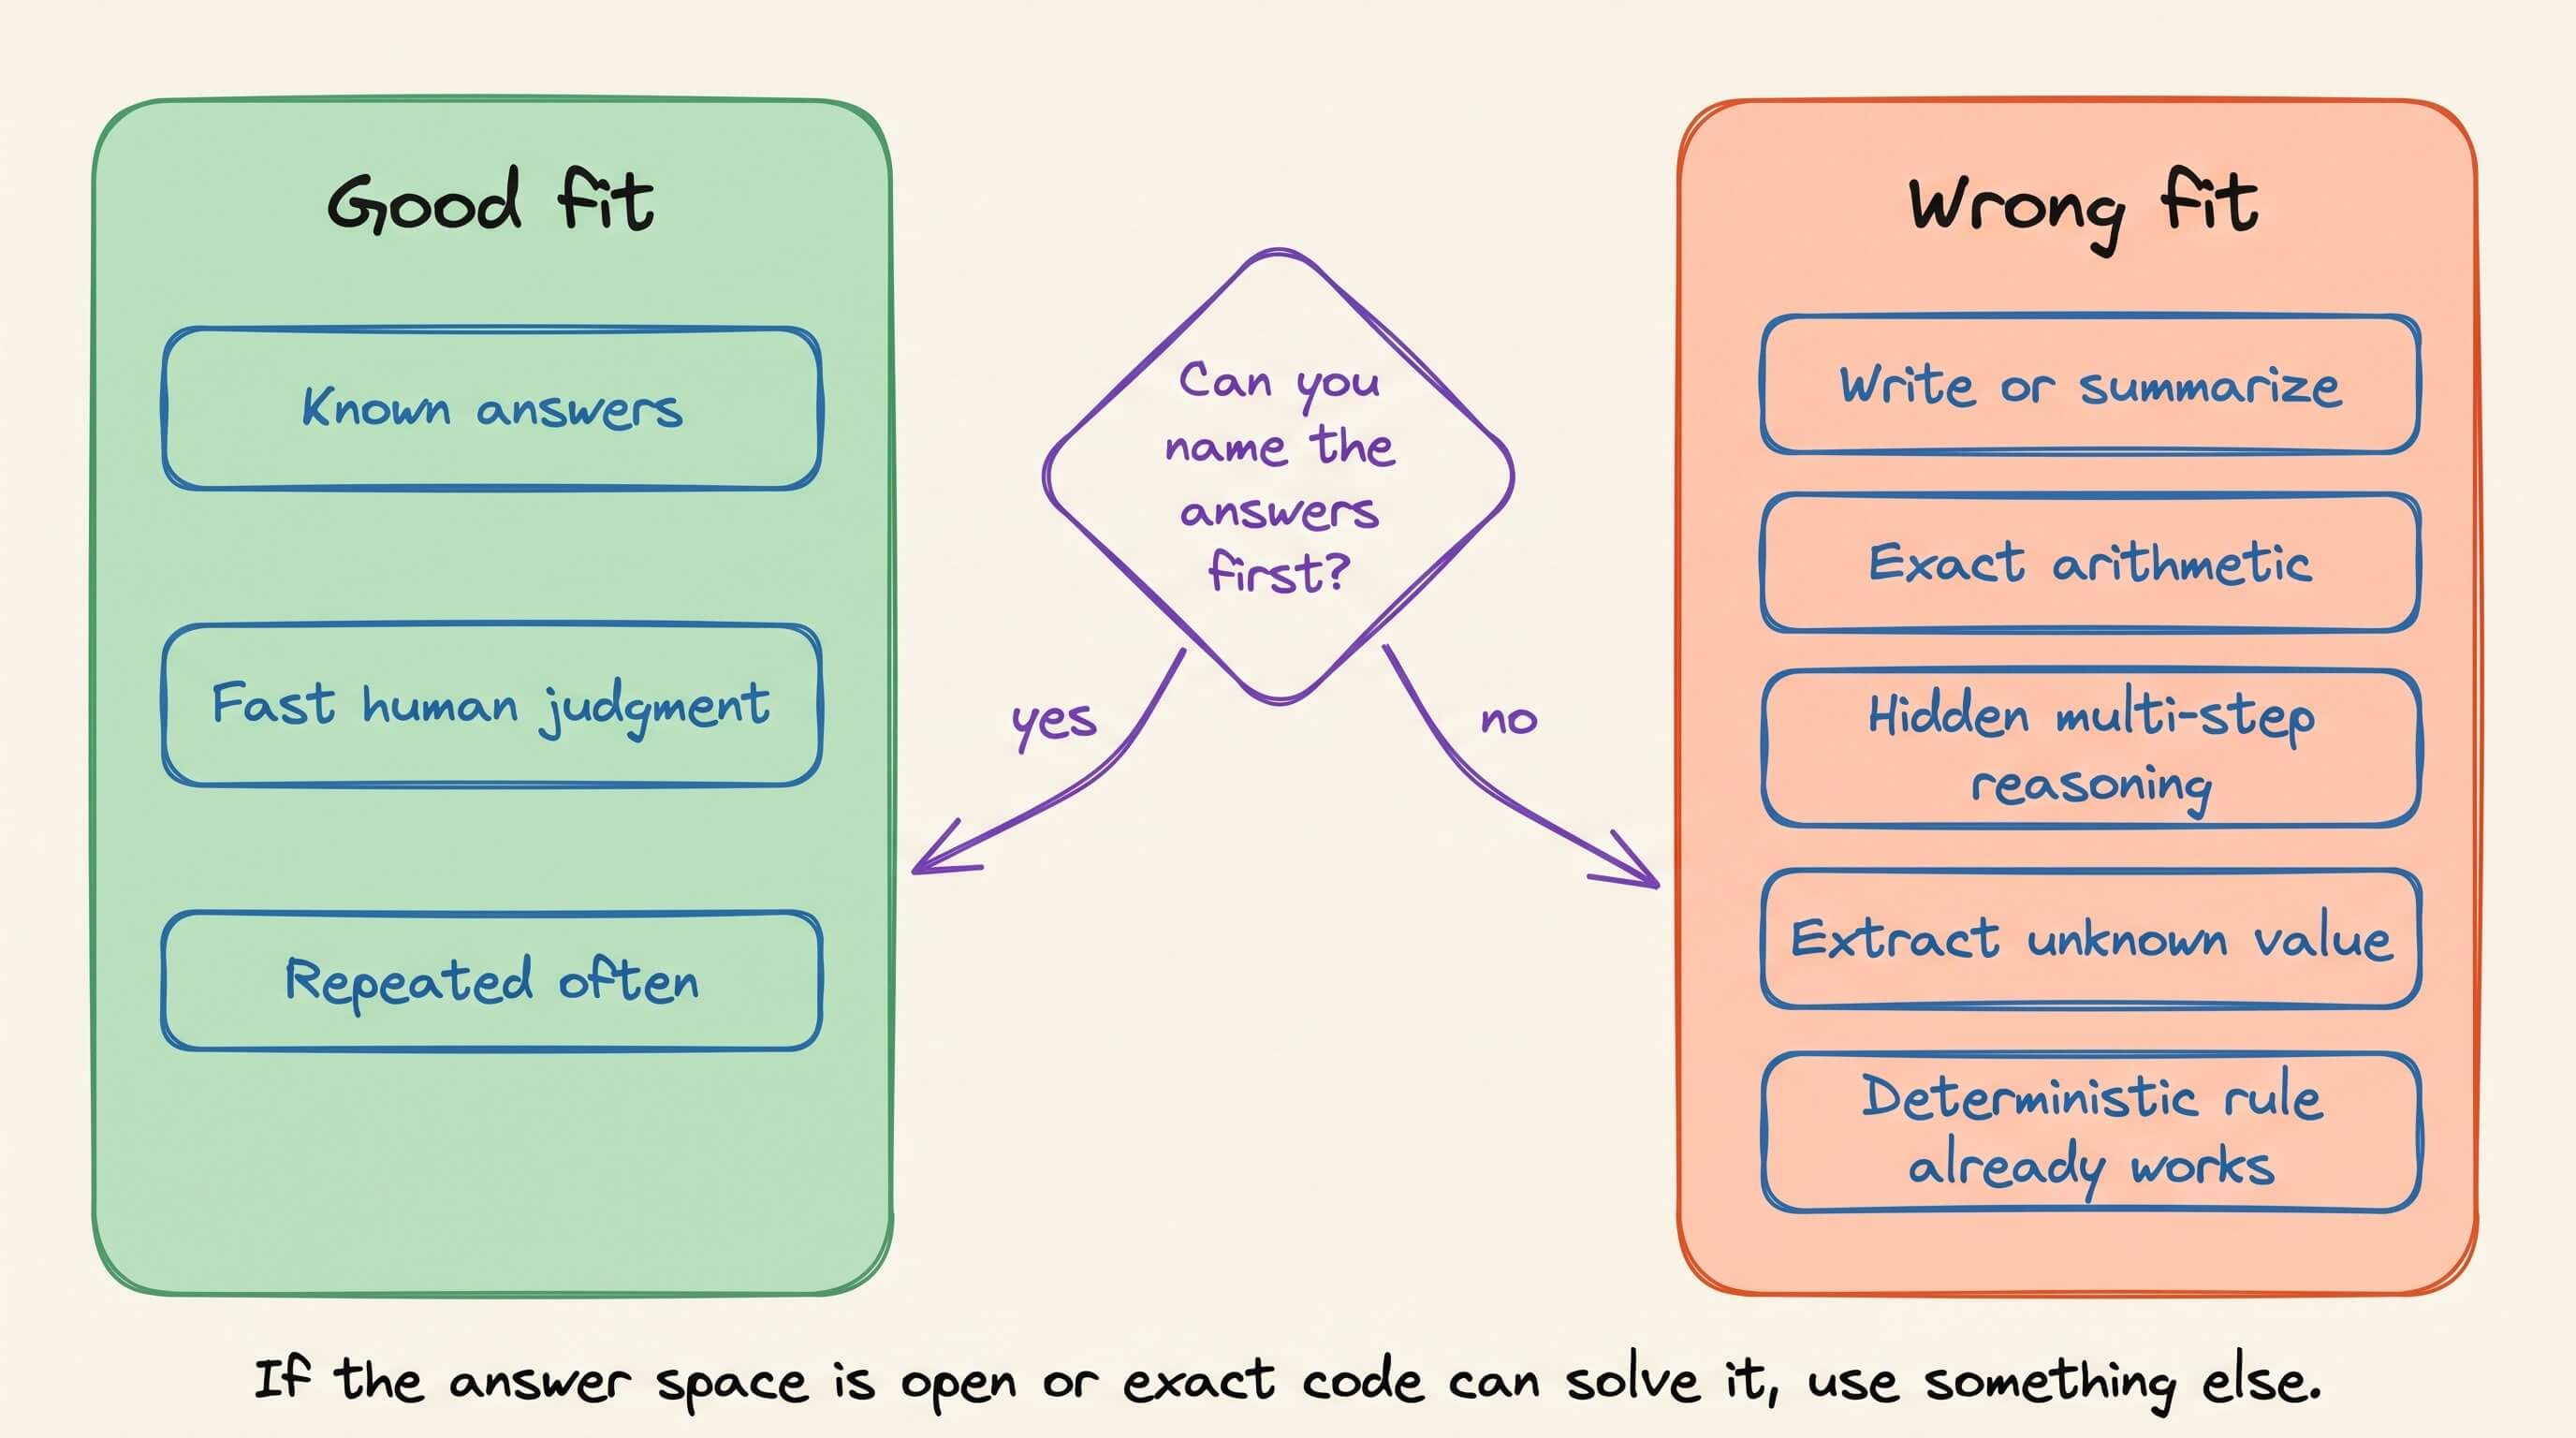
It cannot write, summarize, generate code, or explain its reasoning.
Do arithmetic, counting, date comparison, and exact string manipulation in code.
If a decision needs several hidden reasoning steps, split it into smaller questions or use a reasoning model.
It cannot extract an unknown value directly. Find candidates first, then let Jev choose among them.
Irrelevant context can reduce accuracy. Send only the state needed for the decision.
Closed weights, early access, and limited independent calibration data make blind trust premature.
If deterministic code already solves the problem, keep it. An if statement is faster, cheaper, and easier to test than any model.
Deployment procedure and operational controls
A cheap model becomes expensive when mistakes cause retries, reviews, or incidents. Measure expected cost per decision, including model calls, escalations, false approvals, false blocks, and recovery work.
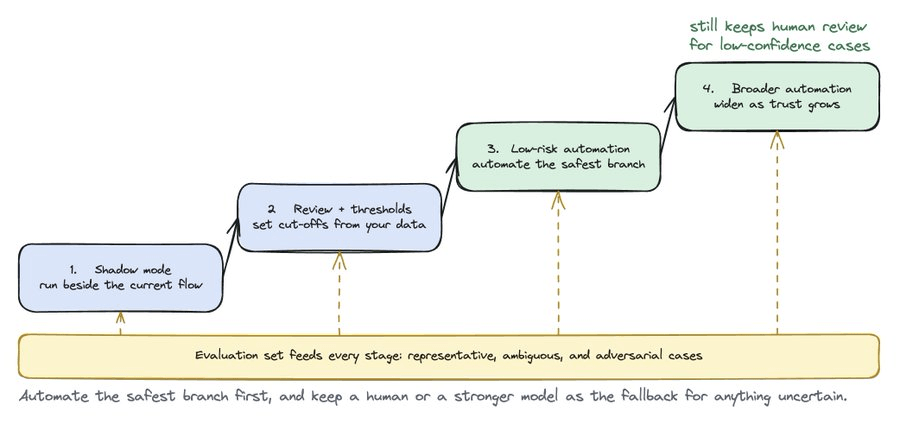
A production rollout needs evidence at each boundary:
Choose one bounded, low-risk decision with clear possible answers.
Write the rubric before calling the model. Define what belongs in every option.
Collect representative examples with expected answers, including ambiguous and adversarial cases.
Run Jev in shadow mode beside the current workflow without letting it change behavior.
Plot accuracy against confidence and set thresholds from your data.
Automate the safest branch first. Keep a person or stronger model for uncertain cases.
Pin or log the model version, questions, criteria, and thresholds so you can replay changes against the same evaluation set.
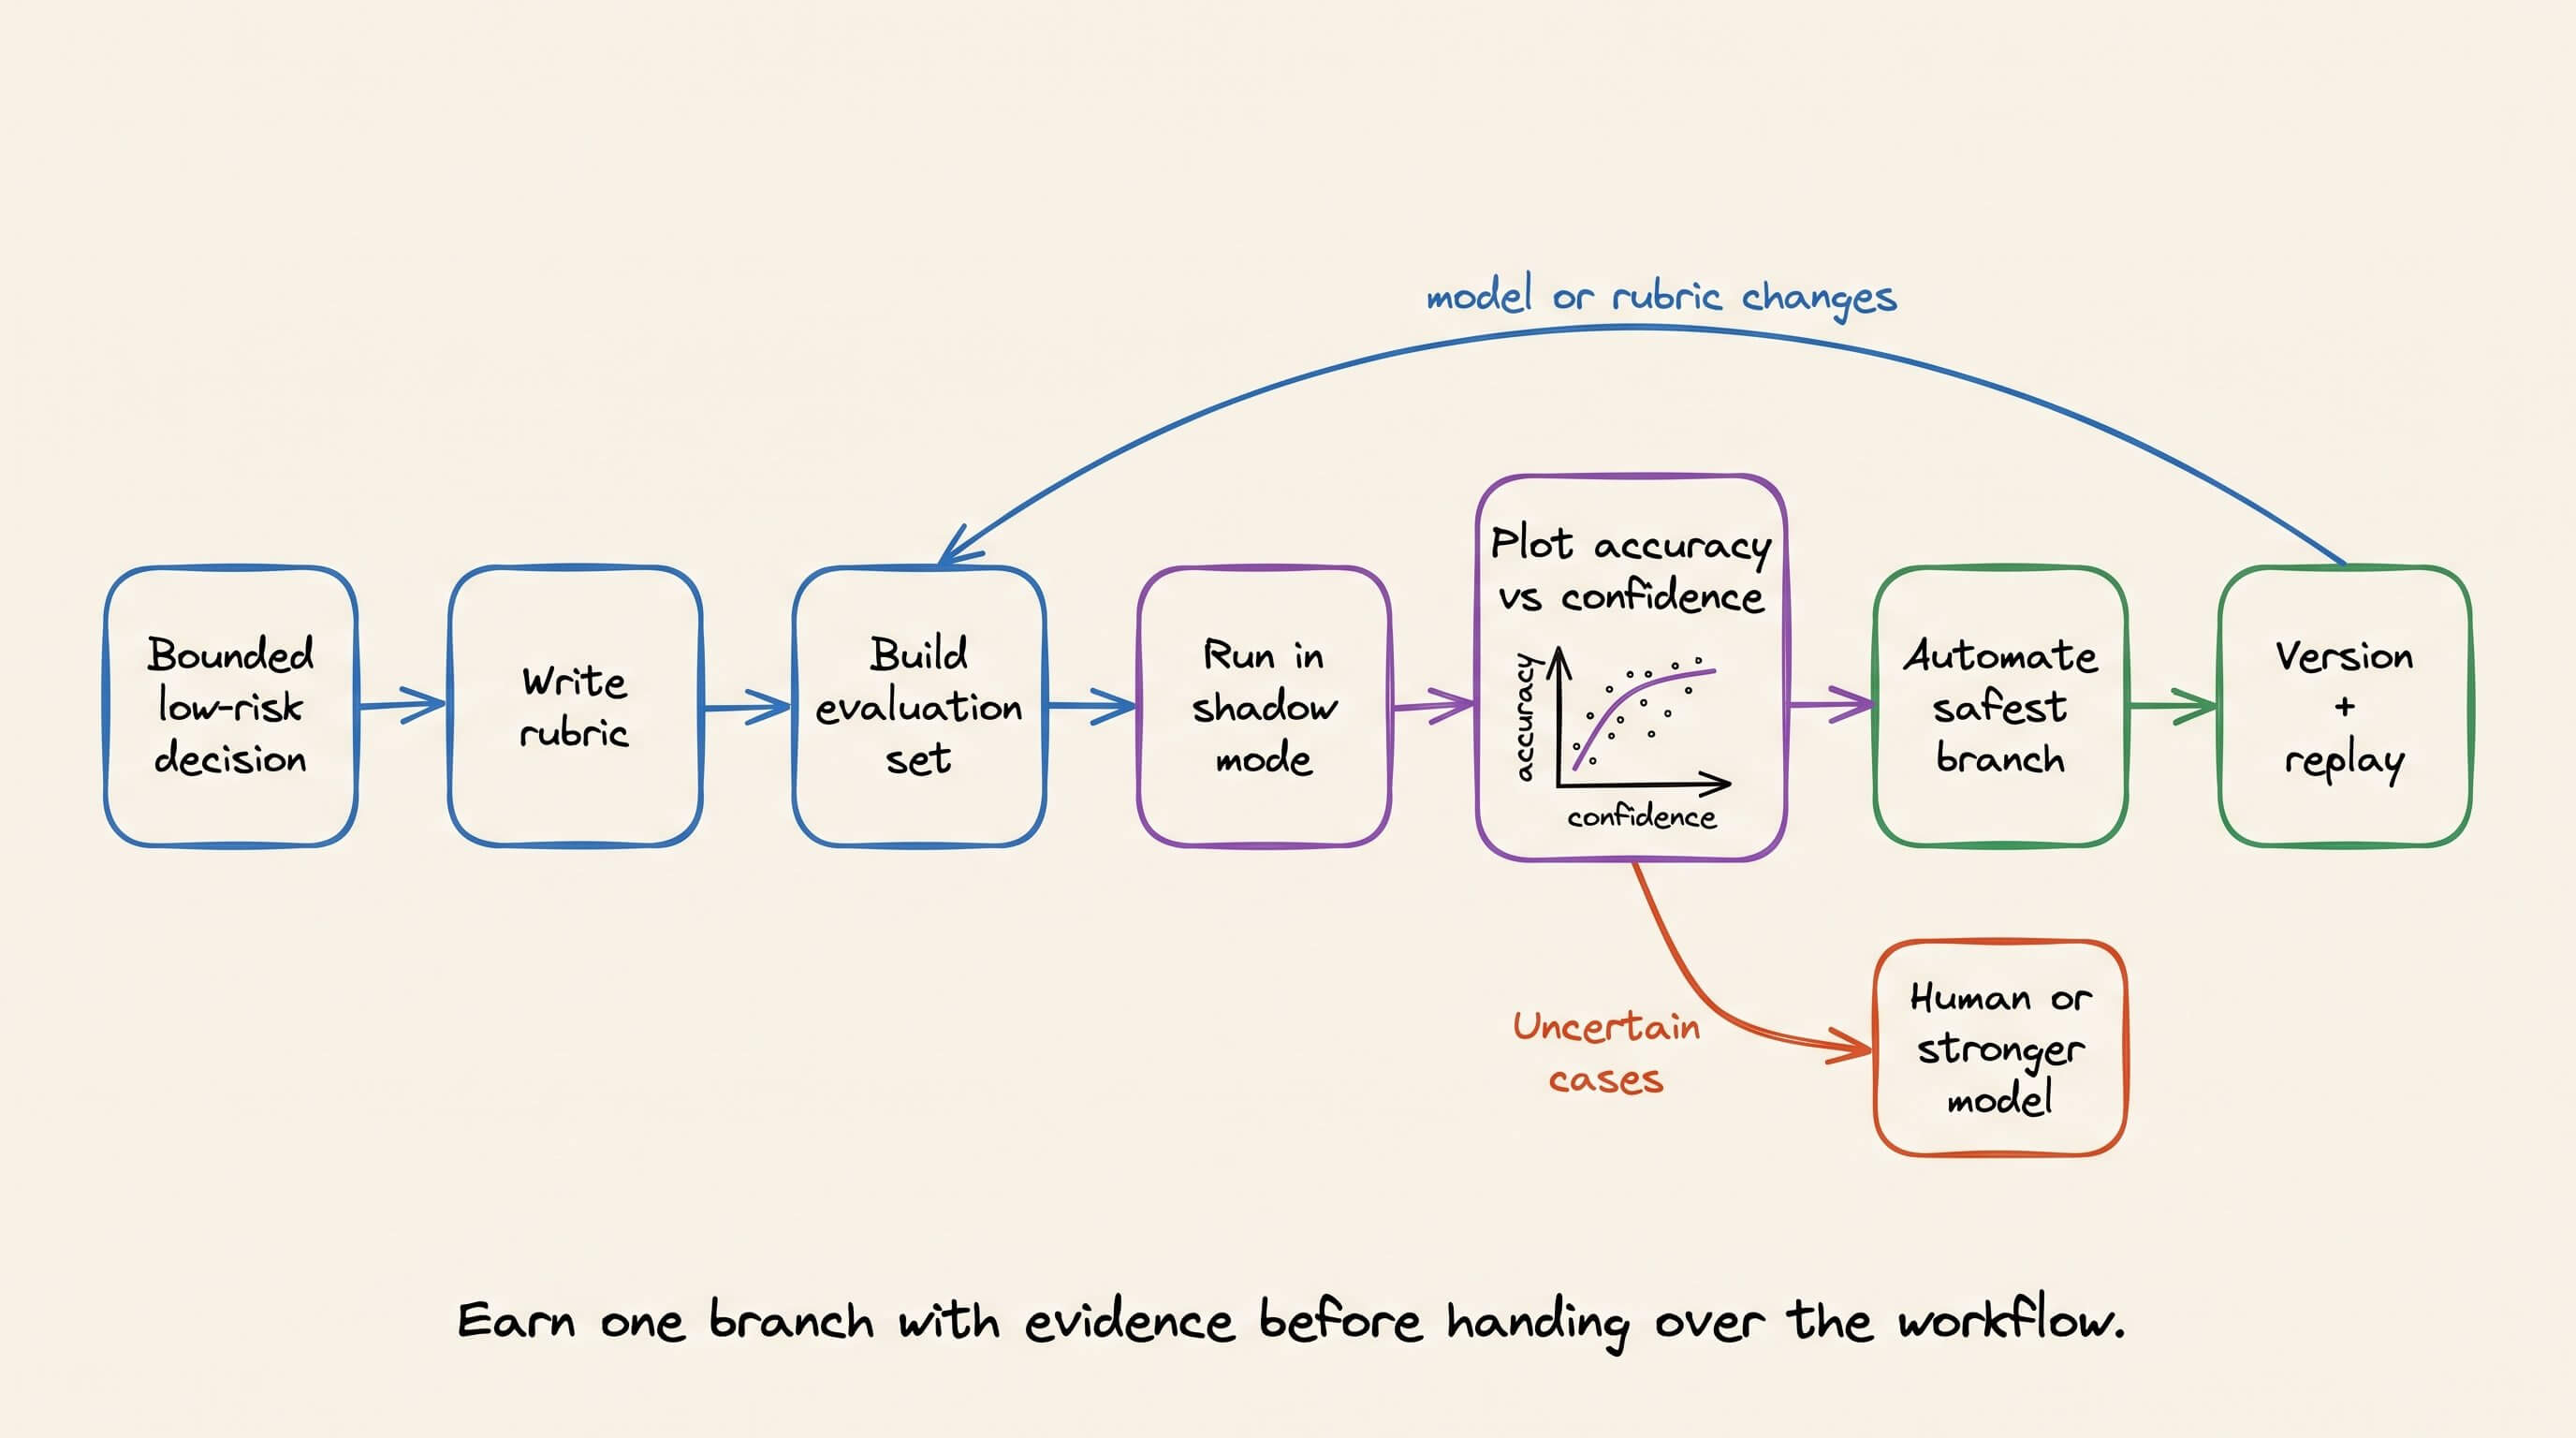
Questions and criteria are program logic. Version, review, and test them.
The architectural trade
Jev gives up generation in exchange for fixed answer types, explicit uncertainty, and code-owned branching. The LLM produces a plan, explanation, or code. Jev routes the request, gates risky actions, checks the result, and escalates uncertain cases.
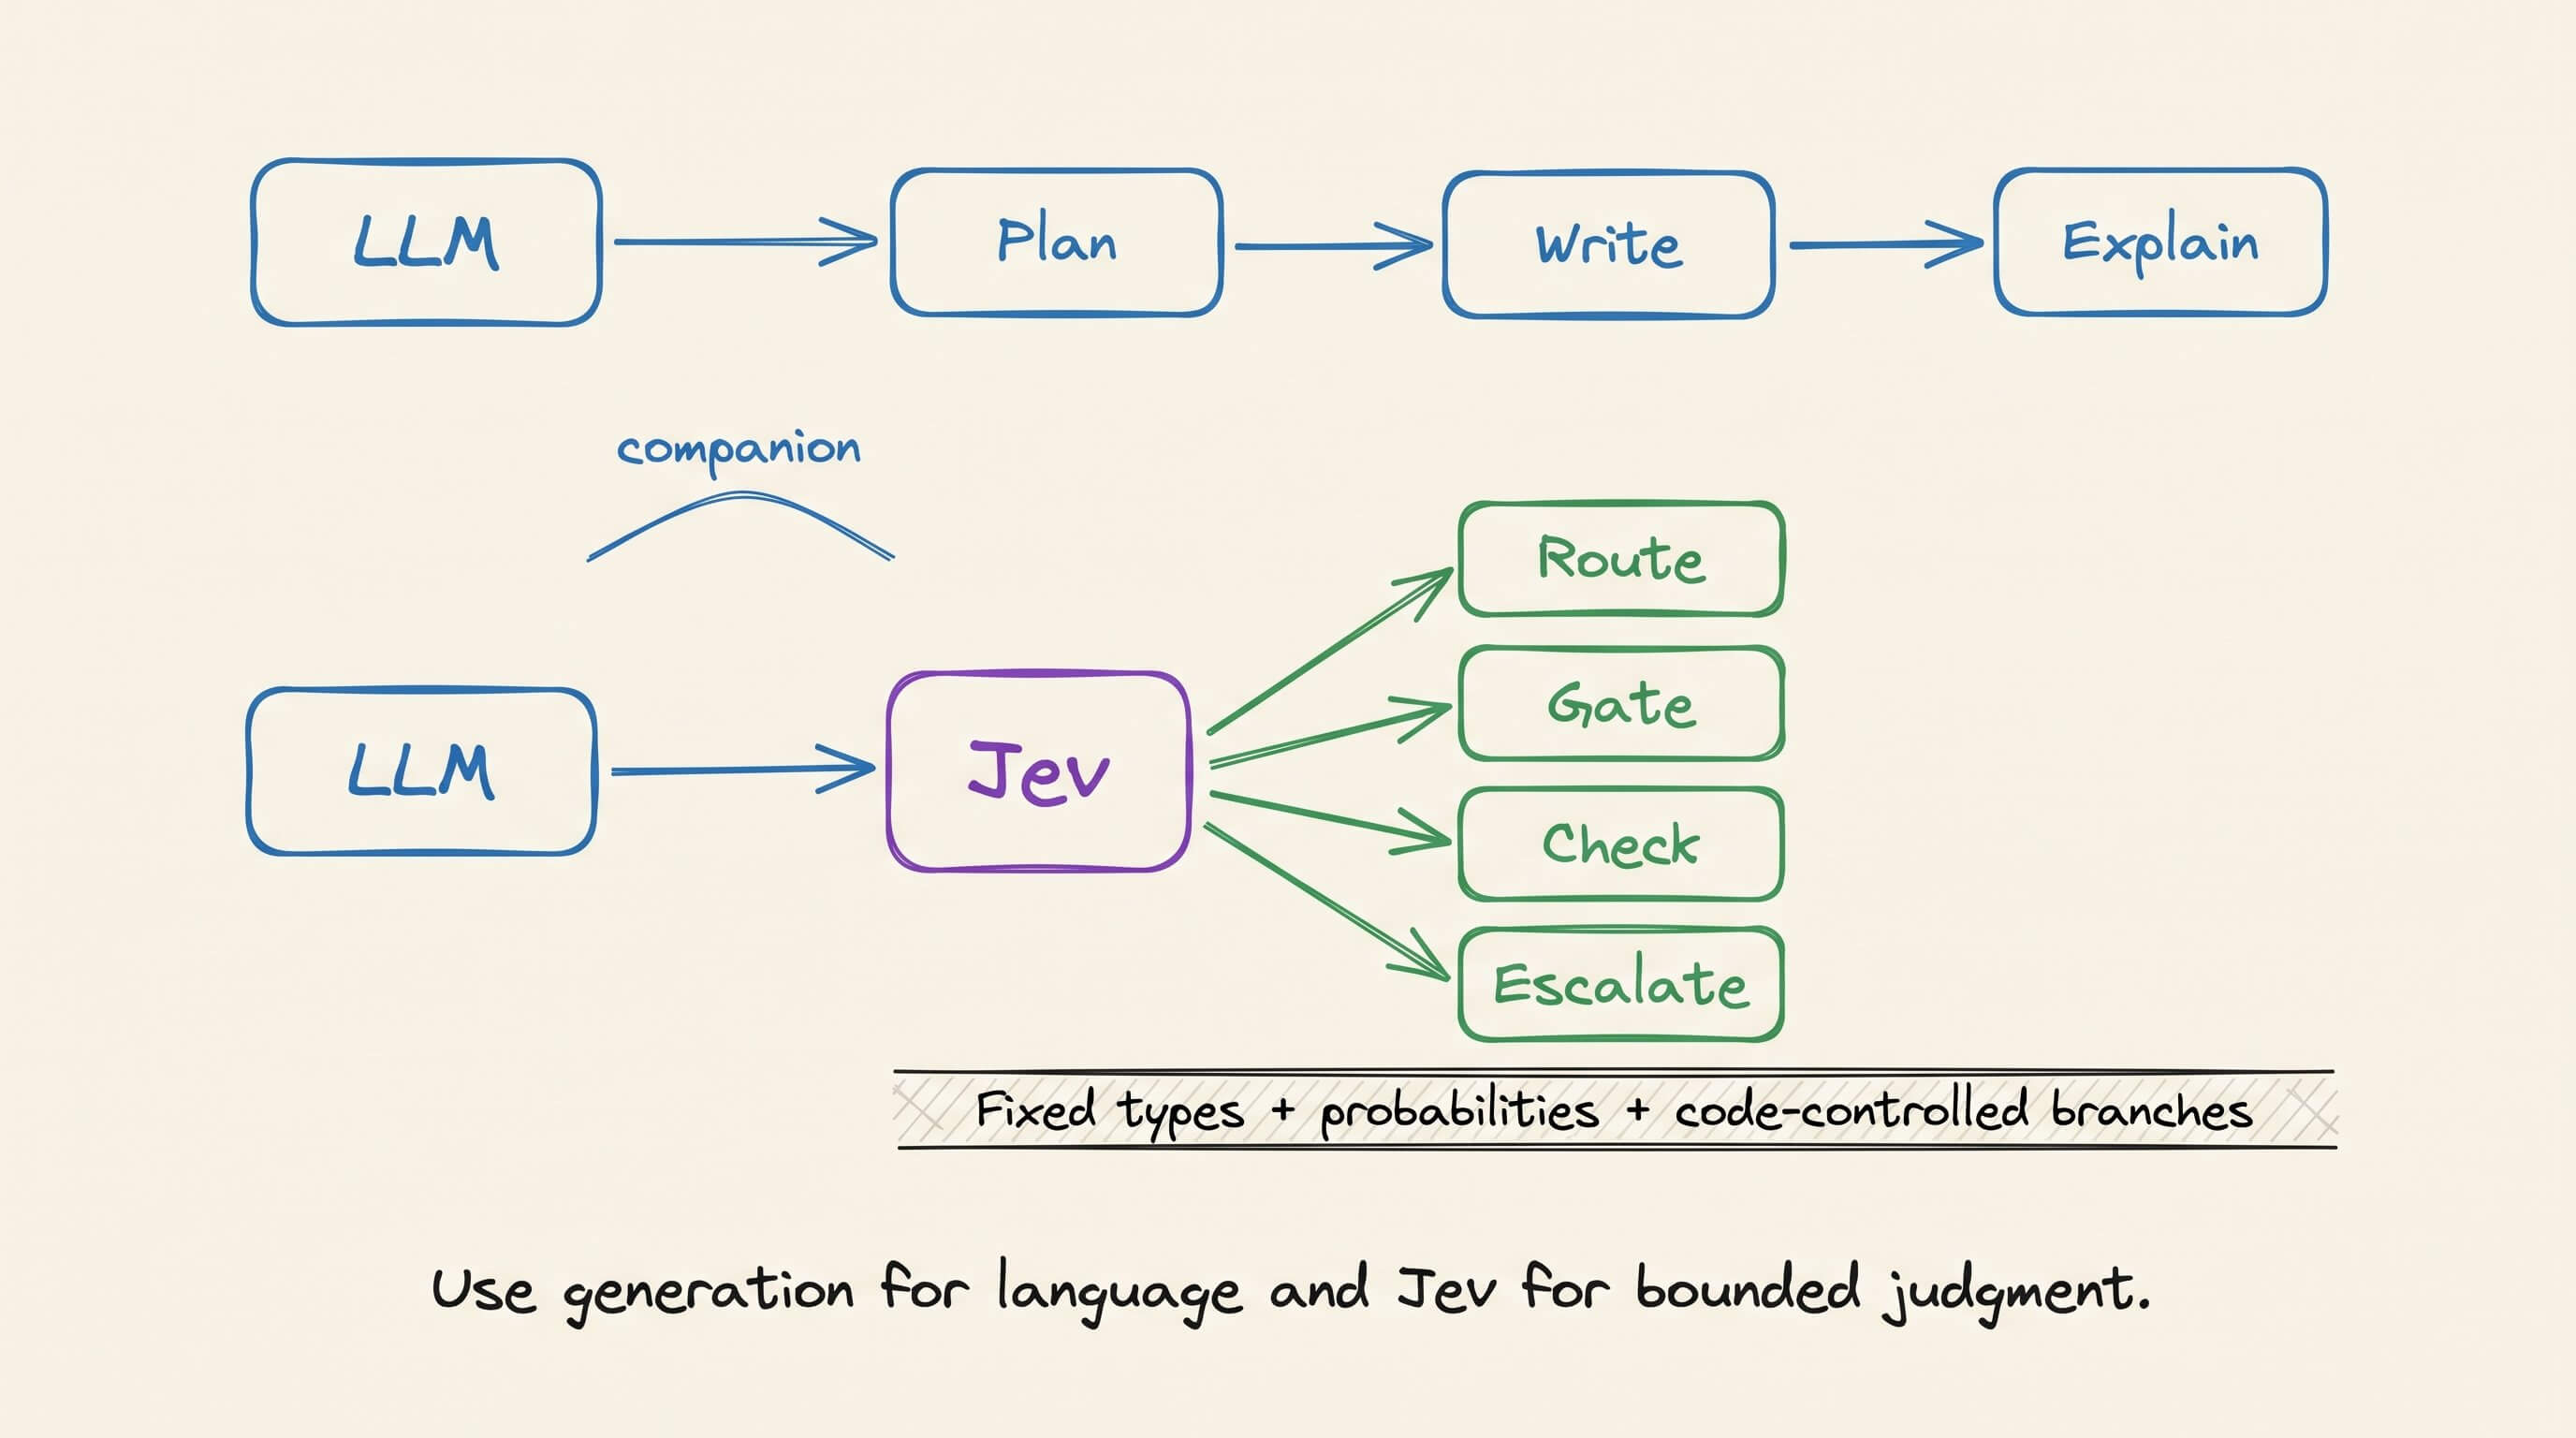
Generation and judgment are different workloads. Forcing both through a text-generation API adds latency and turns control flow into prompt parsing. Jev exposes semantic judgment as a separate component.
Start with one bounded decision currently handled by a slow LLM call or a brittle regex. Send the minimum state, define the answers, and log Jev’s probabilities beside the current result. Automate one low-risk branch only after the evaluation supports it.
An if statement handles explicit values. Jev estimates the meaning needed to choose among them. The application decides whether that estimate is safe to act on.
Good day!