

In today’s newsletter:
An open-source engine for faster local LLMs on Mac
Why DeepSeek stores its KV cache on disk
What is Early Exaggeration in tSNE?
An open-source engine for faster local LLMs on Mac
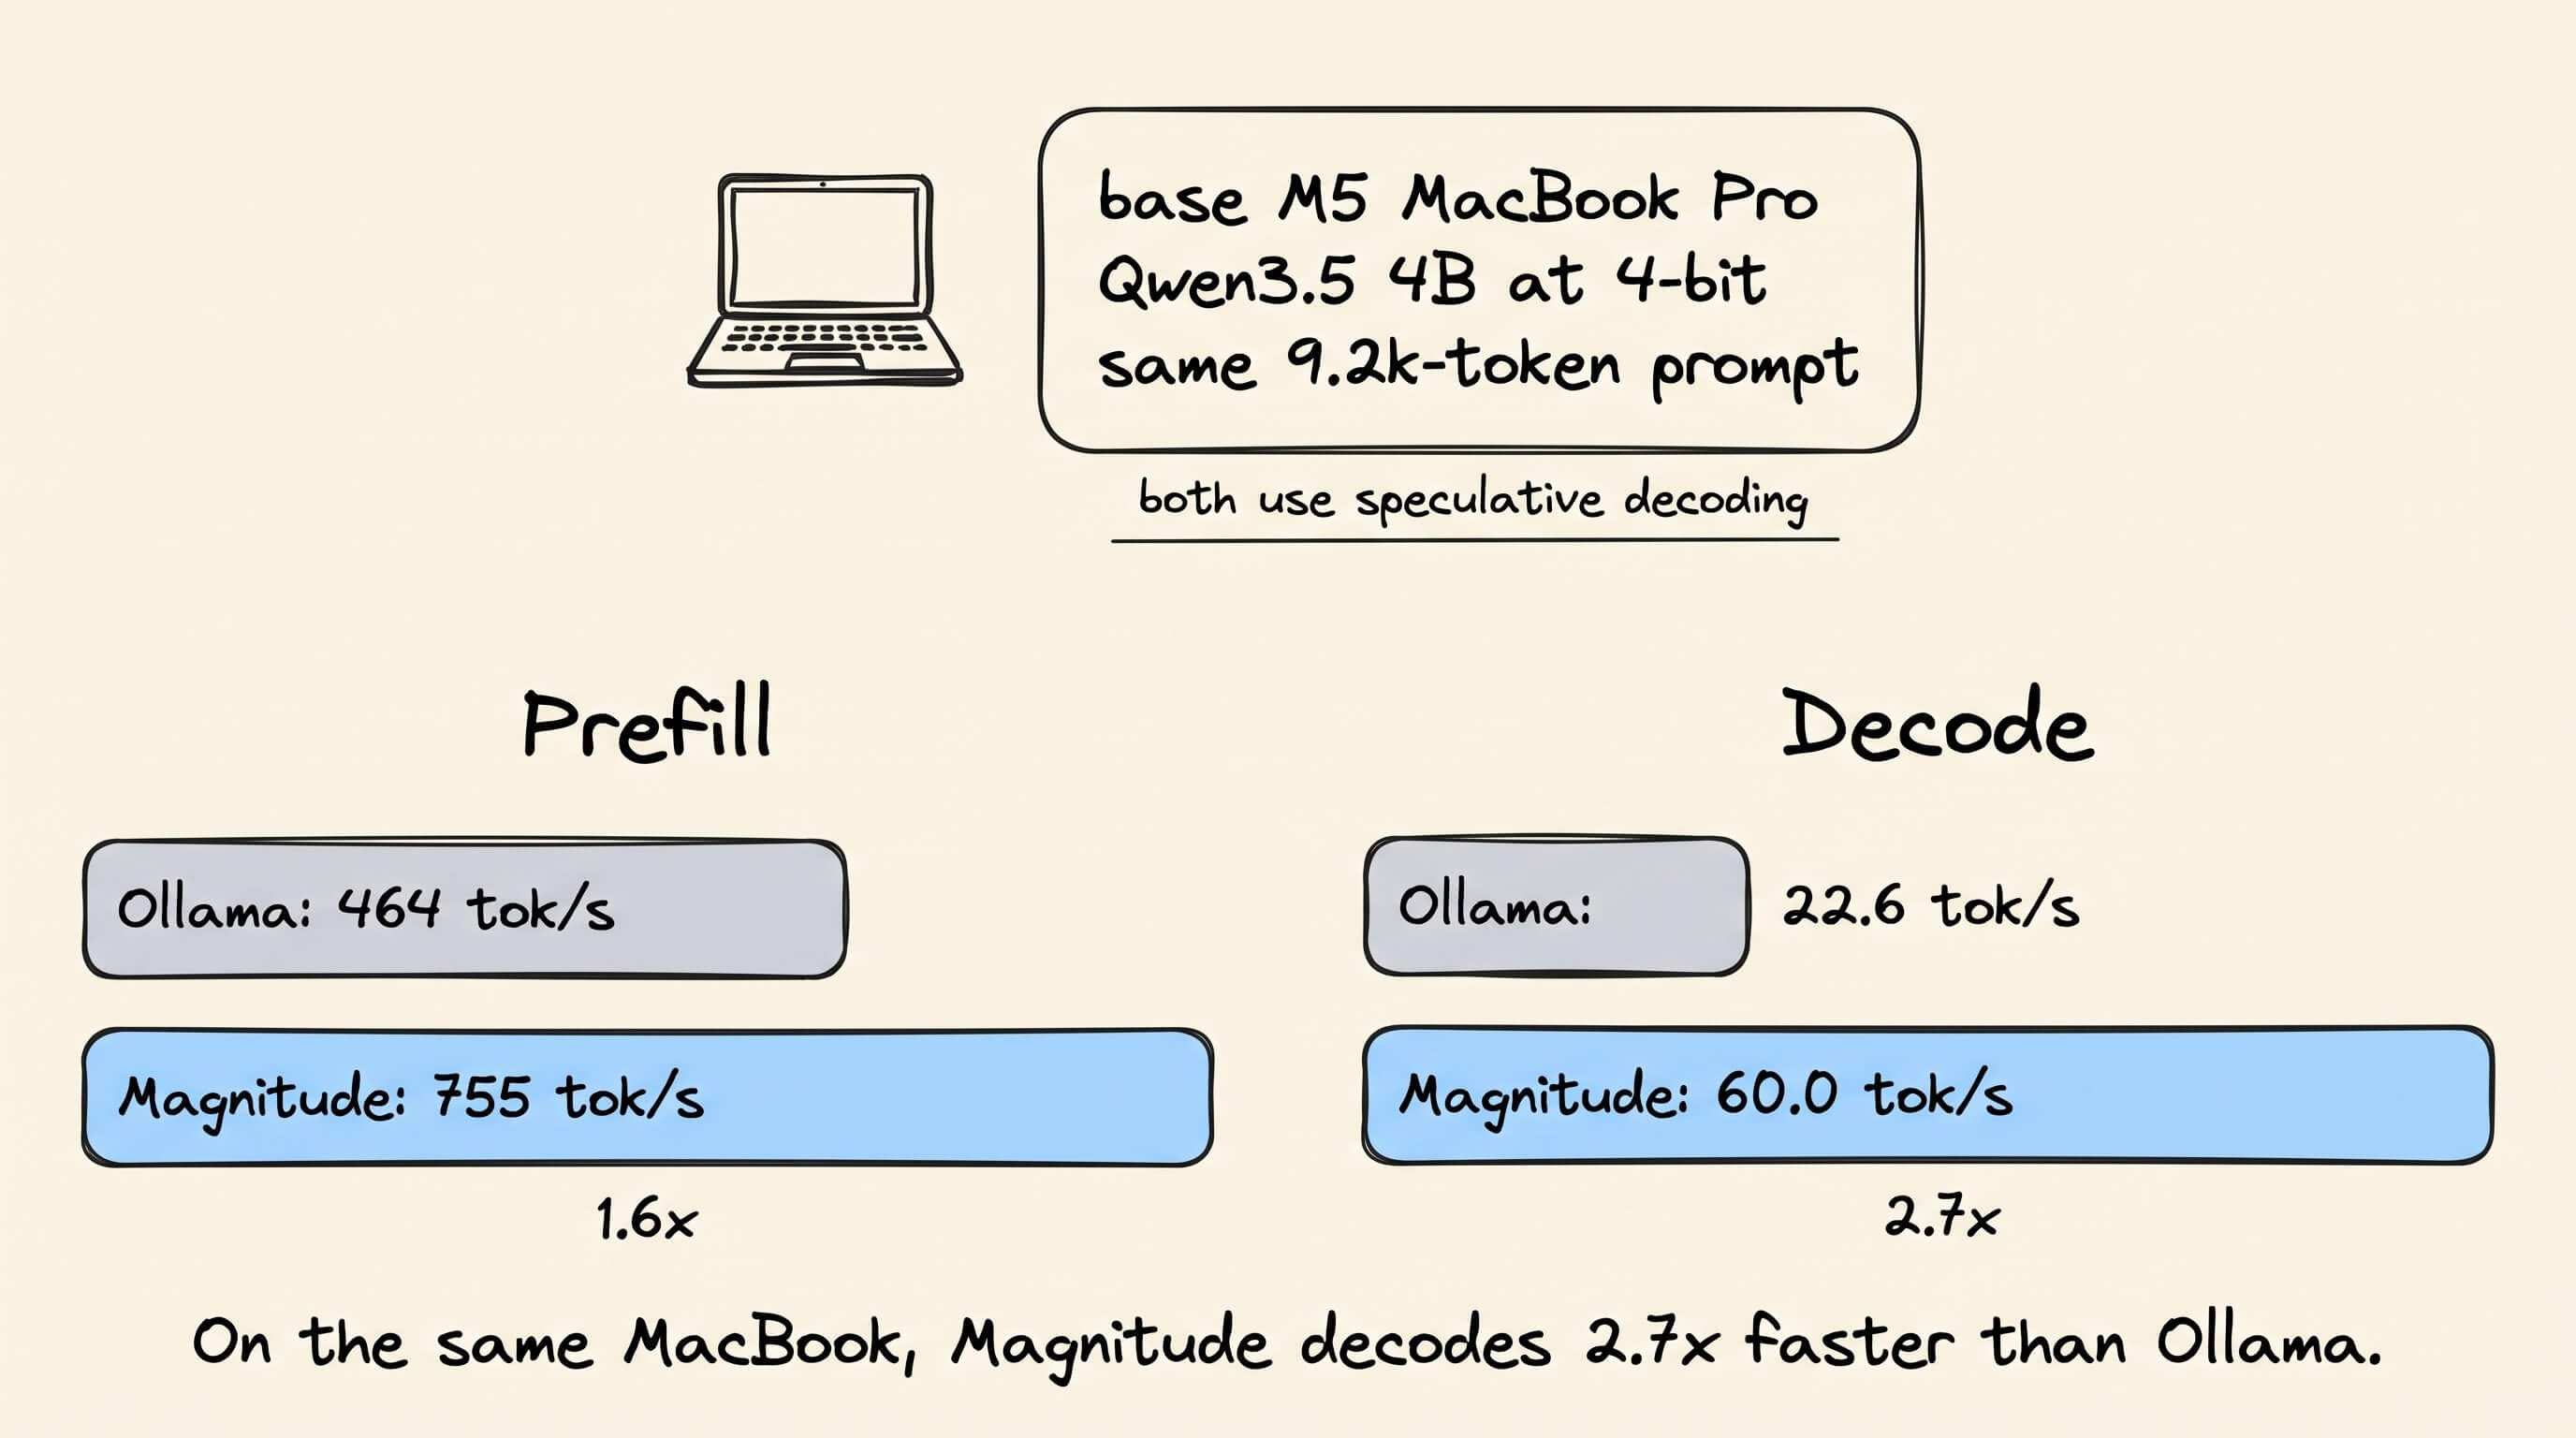
This open-source engine generates tokens 2.7x faster than Ollama on a MacBook:
I tested it on a base M5 MacBook Pro with Qwen3.5 4B at 4-bit and the same 9.2k-token prompt. Ollama ran its MTP build, so both had speculative decoding.
Prefill: Ollama 464 tok/s, Magnitude 755 tok/s (1.6x)
Decode: Ollama 22.6 tok/s, Magnitude 60.0 tok/s (2.7x)
End-to-end, Magnitude finished in half the time
The video above shows both runs side by side.
The Ollama numbers don’t mean it’s badly built. Its kernels were simply tuned in advance.
A kernel is the small GPU program behind every matrix multiply and attention step. Its speed depends on choices like how work is split across GPU cores and how data moves through memory.
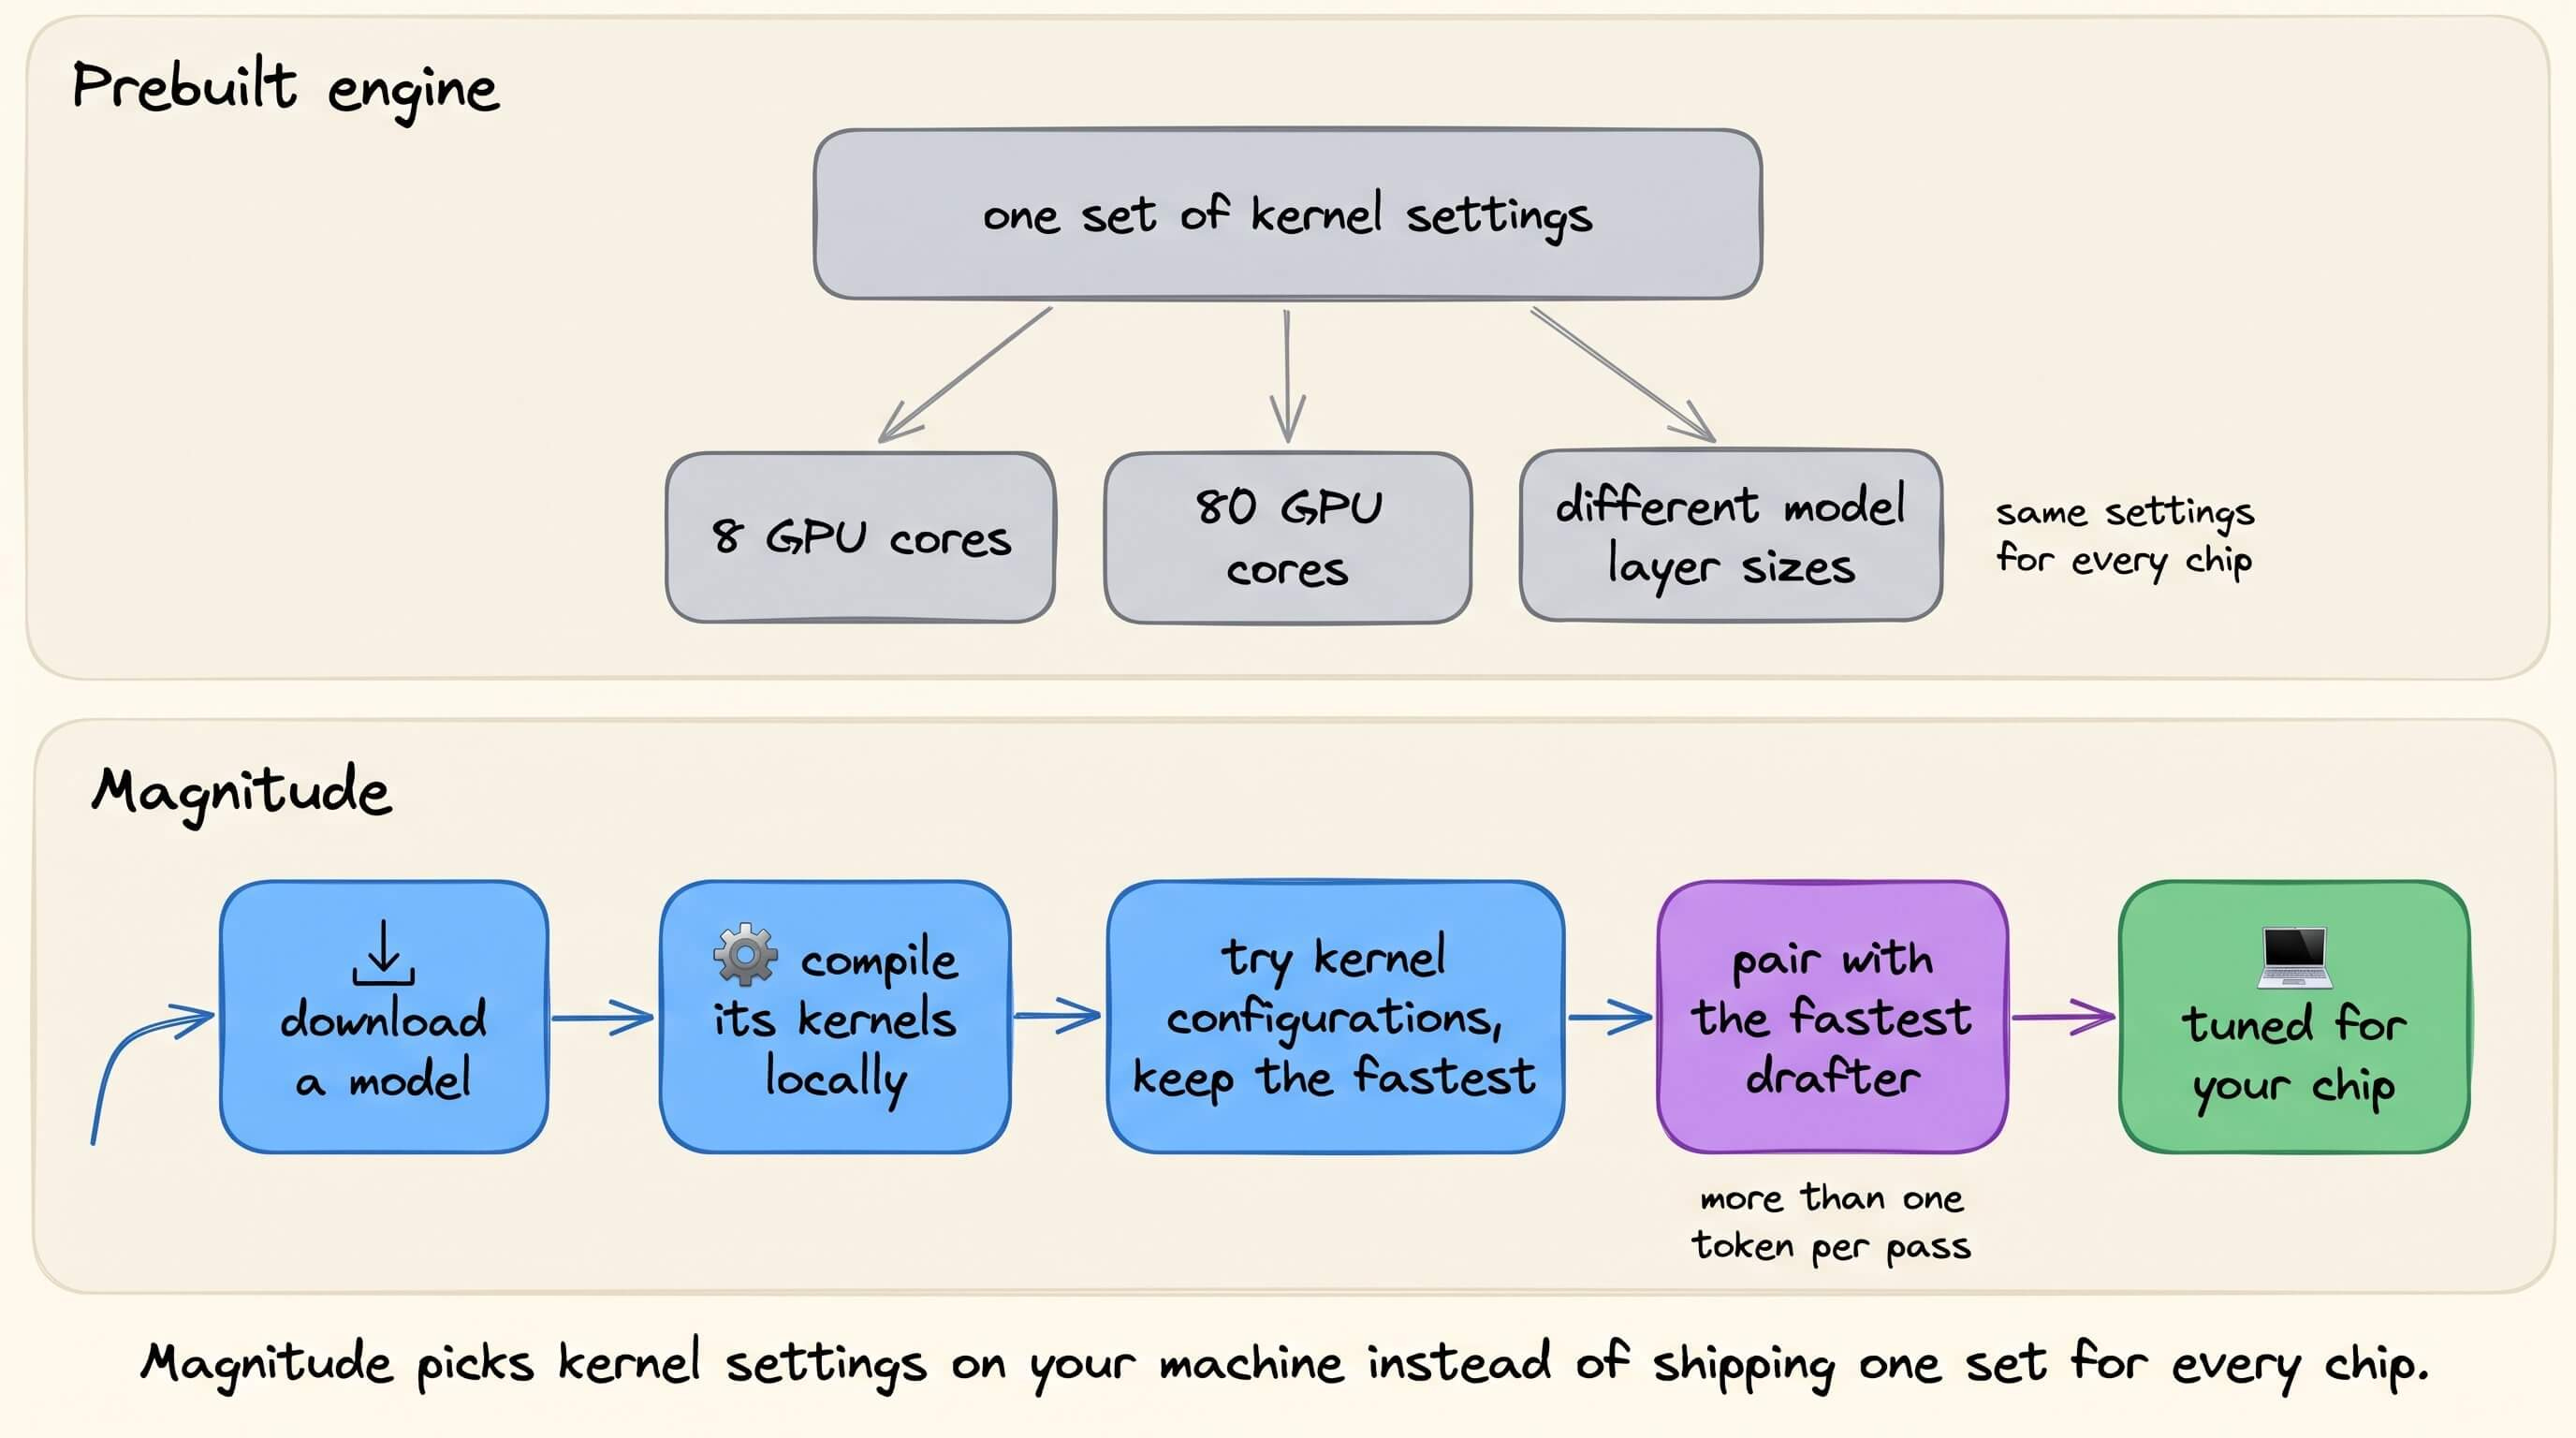
The best choices change with every chip. Apple Silicon alone spans 8 to 80 GPU cores and under 70 to over 800 GB/s of bandwidth, and every model has its own layer sizes.
A prebuilt engine has to pick one set of settings for all of them, so most local setups run on a compromise.
Magnitude replaces that compromise with tuning on your machine:
↳ When you download a model, it compiles that model’s kernels locally.
↳ It tries different kernel configurations and keeps whichever runs fastest on your chip.
↳ It pairs each model with the fastest speculative decoding drafter it has found, so each pass of the model produces more than one token.
This matters most for agents. Every file and tool output has to be processed before the model writes anything, and that prefill step is where kernel efficiency shows up. Concurrent sessions also share prefix caches, so parallel agents don’t slow each other down.
Magnitude is an open-source (Apache 2.0) inference engine written in Rust. It plugs into Claude Code, Codex, OpenCode, Pi and other agents with one click.
GitHub repo: github.com/magnitudedev/magnitude
(don’t forget to star it 🌟)
Why DeepSeek stores its KV cache on disk
They just open-sourced DeepInfer, the inference stack behind cache hits that return the first token up to 26x faster.
When a request repeats a long prefix, like a system prompt or earlier chat turns, the server can reuse the KV cache it already computed instead of running prefill again.
Ideally, you’d expect that cache to sit in GPU memory, since disk is supposed to be far too slow for anything on the request path.
In practice, DeepSeek keeps it on SSDs.
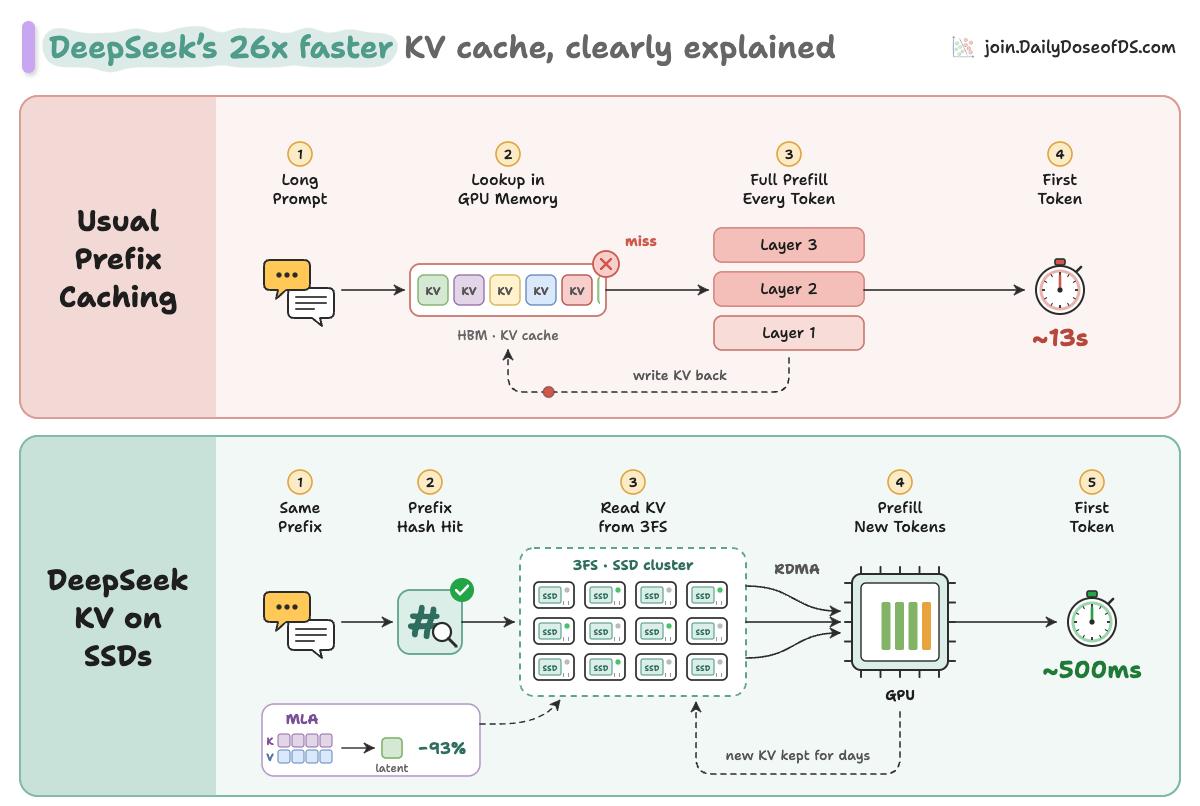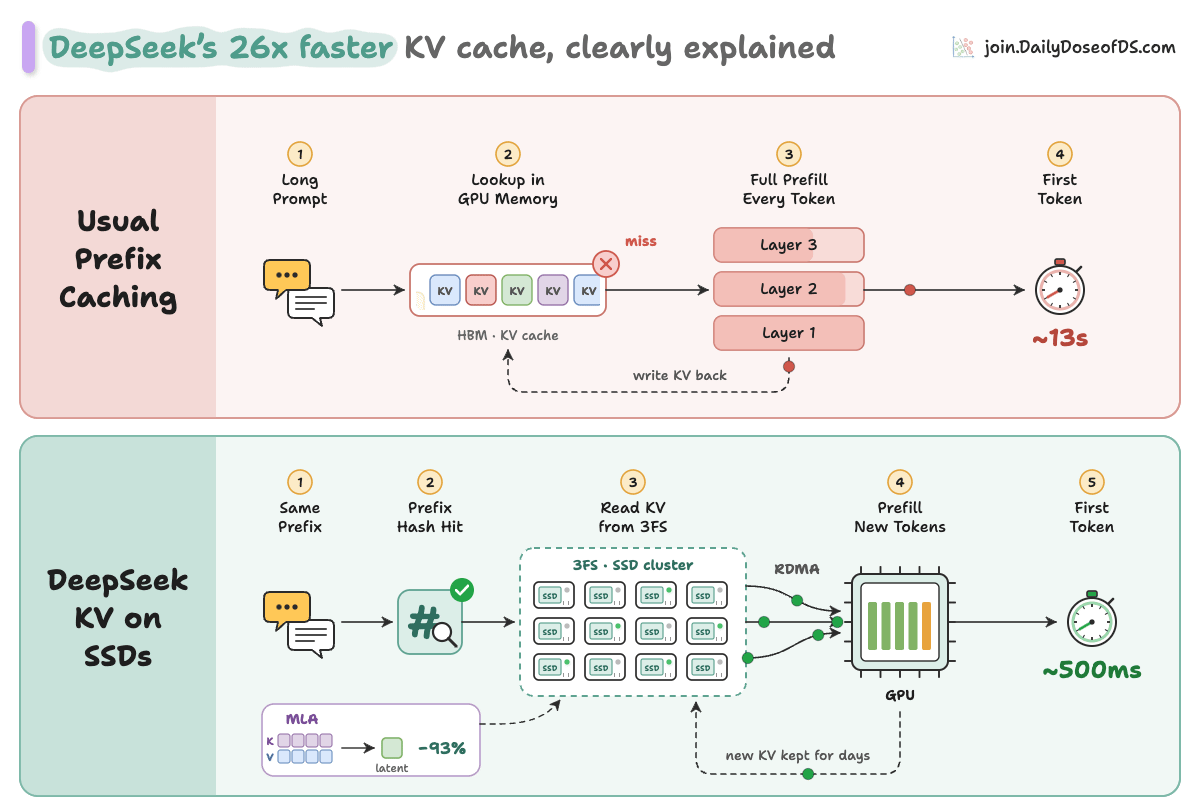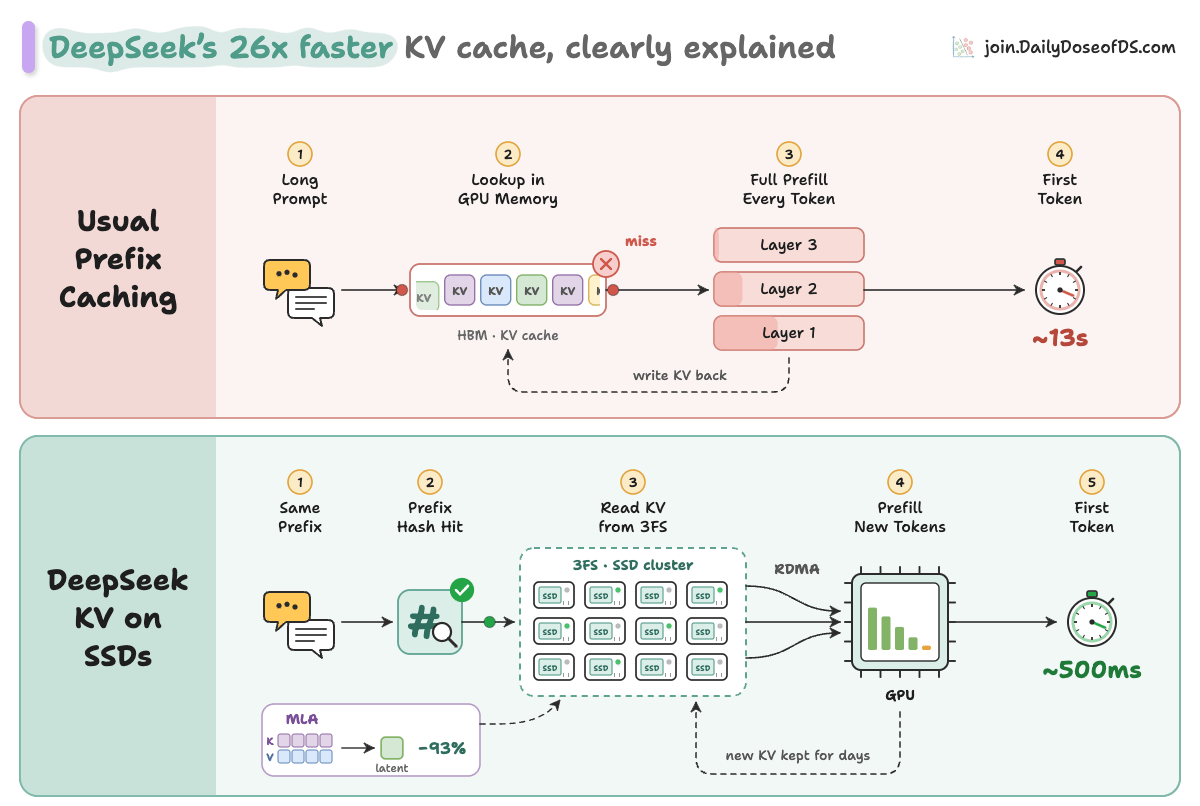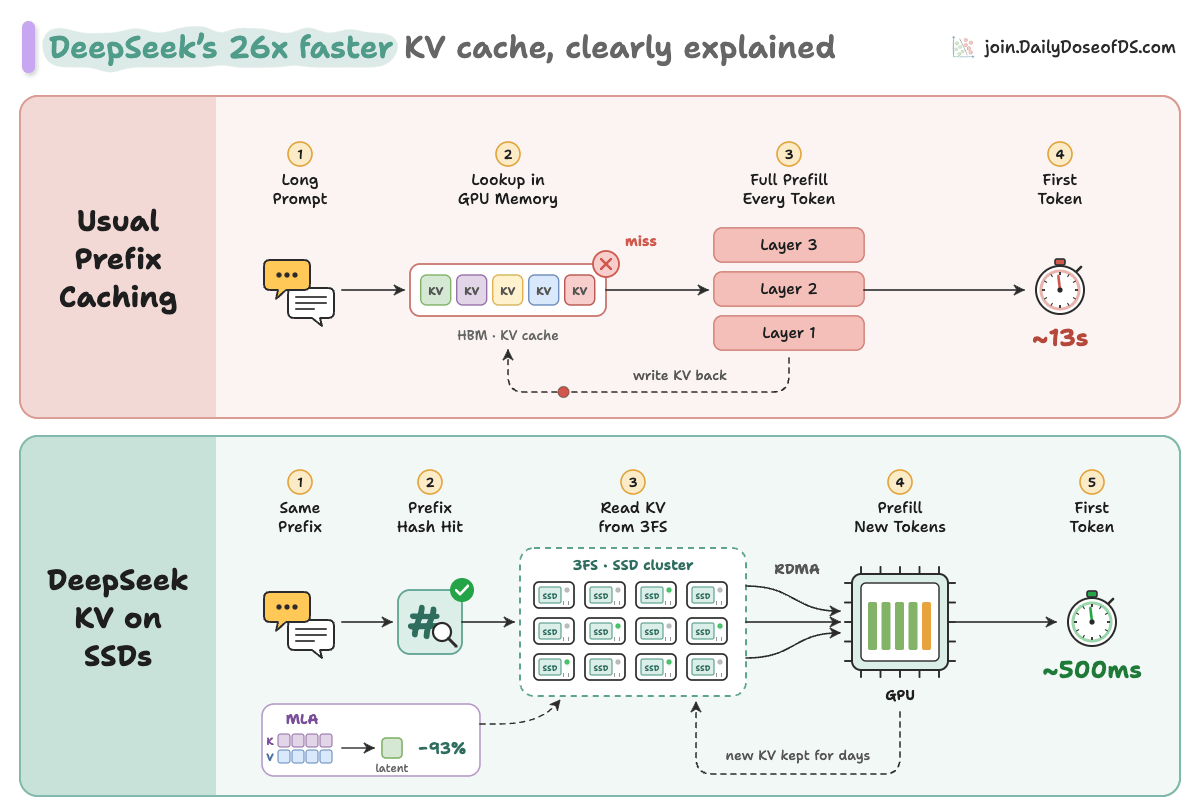
When DeepSeek launched this in 2024, a 128K-token prompt that hit the cache got its first token in 500ms instead of 13s.
And in one day of production traffic last year, 56% of all input tokens were served straight from disk.
So disk isn’t the bottleneck here, as long as what you store is small enough and the storage is wide enough.
Let’s understand how this works.
1. Why reuse the KV cache at all
Before generating anything, an LLM reads the whole prompt and computes a key and a value for every token in every layer.
This is prefill, and on long prompts it’s the slow part.
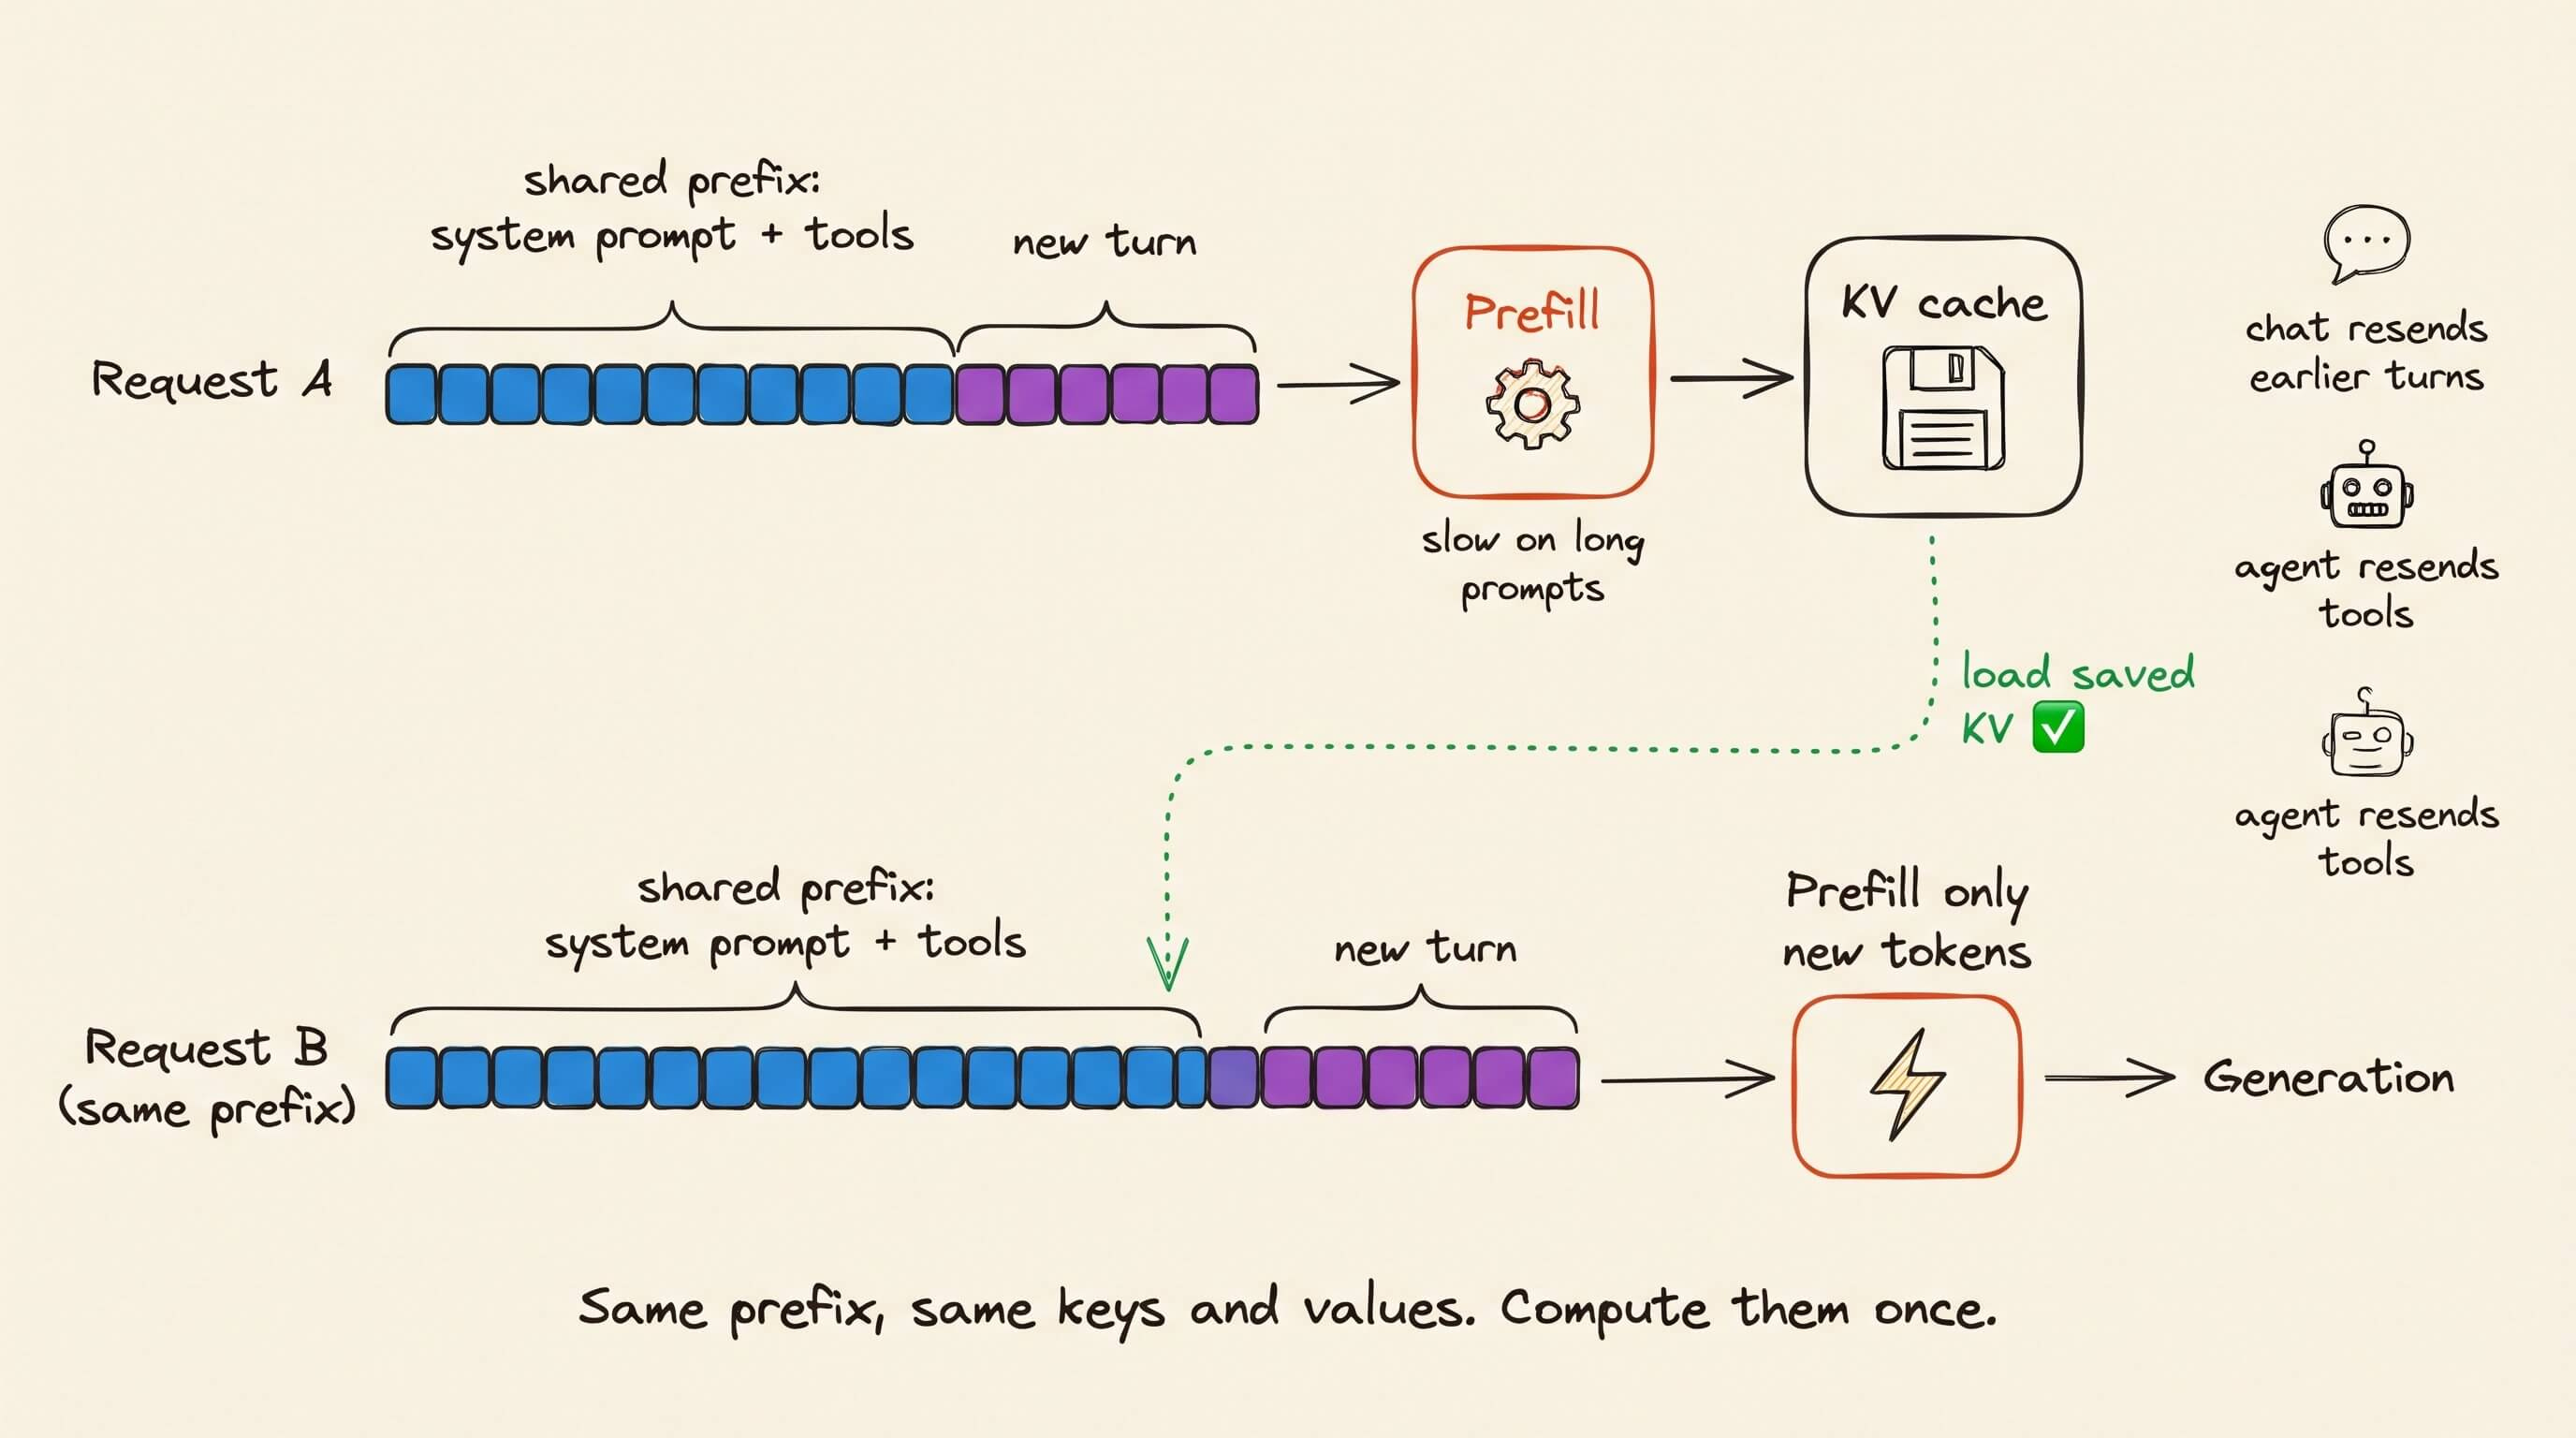
Many requests start the same way.
For instance, a chat resends every earlier turn, and an agent resends the same system prompt and tool definitions on every call.
If those KV are saved, the next request with the same prefix loads them and only computes the new tokens.
2. Why GPU memory is the default
Every token stores KV in every layer, so on a standard model a long prompt’s KV cache runs into many GBs.
Reading that much from disk can take longer than recomputing it on the GPU.
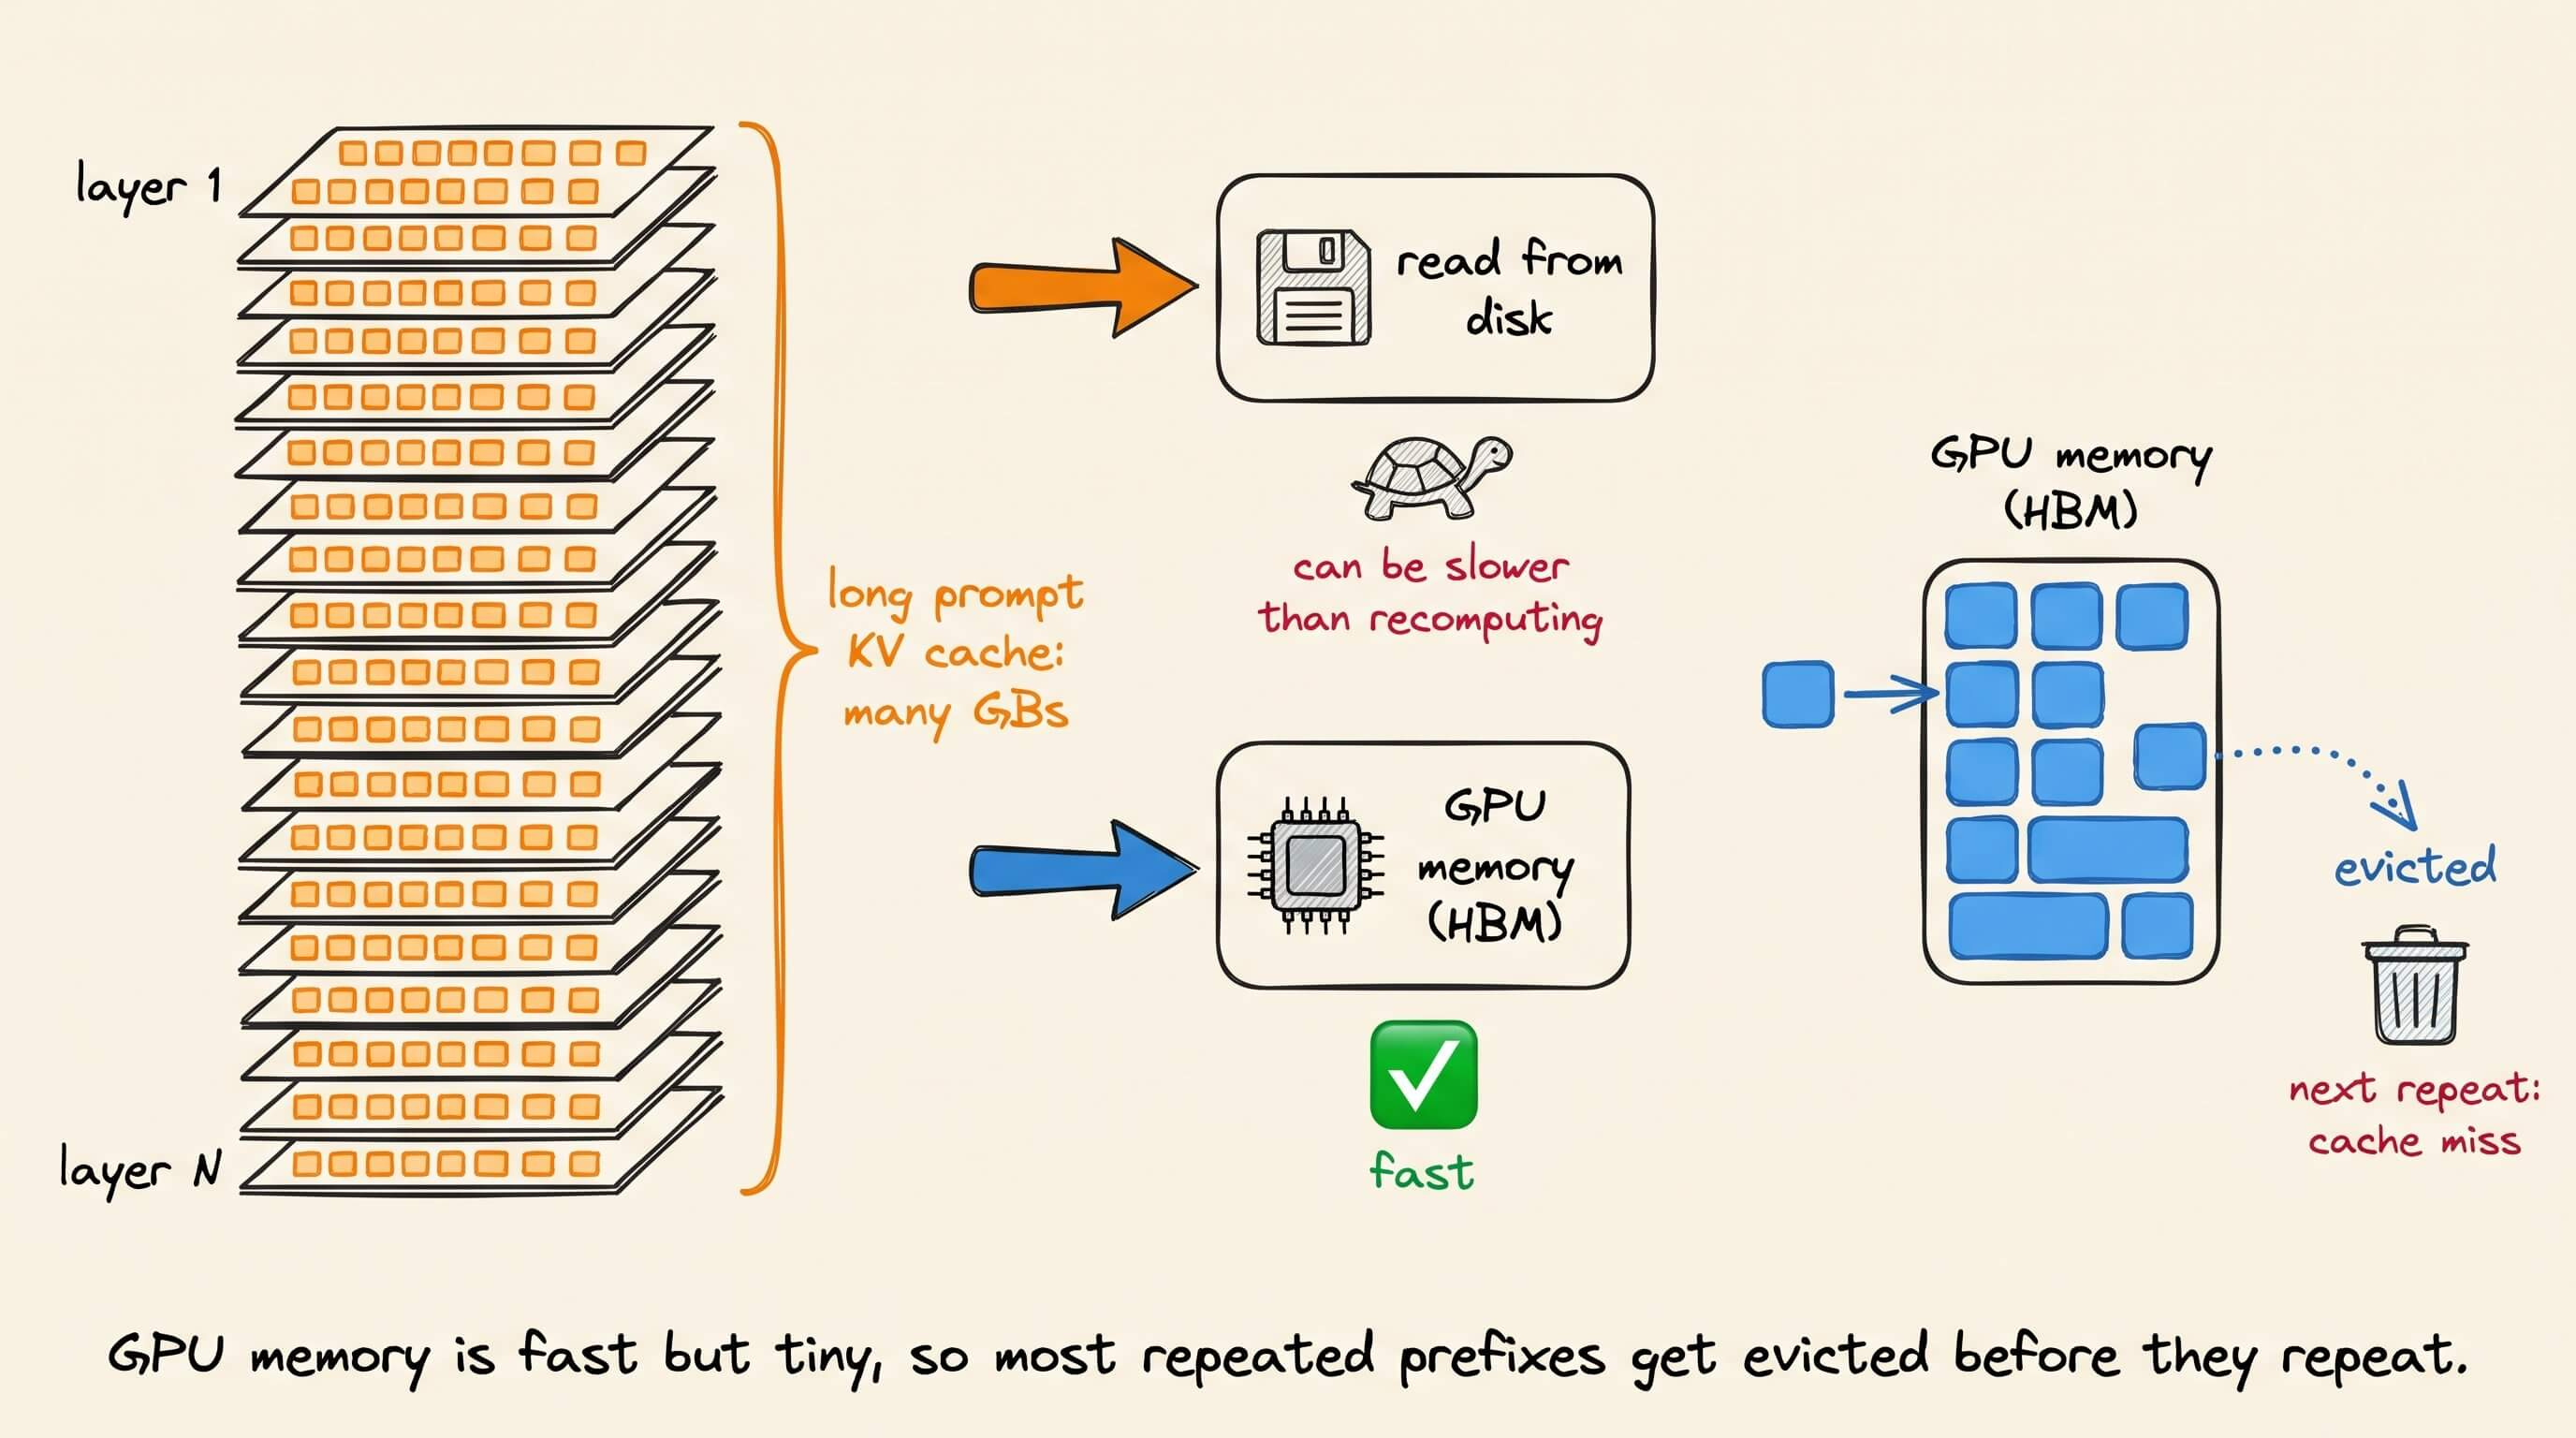
So engines keep it in GPU memory.
But GPU memory is small, so old prefixes get evicted fast and many repeats miss.
3. DeepSeek made the KV cache small
DeepSeek-V2 introduced Multi-head Latent Attention (MLA).
Instead of storing separate KV for every attention head, MLA stores one small compressed vector per token per layer. The keys and values are rebuilt from it during attention.
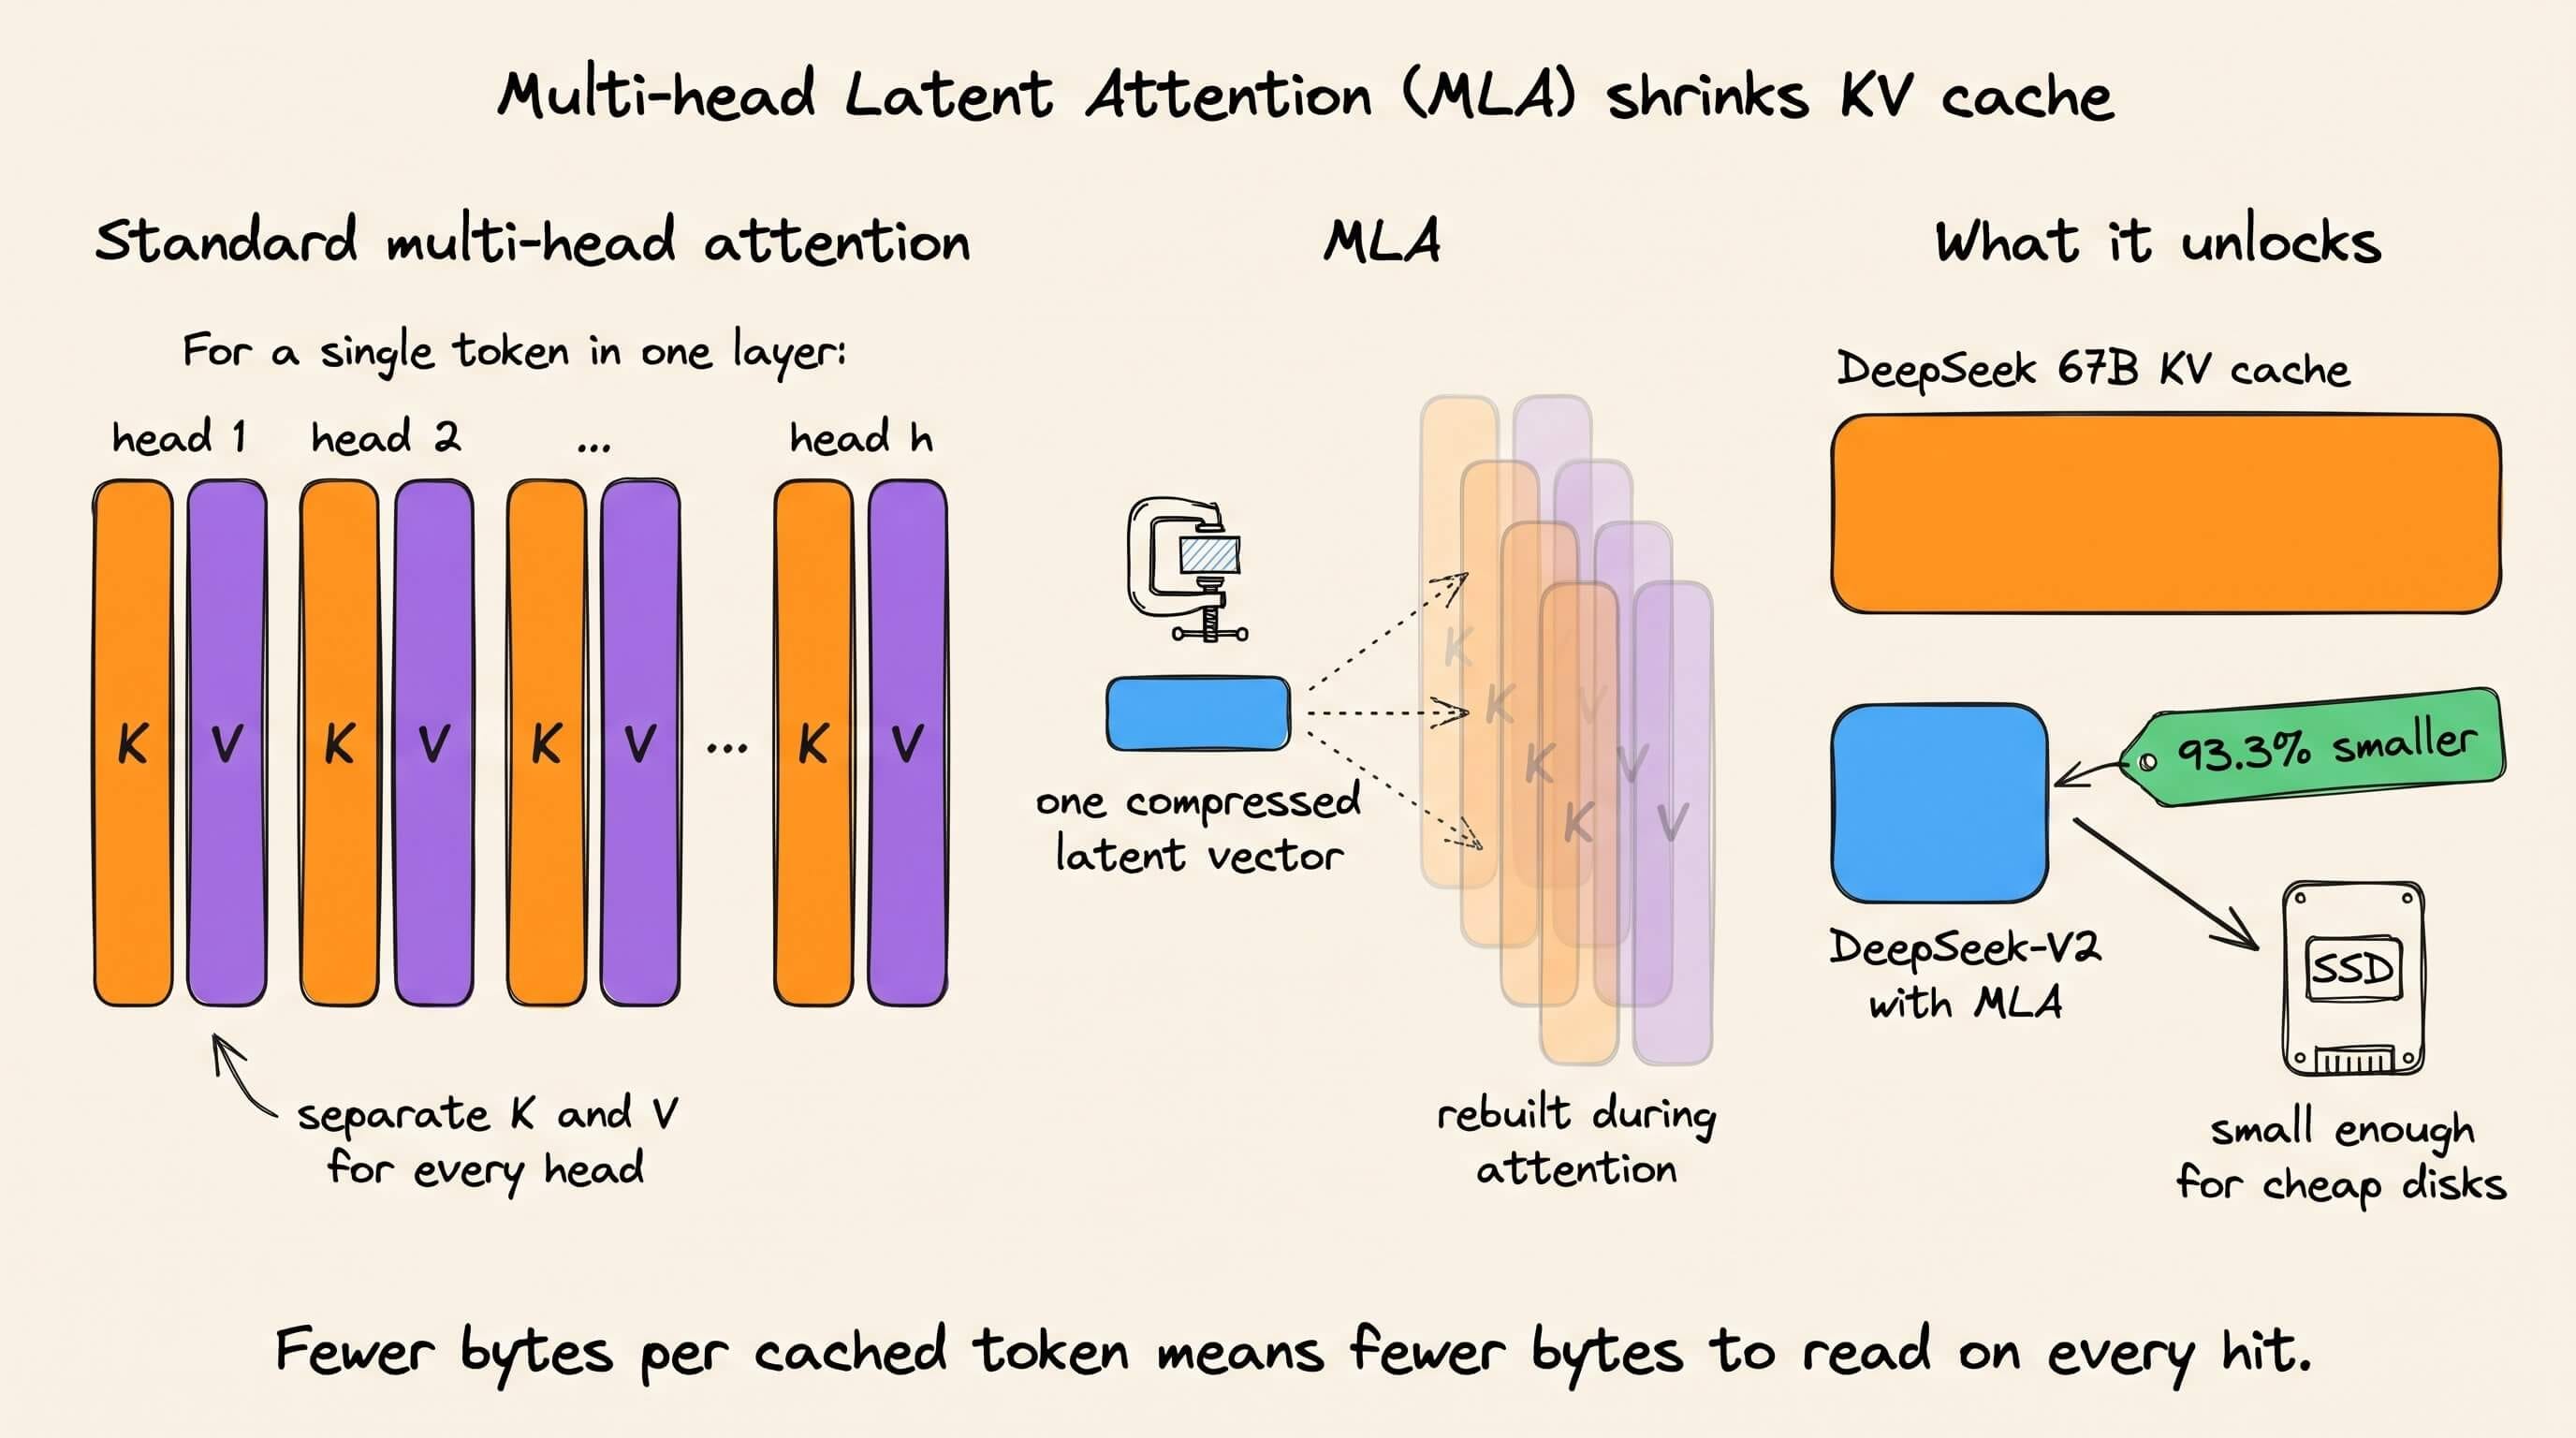
In the V2 paper, this cut the KV cache by 93.3% compared to DeepSeek’s earlier 67B model.
That made the KV cache small enough to store on low-cost disks.
Fewer bytes per cached token means fewer bytes to read on every hit, and that made loading from SSD faster than recomputing.
4. 3FS reads it from many SSDs at once
One SSD would still be too slow, so the cache lives on 3FS, DeepSeek’s own distributed file system.
3FS splits files into chunks and spreads them across thousands of SSDs on many storage nodes. A read pulls chunks from many drives in parallel, so their bandwidth adds up.
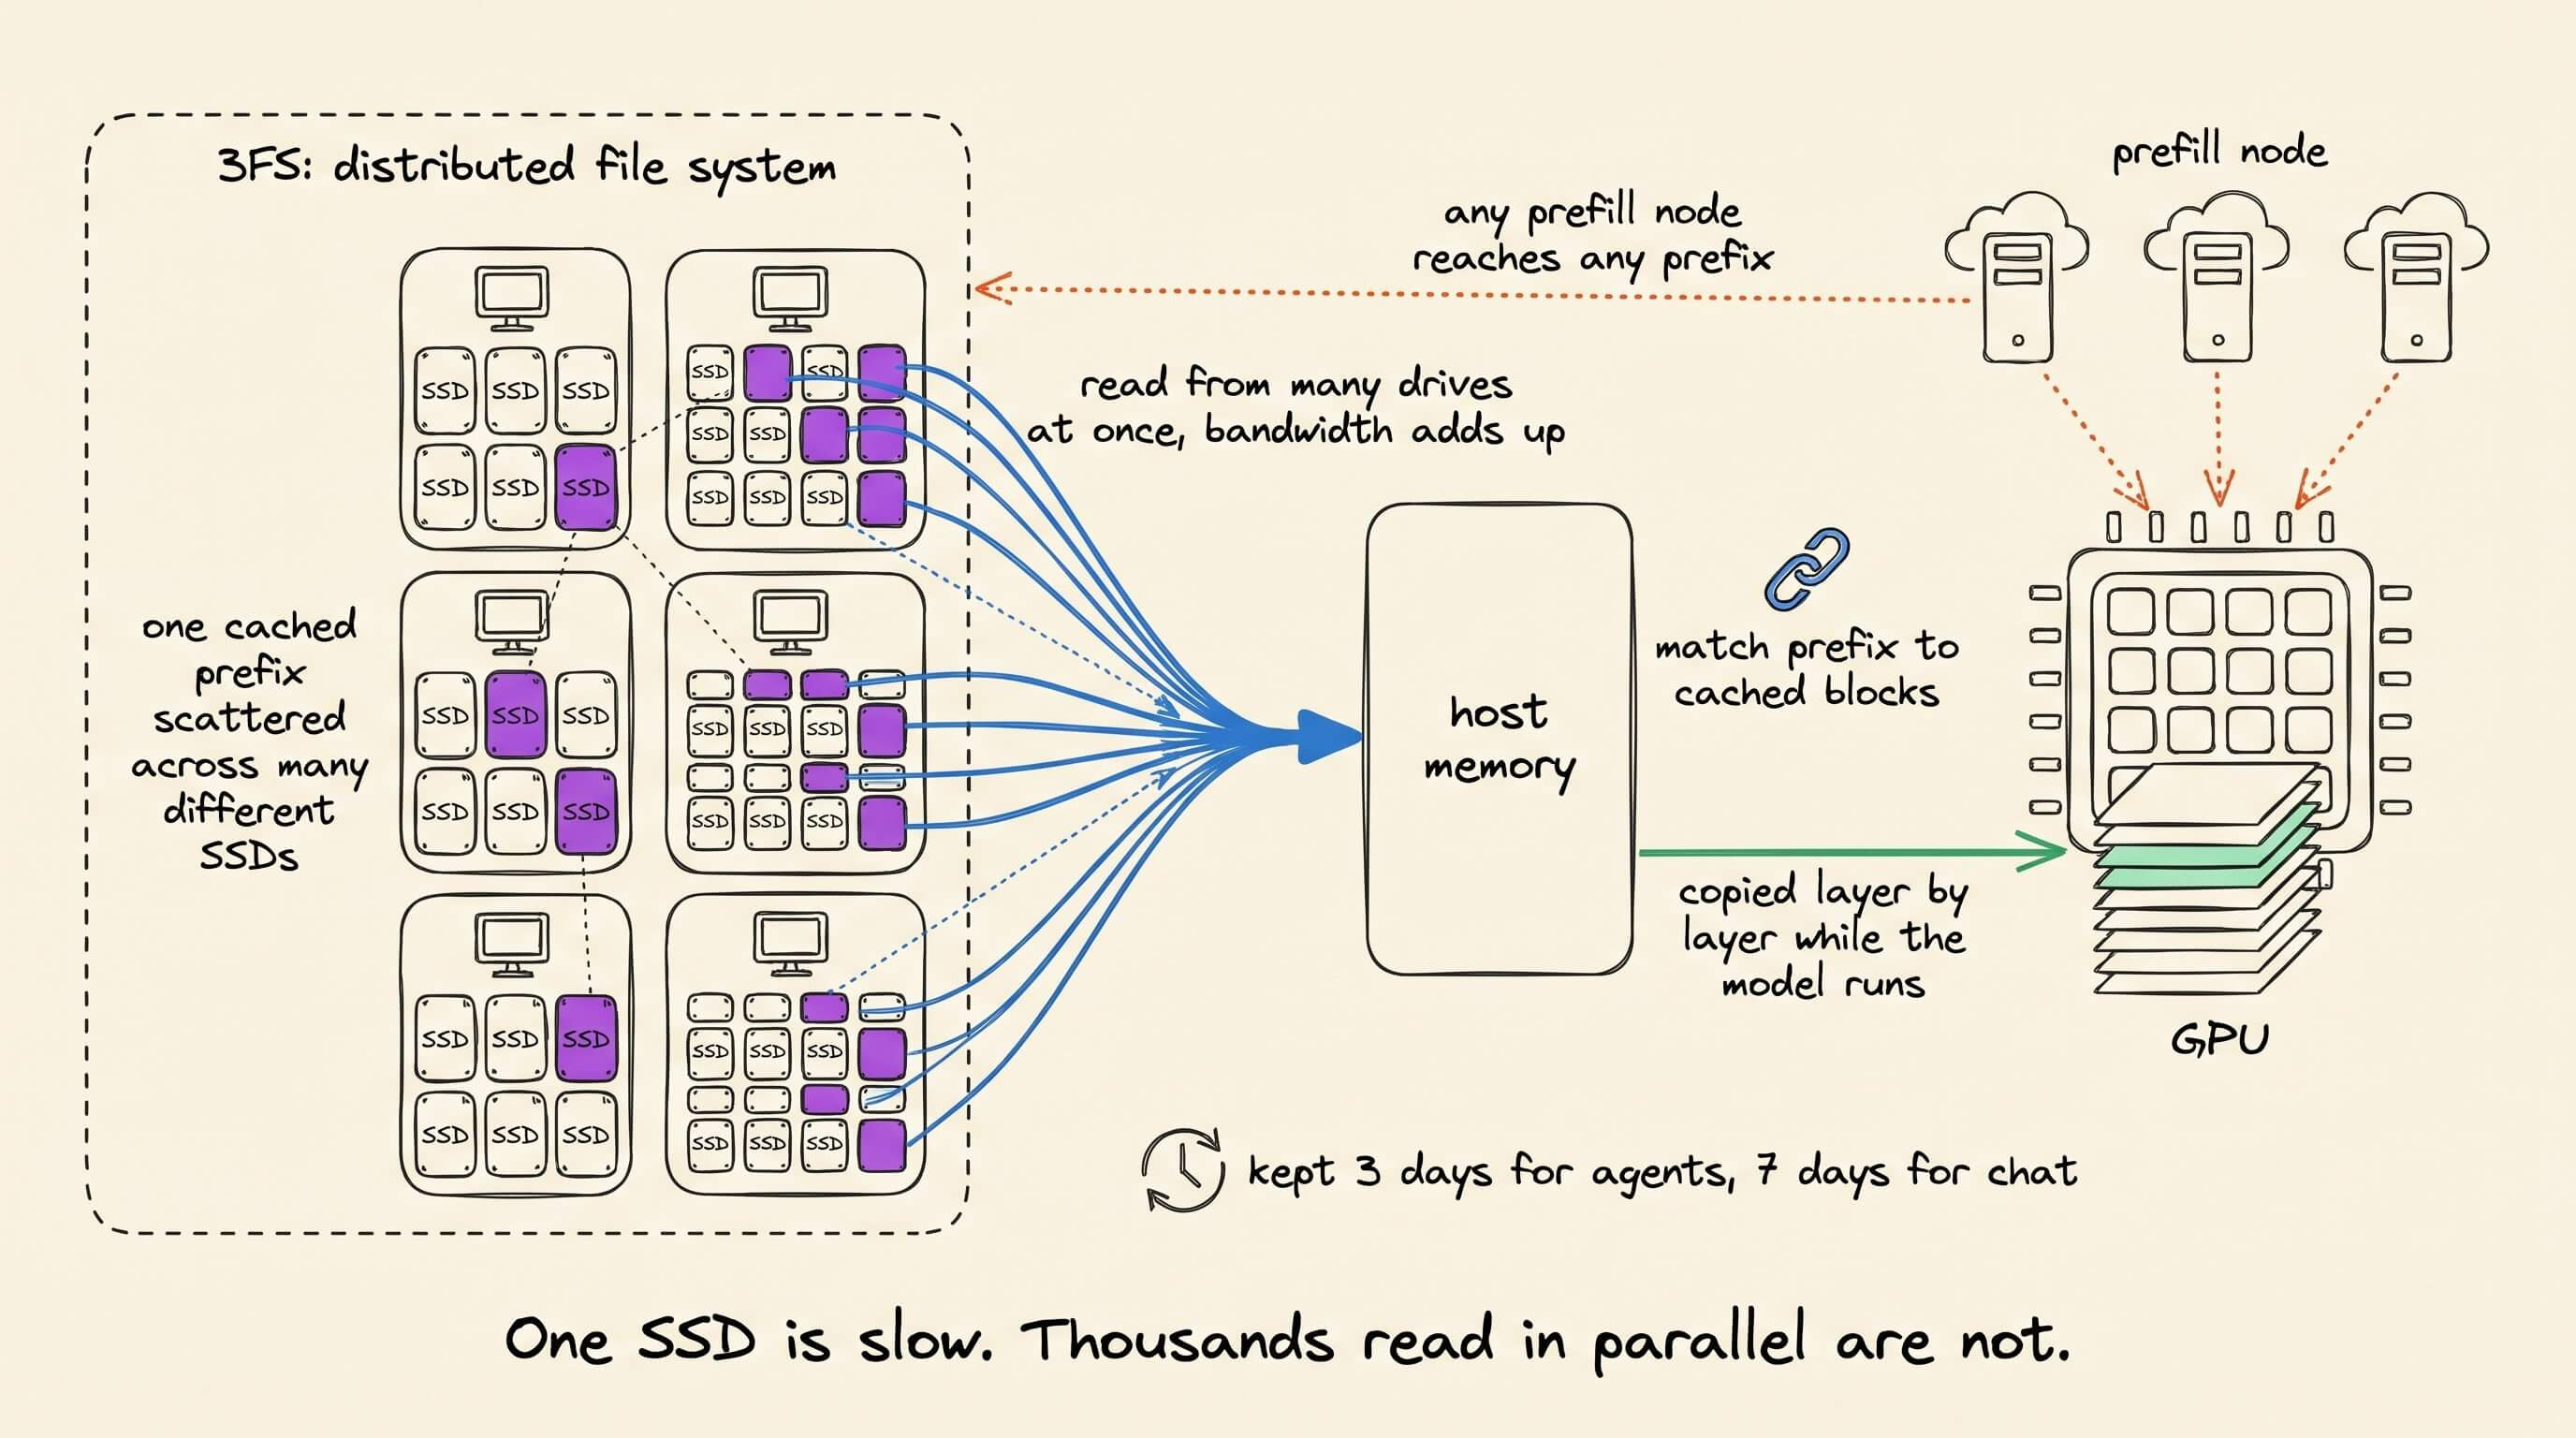
When a request arrives, the system matches its prefix against cached blocks and fetches those blocks from 3FS into host memory.
Then it copies them to the GPU layer by layer while the model is already running.
And since every prefill machine can reach every cached prefix, a request doesn’t have to go back to the machine that served it last.
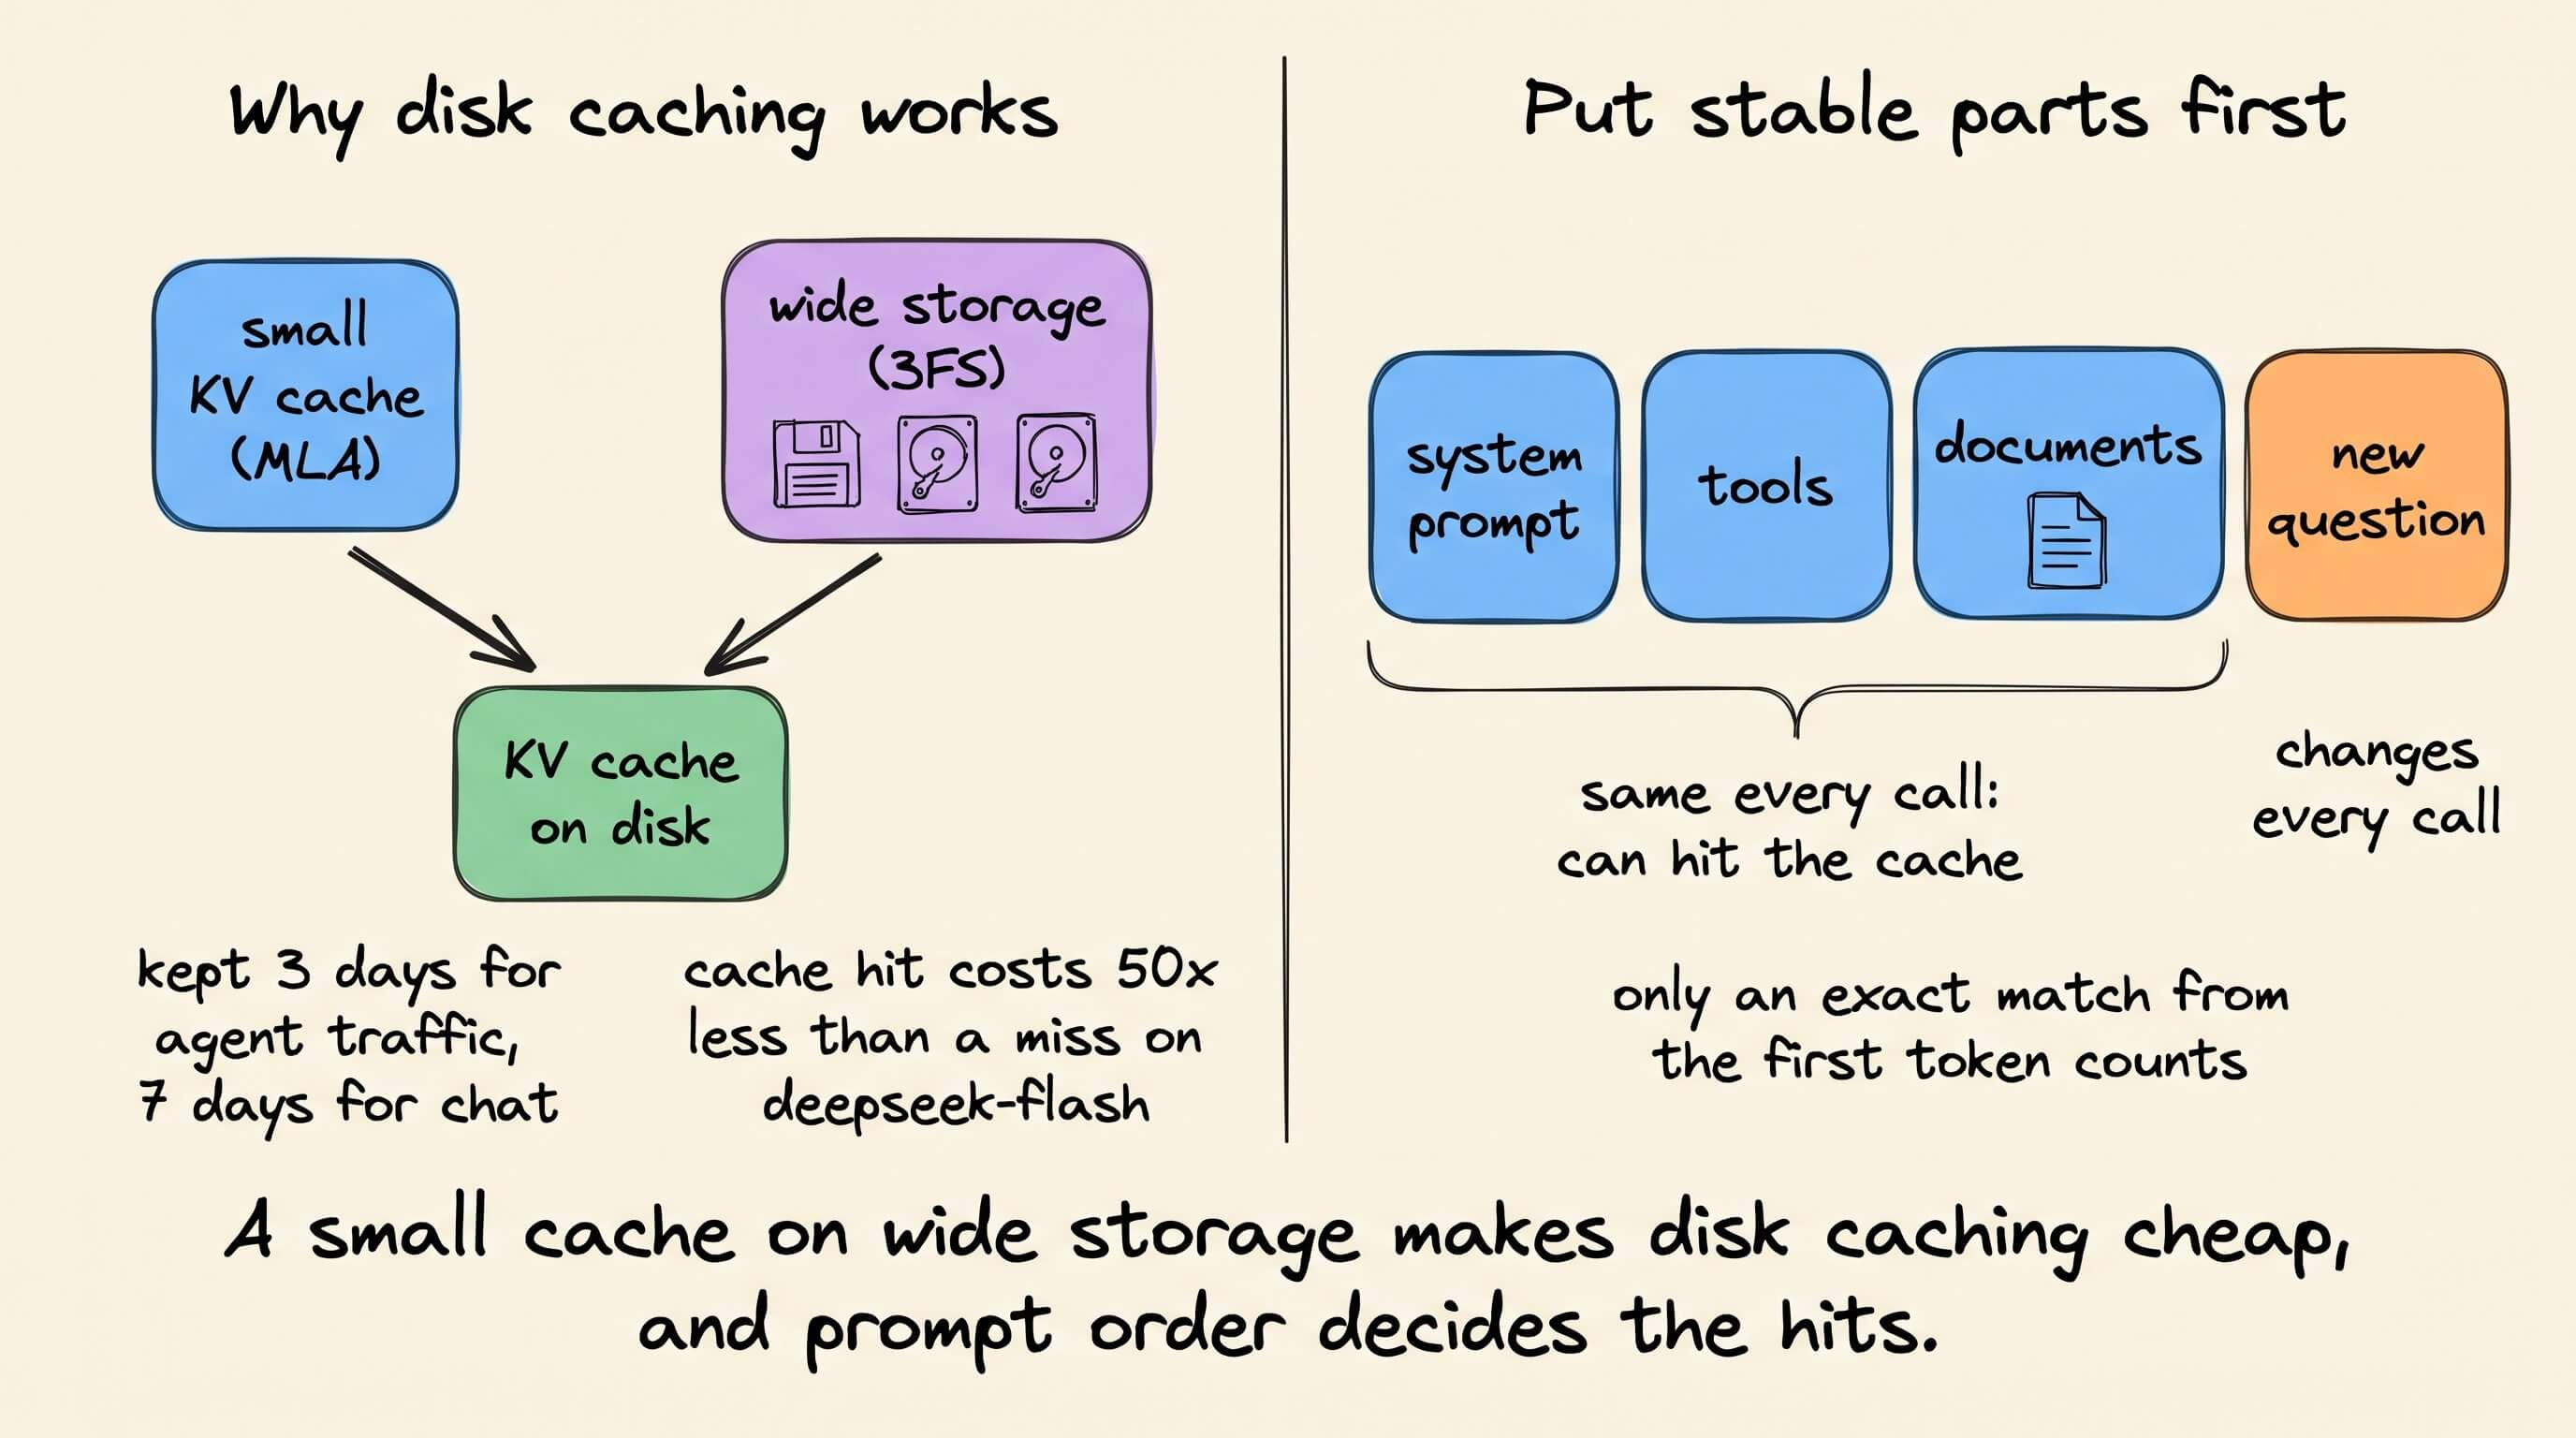
Disk is also cheap, so the cache can stay for days. As per the DeepInfer docs, cached prefixes are retained for 3 days for agent traffic and 7 days for chat.
Disk caching works when the KV cache is small and the storage is wide. DeepSeek got the first from its attention design and the second from 3FS.
This also shows up in the price. On deepseek-flash today, a cache hit costs 50x less than a miss.
If you use the API, keep the stable parts of your prompt, like the system prompt, tools, and documents, at the front. Only an exact match from the very first token counts as a hit.
That said, prefix caching is only one of the ways to manage the KV cache in LLM serving.
We wrote an open-access KV Cache Engineering article covering quantization and other ways to reduce cache memory, with code examples and their trade-offs.
👉 Over to you: Do you order your prompts for cache hits, or does every request start from scratch?
What is Early Exaggeration in tSNE?
tSNE algorithm has an early_exaggeration parameter:
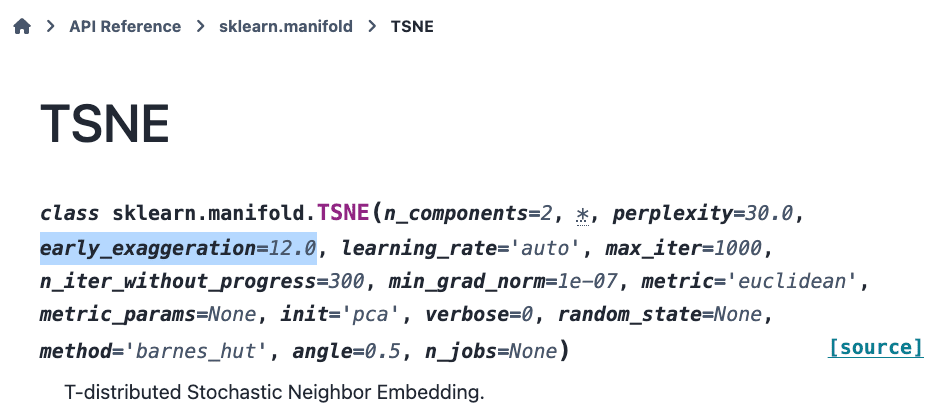
What is it, and how does it help?
Let’s understand this today, along with a strategy to improve it.
Let’s begin!
A brief about tSNE
To understand early exaggeration, we need to briefly overview how tSNE works.
The steps discussed below have been discussed in a mathematical manner here: Formulating and Implementing the t-SNE Algorithm From Scratch.
The core objective of tSNE is to project a given high-dimensional data into low-dimensions (mostly 2D) for visualisation.
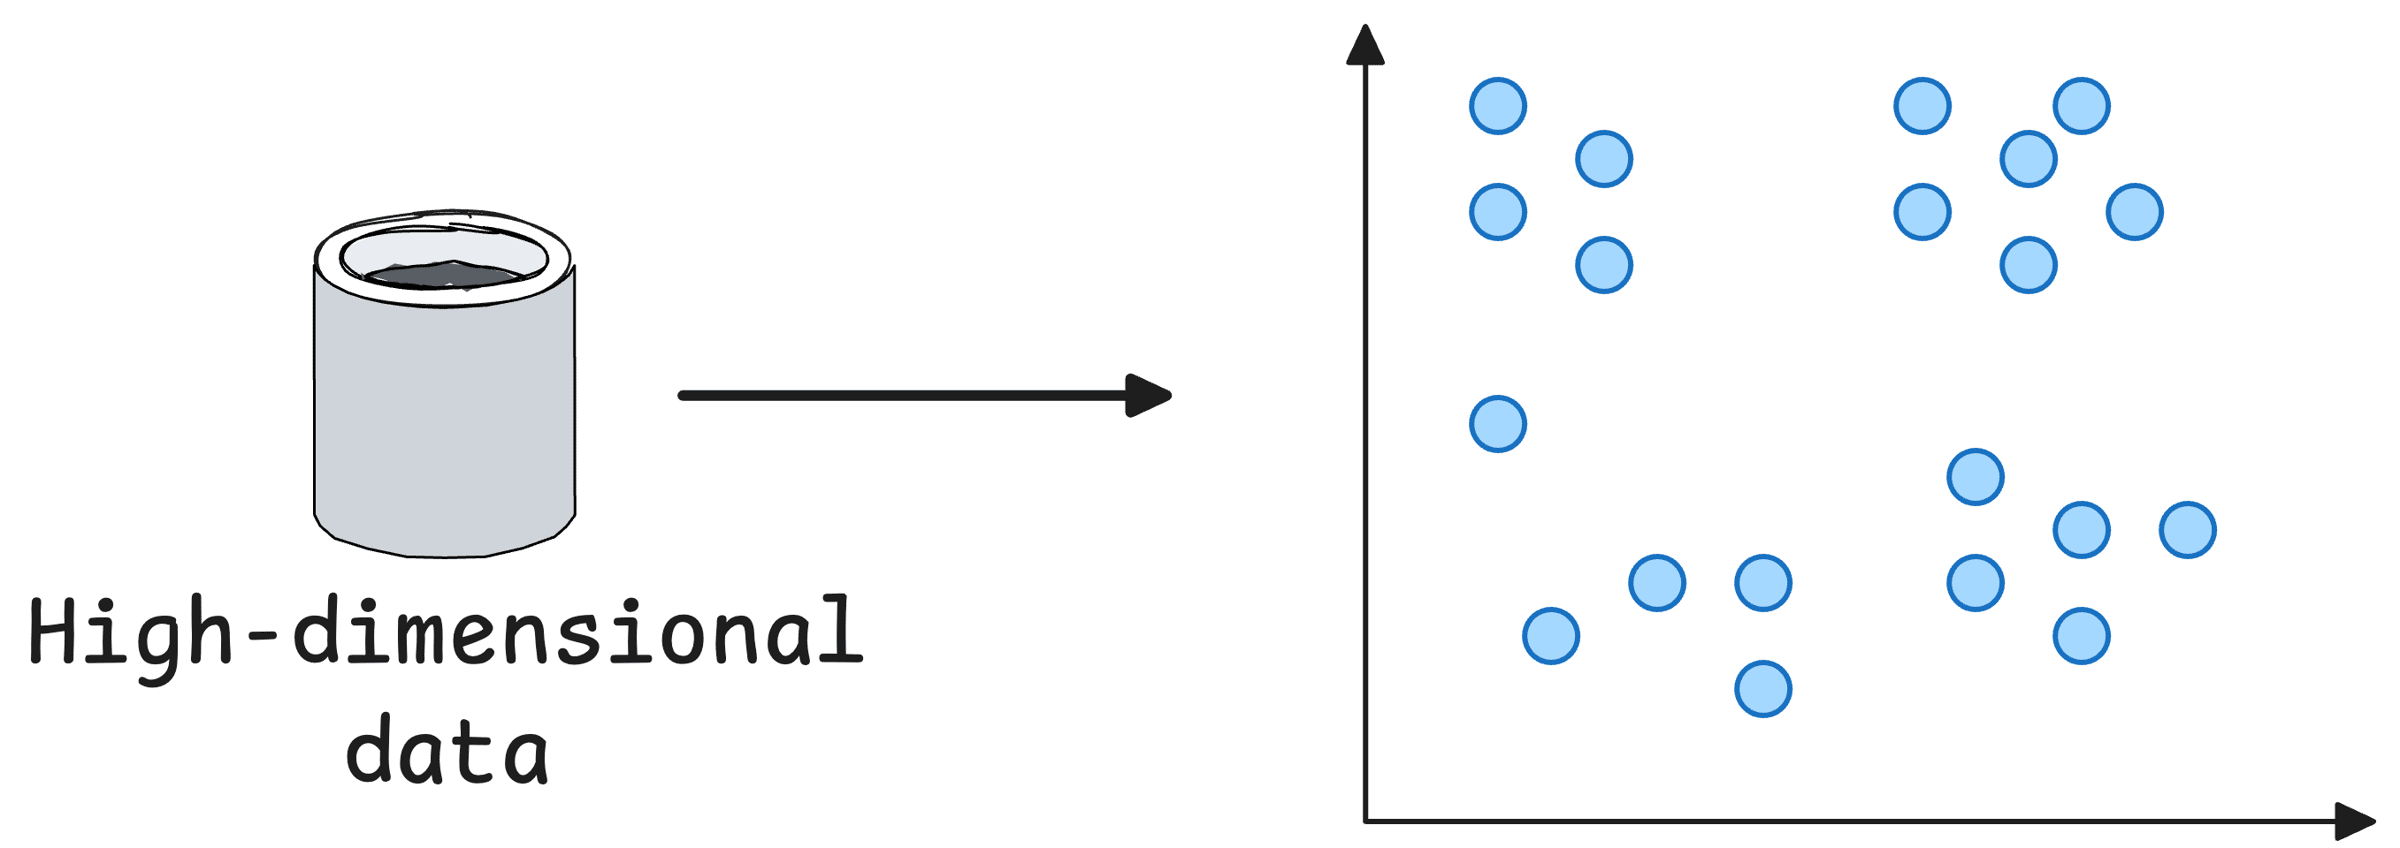
This is how we do it:
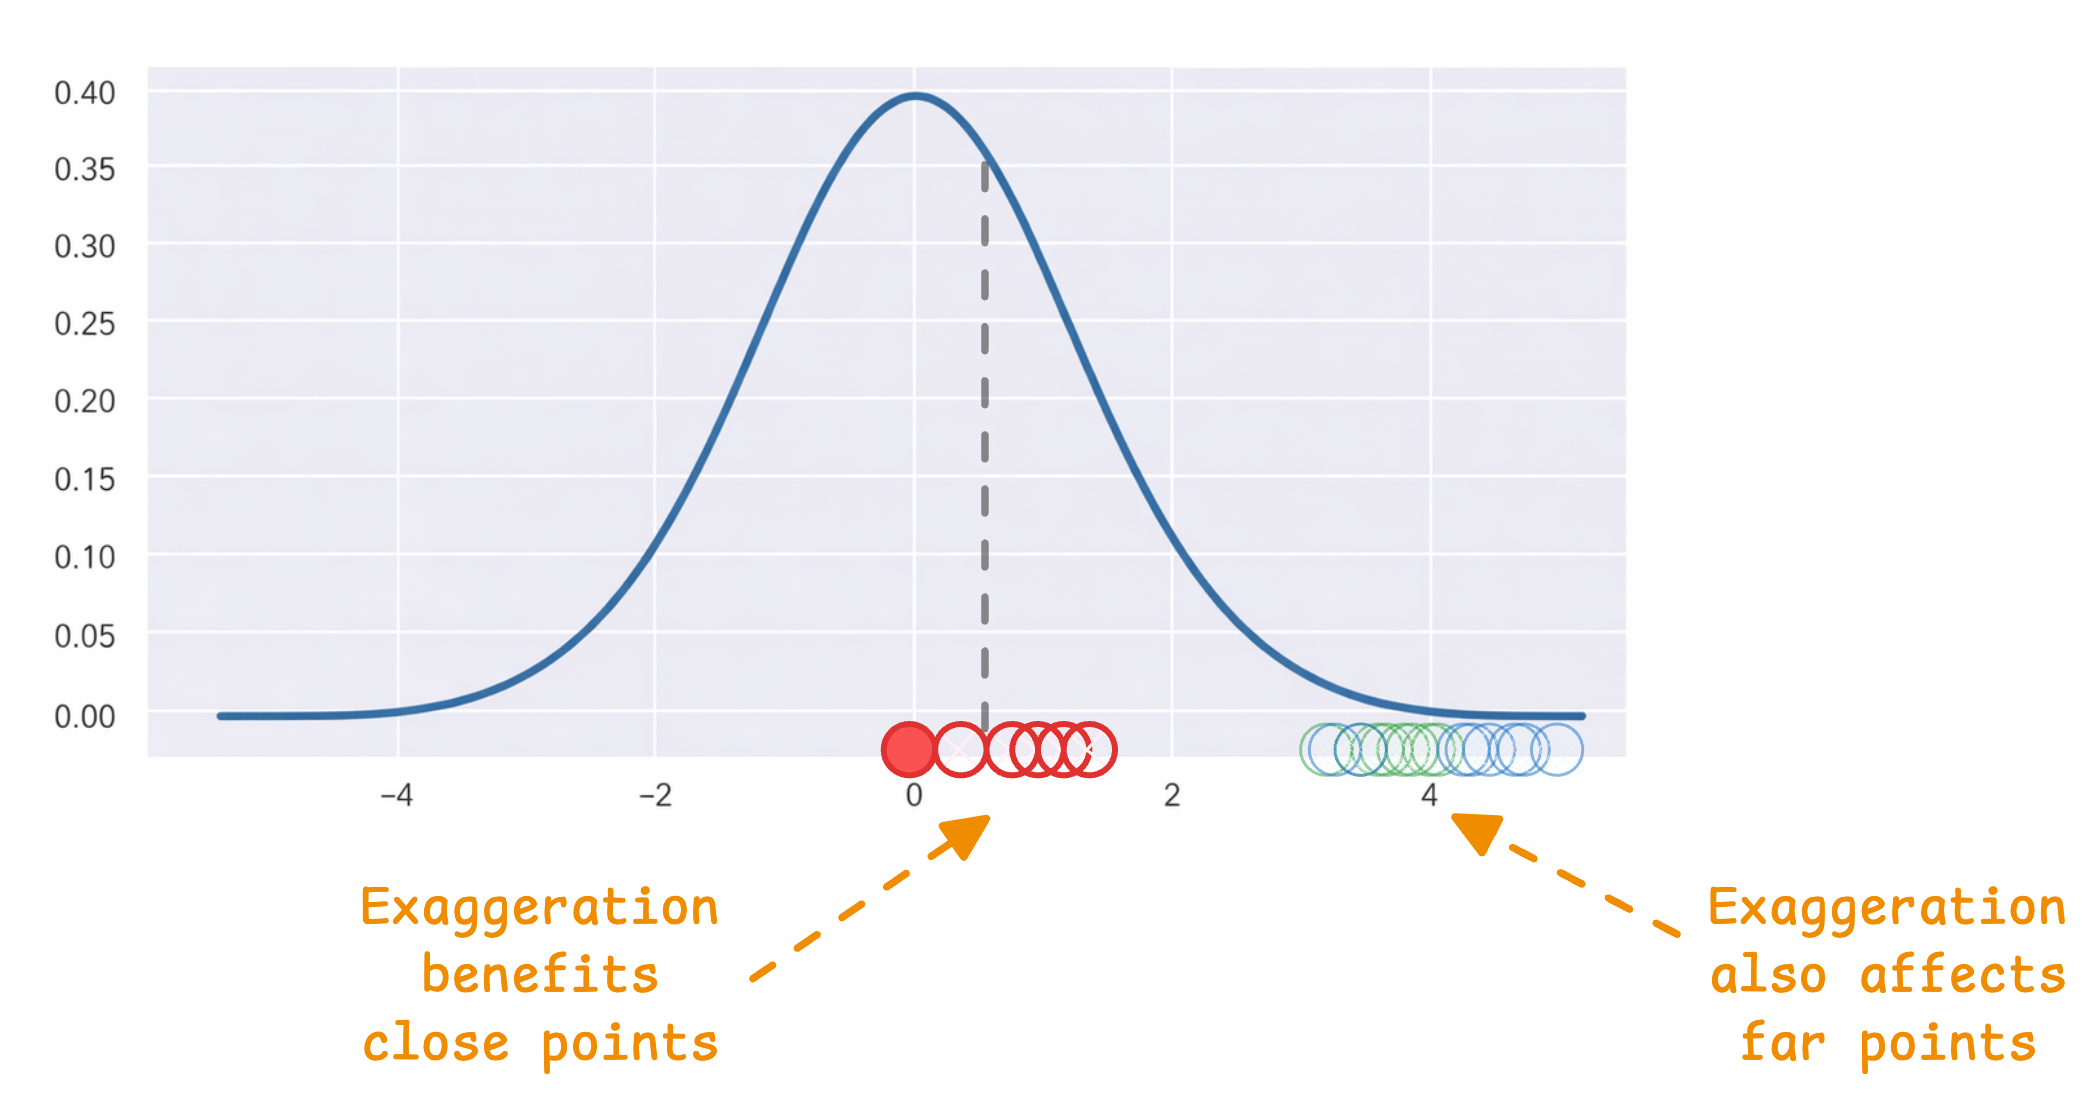
Step 1) For every point (i) in the given high-dimensional data, plot Euclidean distances to all other points (j), which gives you a Gaussian-like probability distribution. For instance, consider the dark red point marked on the left below. Other red points that are closer to it have a higher probability of being i‘s neighbor than those that are far:
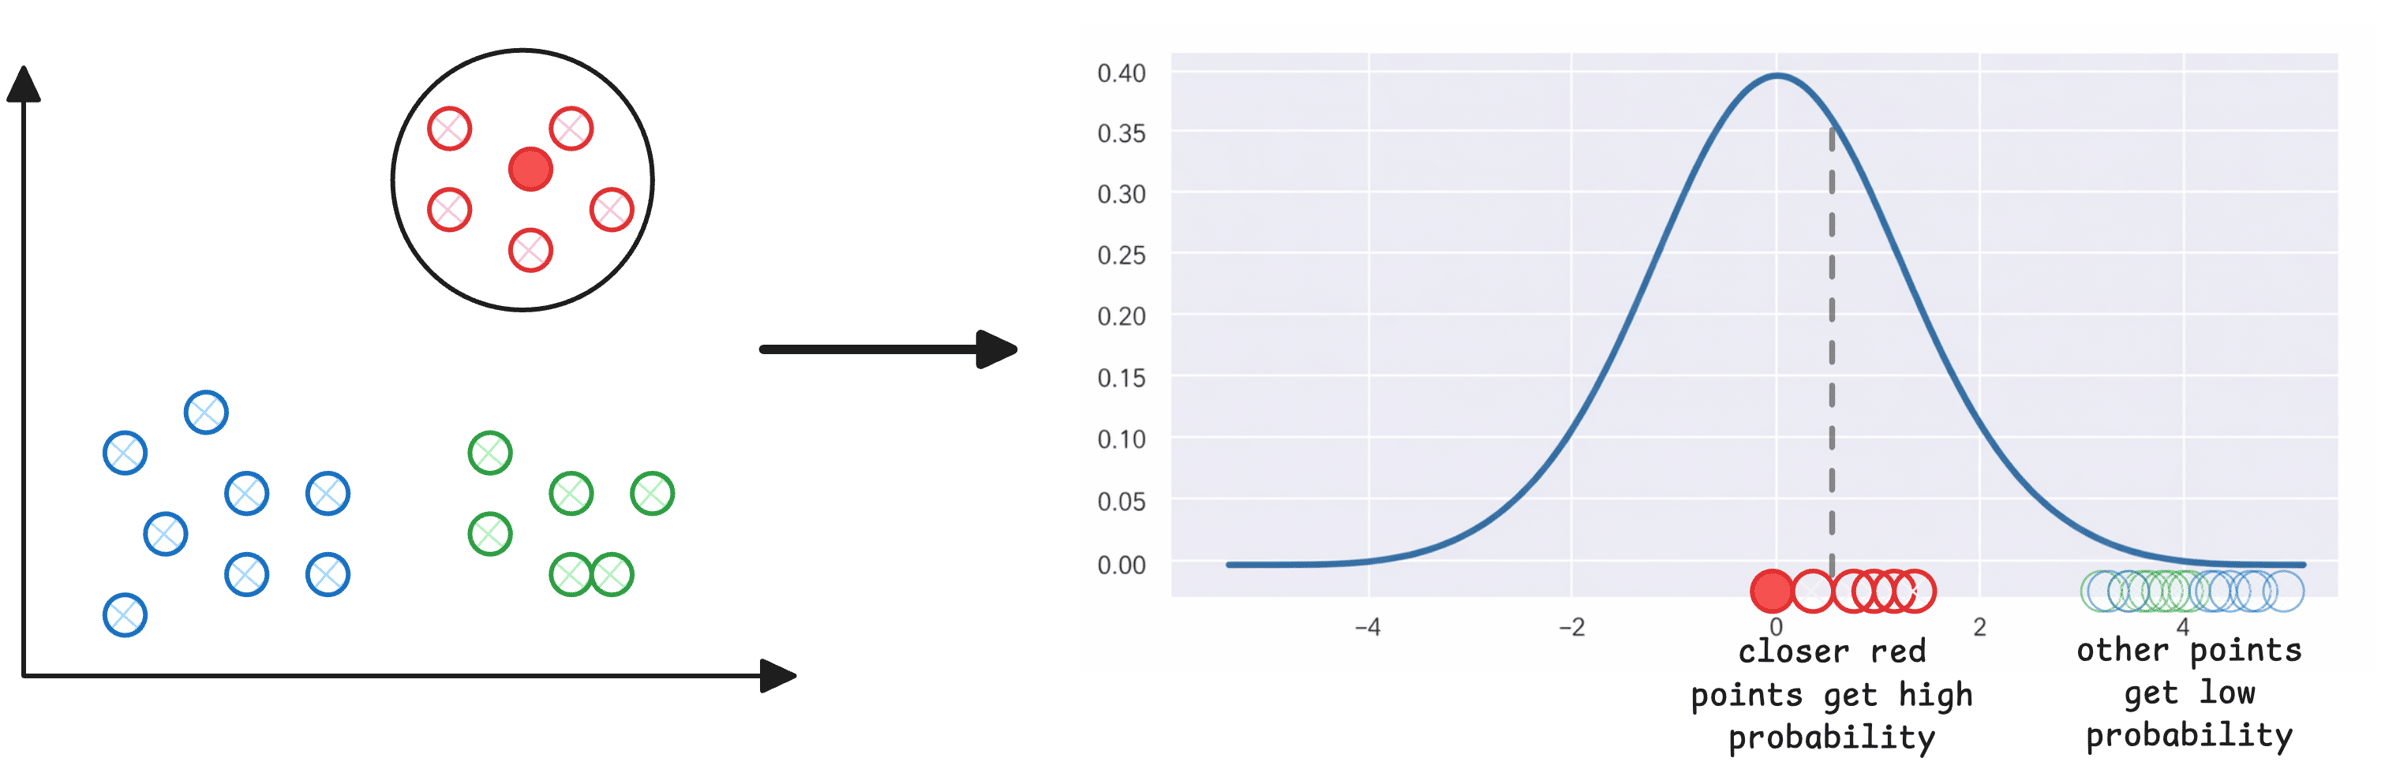
The above step assigns a neighbourhood distribution to every data point.
Step 2) Next, for every data point xᵢ in the given data (which is in high-dimensions), randomly initialize its counterpart yᵢ in 2D space. These will be our projections.
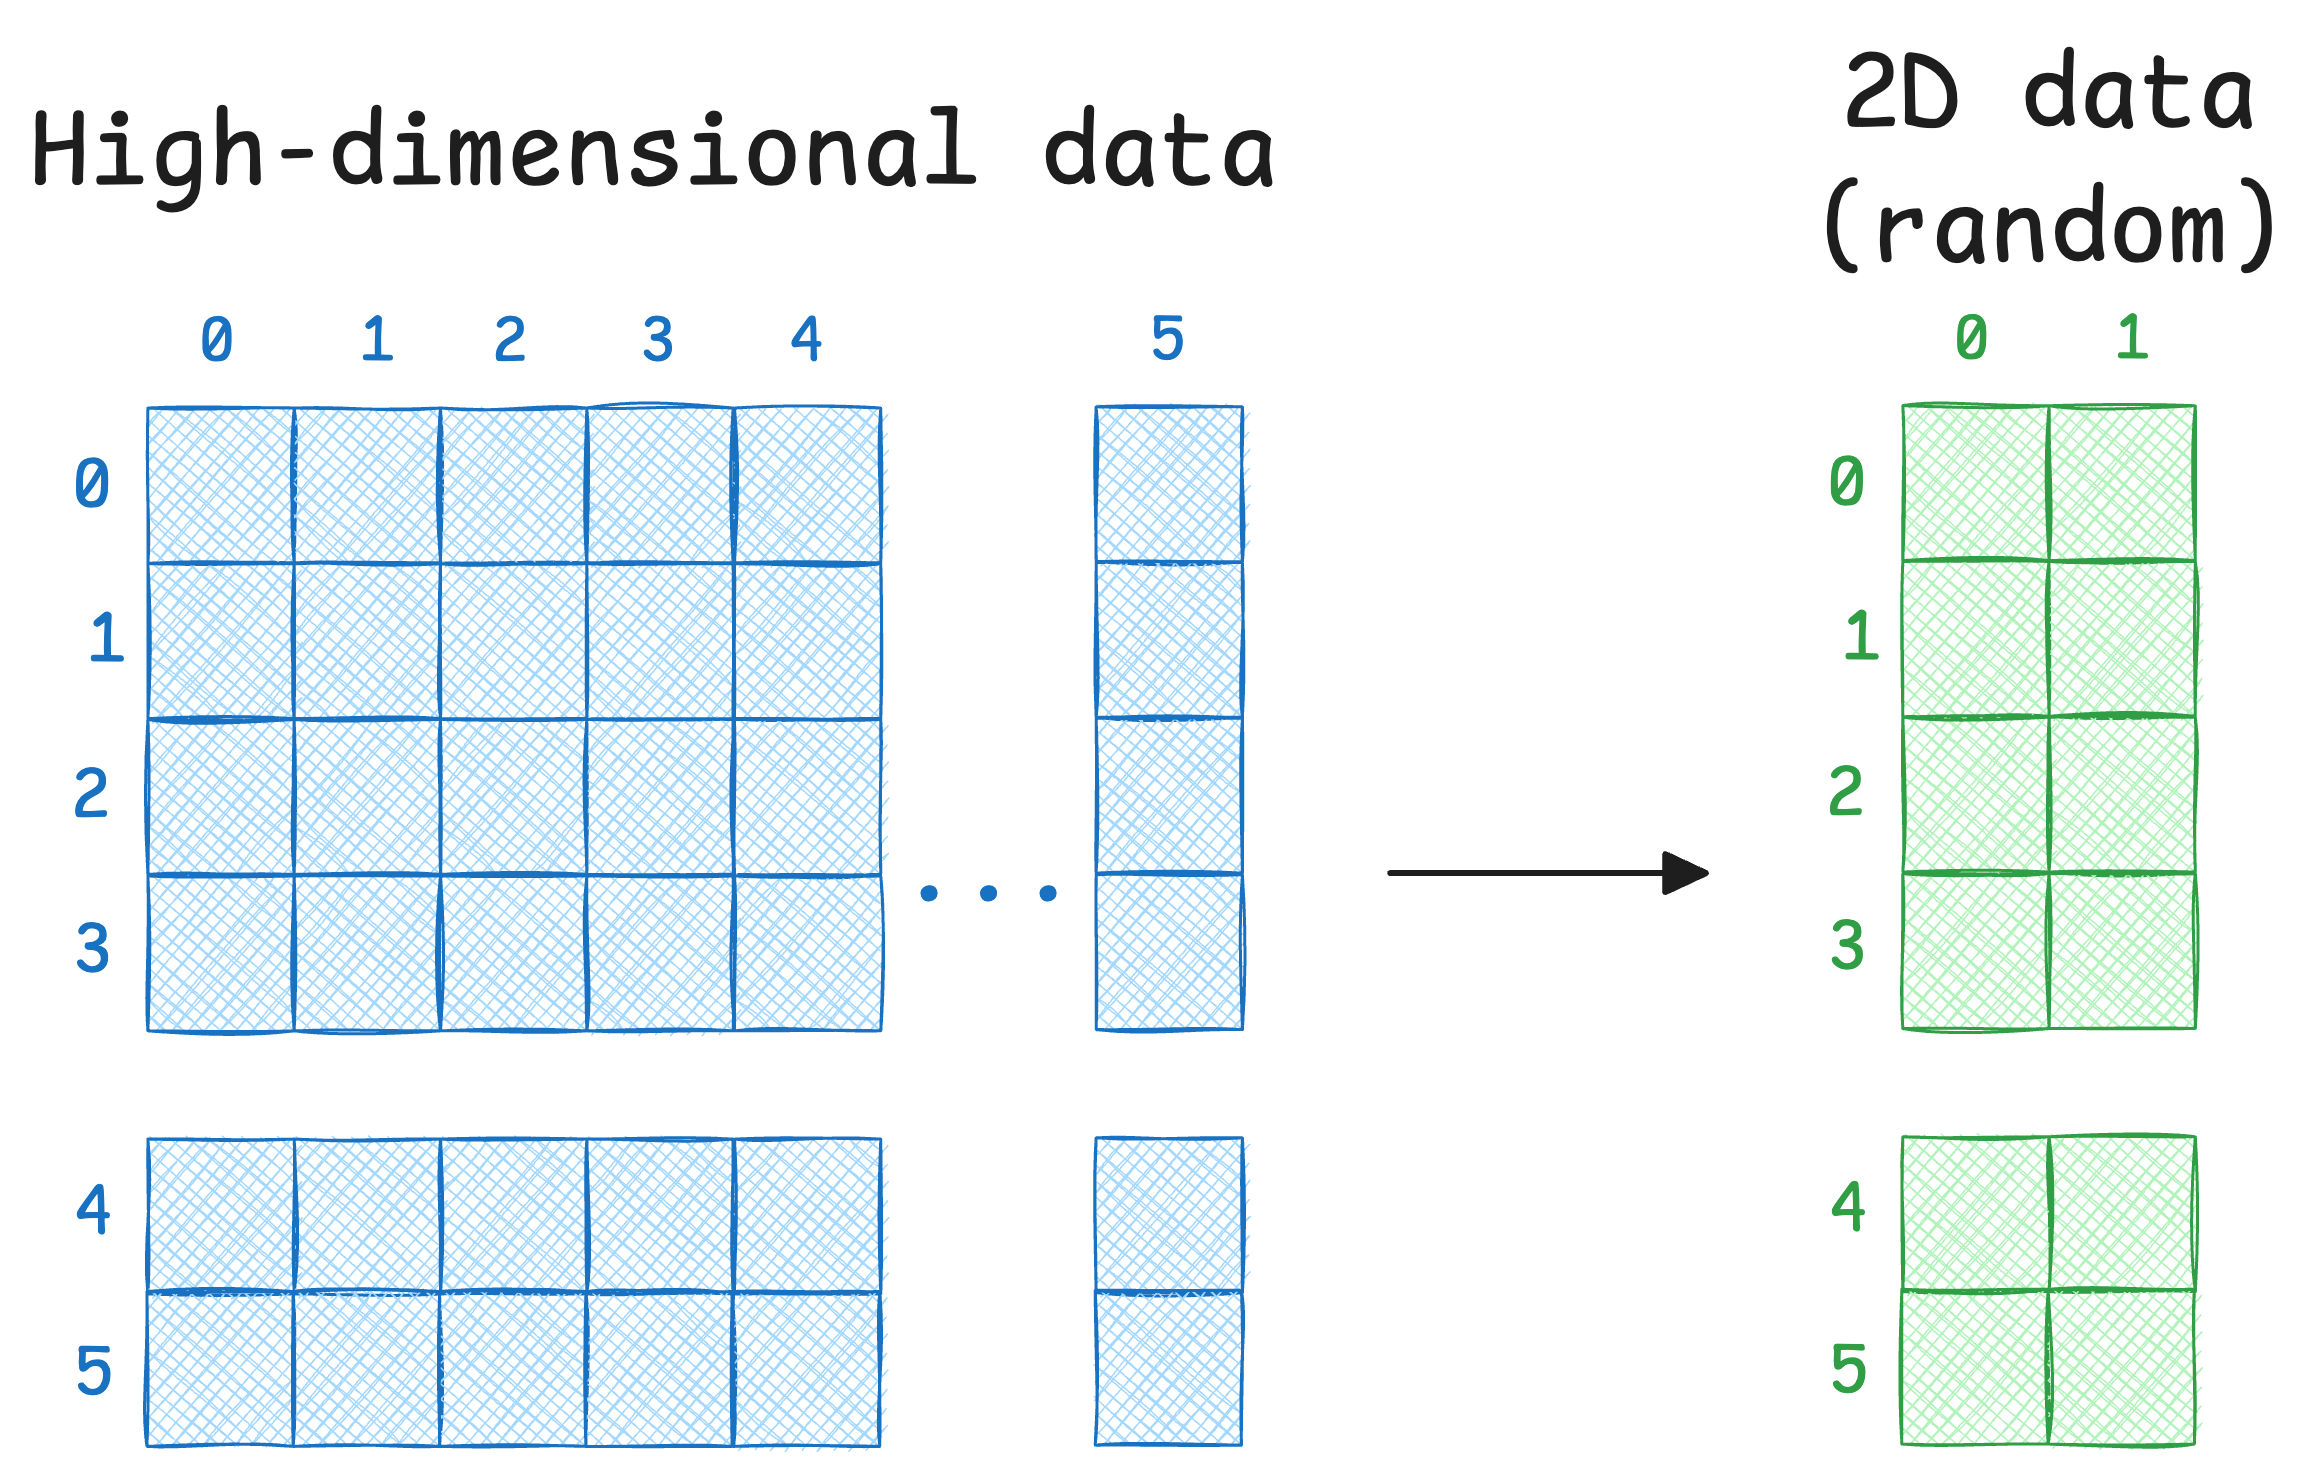
Step 3) Just like we created a distribution of Euclidean distances using high-dimensional data in Step 1, we create a distribution of the random data as well.
Step 4) At this point, every data point (i) has a high-dimensional distribution and a random low-dimensional distribution. The objective is to match these two distributions so that the low-dimensional representation preserves the neighborhood structure of the high-dimensional data.

Using KL divergence as a loss function helps us achieve this. It measures how much information is lost when we use a distribution
Qto approximate distributionP.

Ideally, we want to have the minimum loss value (which is zero), and this will be achieved when
P=Q.

The model can be trained using gradient descent, and eventually, it generates projections that preserve the local neighborhood structure of the original high-dimensional data.
But having early exaggeration makes it even better.
Early exaggeration
The step exaggerates (inflates) the values of all high-dimensional probabilities (P) during the initial stages of the optimization by multiplying a constant factor greater than 1:
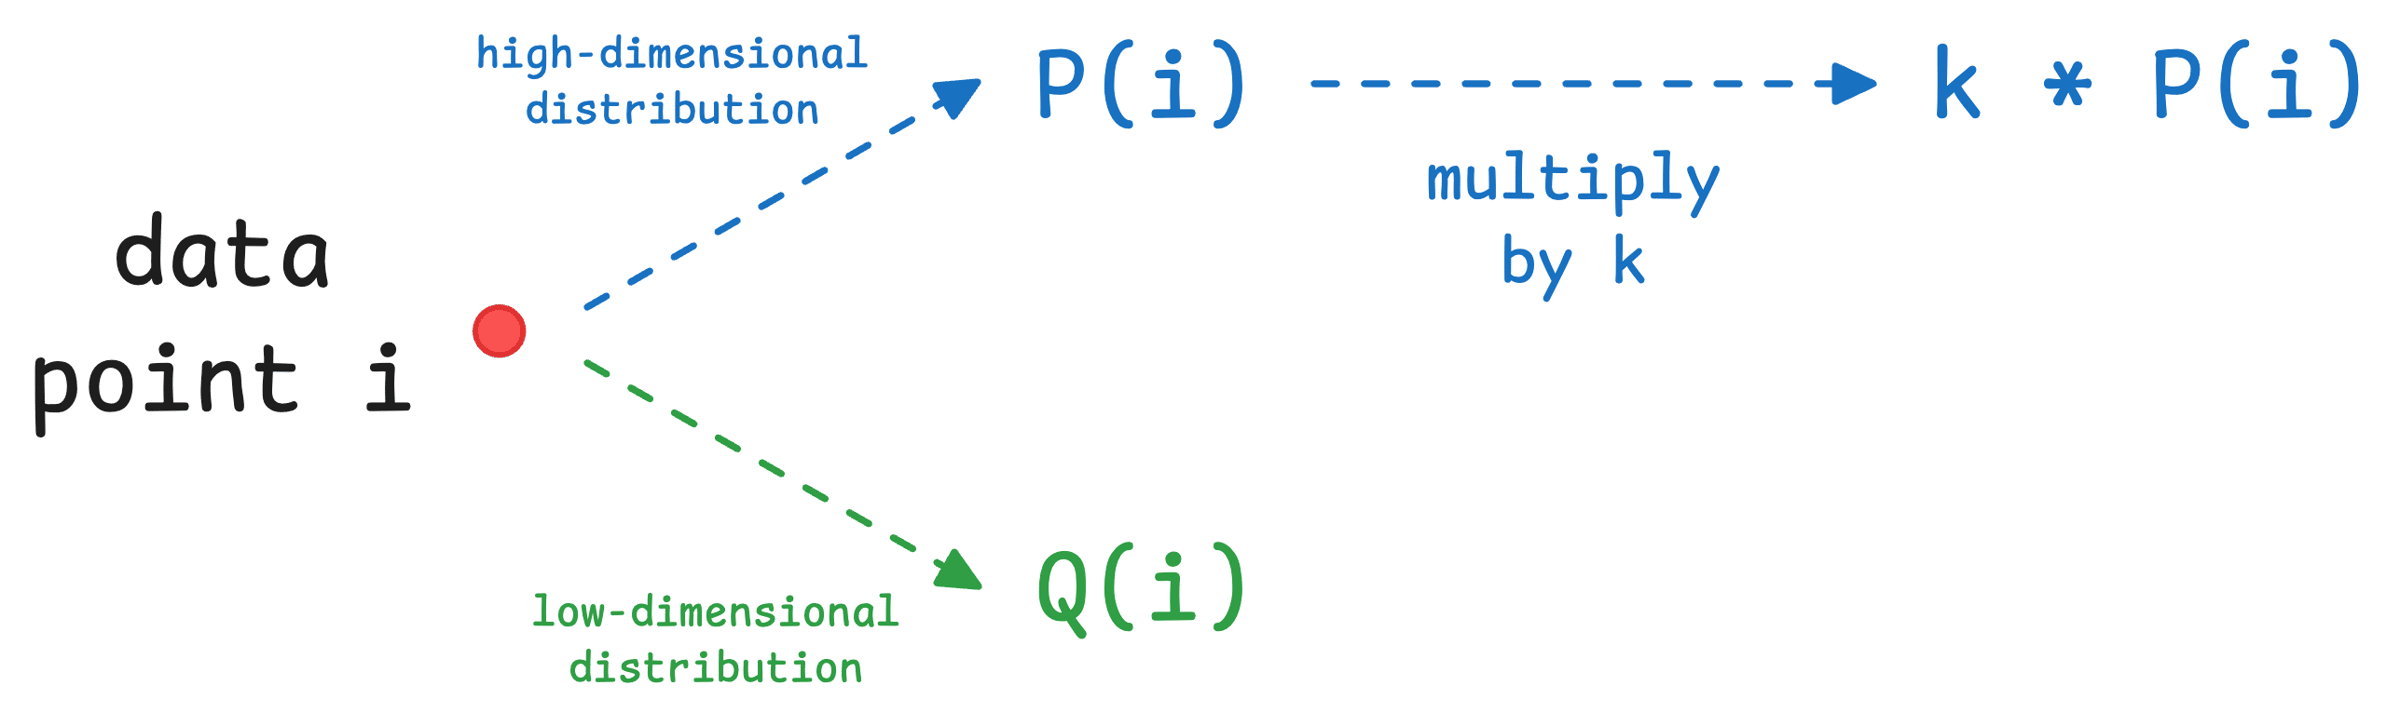
Here’s why this is useful:
Recall that the KL divergence is minimized when the distributions P and Q are identical.
By increasing P, the optimization process learns larger values of Q since it must match them to get minimum loss.
As a result, the low-dimensional clusters created will be very tight, and all individual clusters will be widely separated from each other.
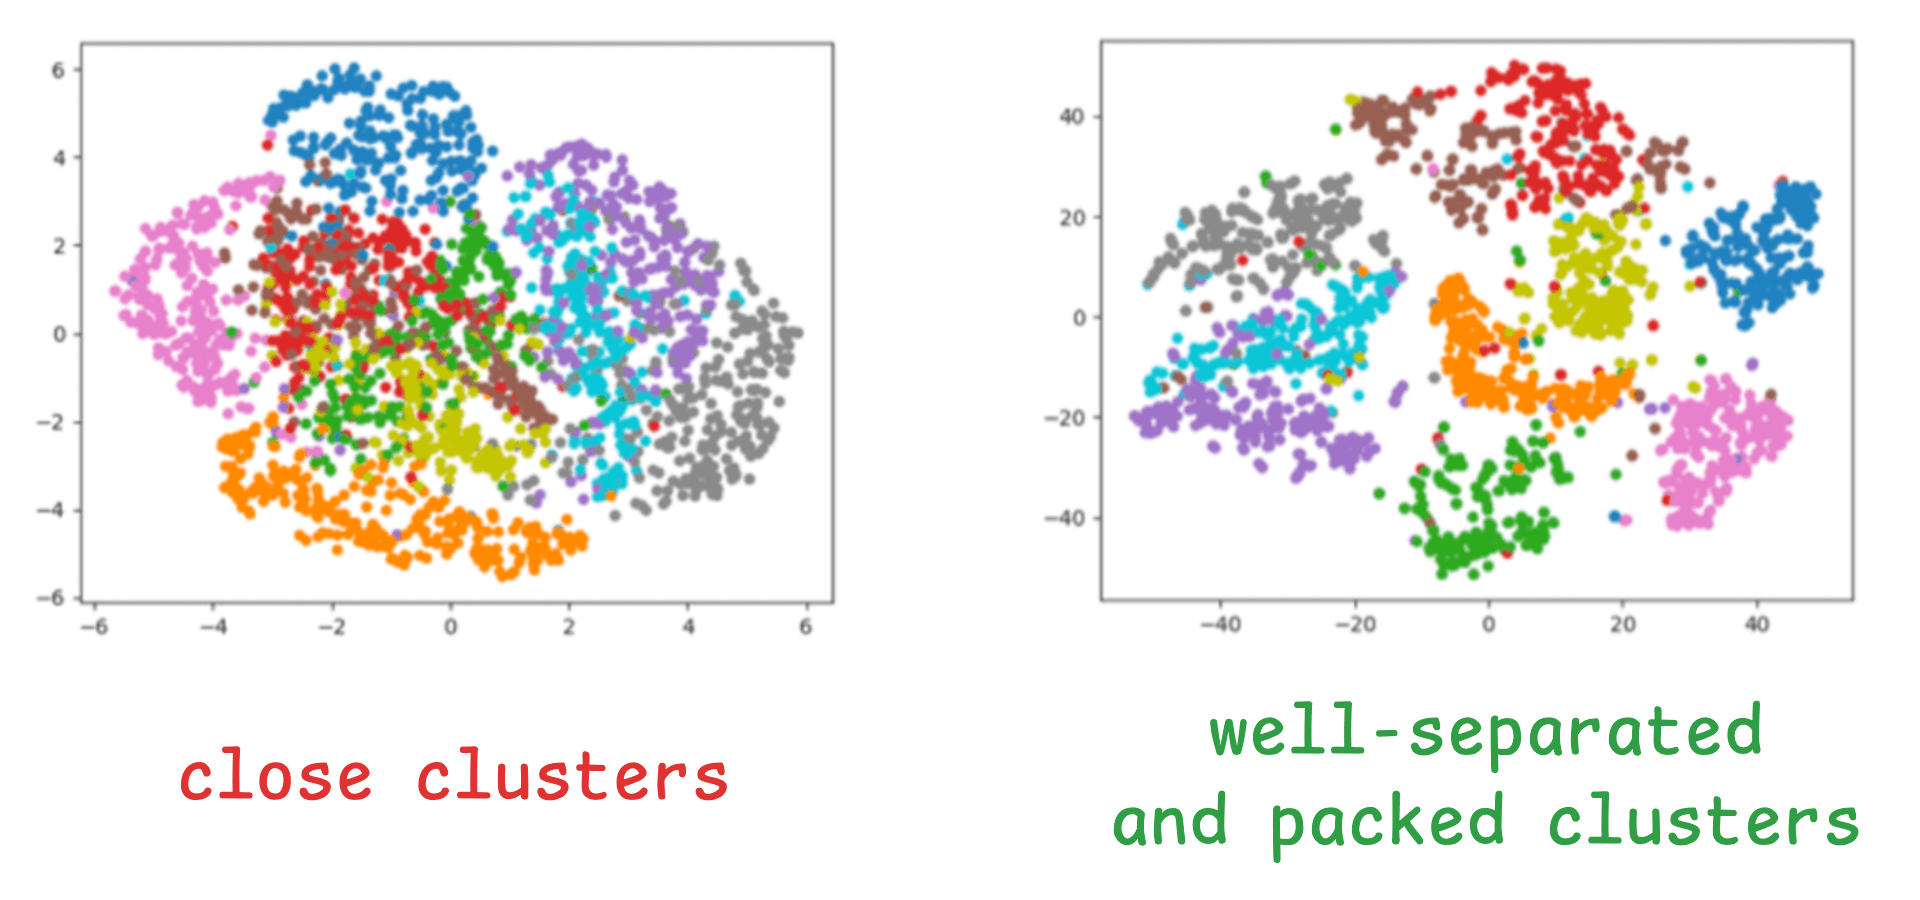
This is why we use early exaggeration.
Improving early exaggeration
Early exaggeration multiplies all high-dimensional probabilities (P) by a constant factor greater than 1.
While this inflates the probability of data points that are close, the downside is that it also inflates the probability of data points that are far (likely in different clusters).
A better strategy is to set a threshold (λ) for inflating values:
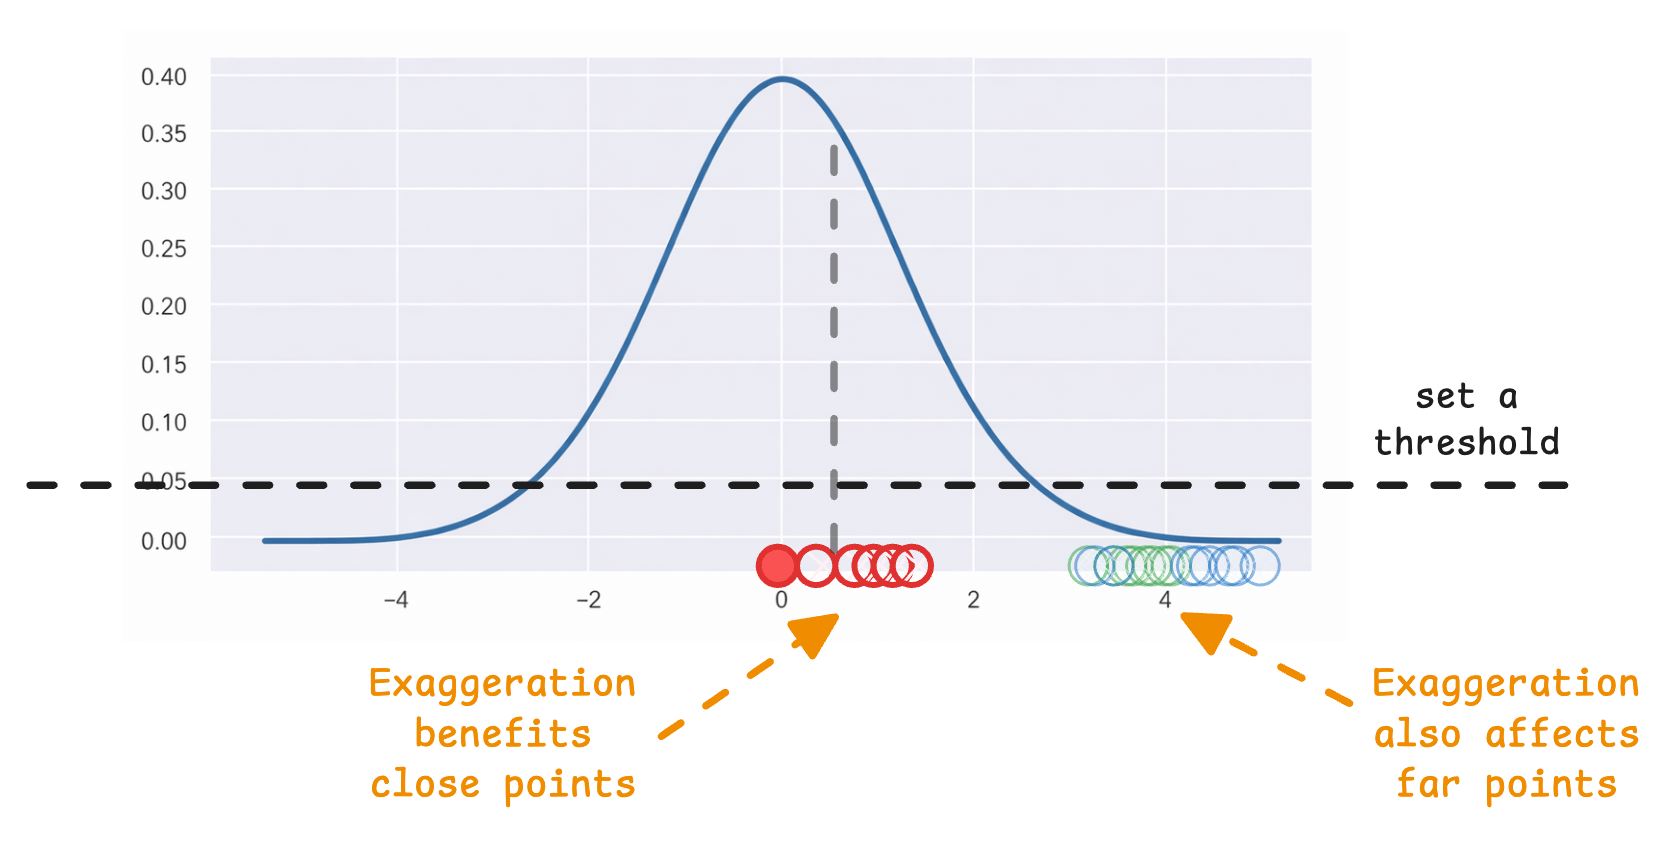
Only exaggerate the joint probabilities if they exceed a certain threshold.
Otherwise, understate (or reduce) them.
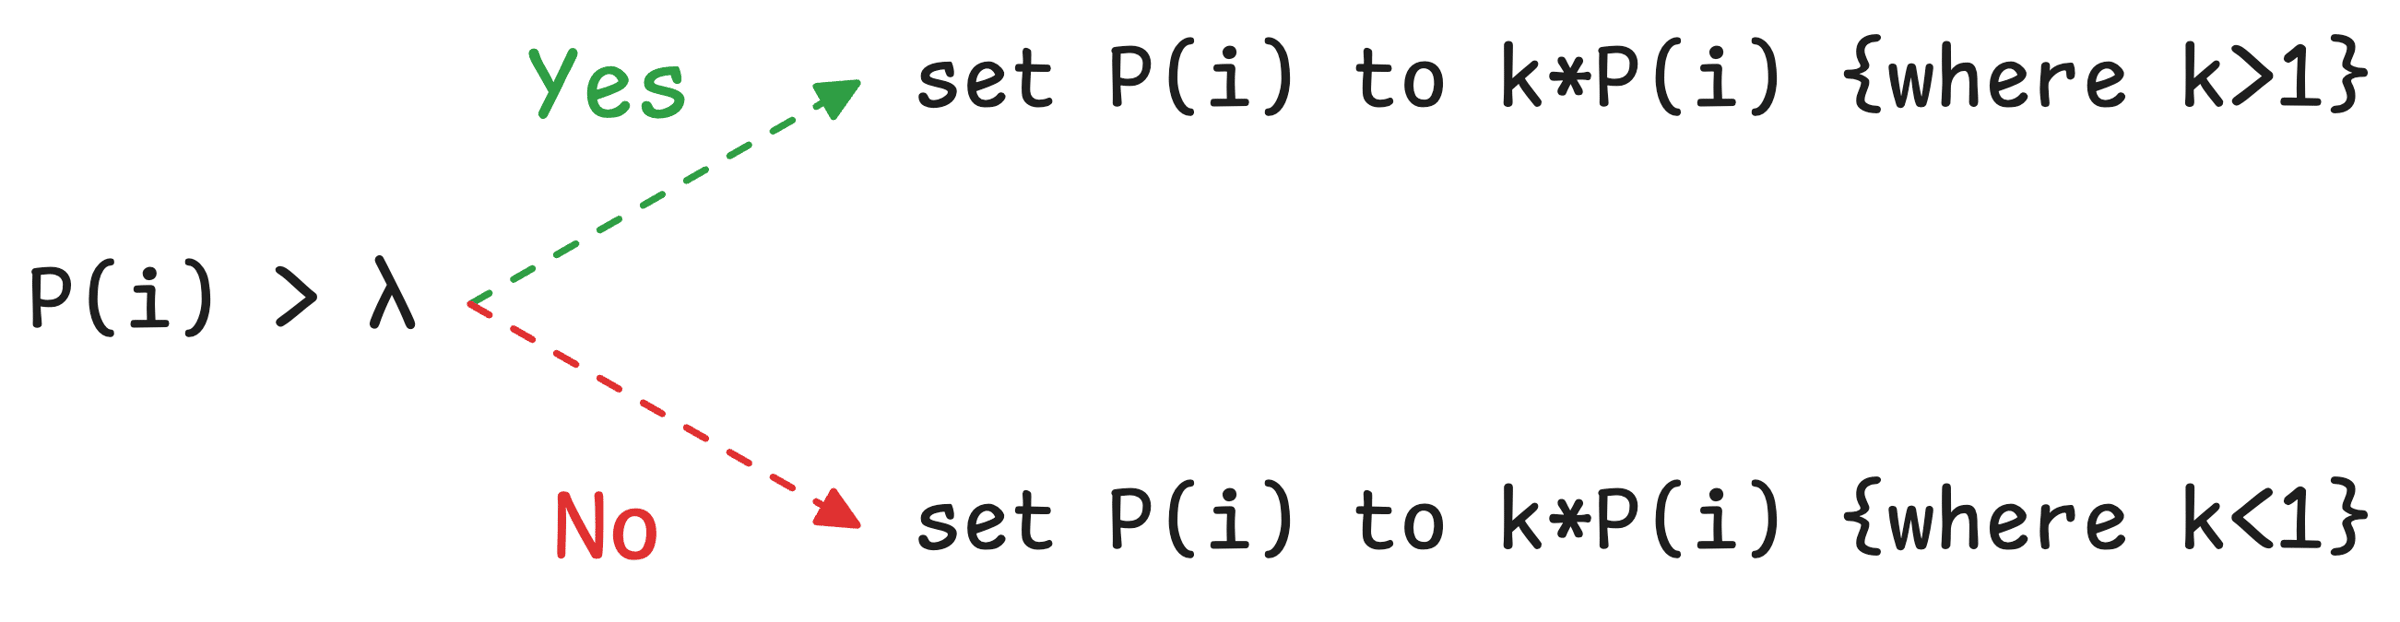
This makes intuitive sense as well.
This is how early exaggeration works and why it is so useful in tSNE.
We went into much more detail about tSNE in a beginner-friendly manner in the full article: Formulating and Implementing t-SNE From Scratch →
This article covers:
The limitations of PCA.
The entire end-to-end working of the SNE algorithm (an earlier version of t-SNE).
What does SNE try to optimize?
What are local and global structures?
Understanding the idea of
perplexityvisually.The limitations of the SNE algorithm.
How is t-SNE different from SNE?
Advanced optimization methods used in t-SNE.
Implementing the entire t-SNE algorithm by only using NumPy.
A practice Jupyter notebook for you to implement t-SNE yourself.
Understanding some potential gaps in t-SNE and how to possibly improve it.
PCA vs. t-SNE comparison.
Limitations of t-SNE.
Why is
perplexitythe most important hyperparameter of t-SNE?Important takeaways for using t-SNE.
Similar to this, we also formulated the PCA algorithm from scratch here: Formulating the PCA Algorithm From Scratch →
👉 Over to you: Can you identify a bottleneck in the t-SNE algorithm?
Good day!
The part I keep coming back to is that disk only wins after MLA cuts the KV cache by 93.3%, and then 3FS has to stripe the prefix across many SSDs so the read can stream to the GPU layer by layer. I would still worry about the exact-prefix rule: one token inserted at the front of an agent system prompt turns a hit into a full prefill, and the 500ms versus 13s gap on a 128K prompt is exactly that miss. The 3-day retention for agent traffic versus 7 days for chat is the other choice I would want a number for, because tool traces churn faster than chat and a short TTL throws away the 56% of input tokens that were served from disk.