

In today’s newsletter:
Harness Engineering 2.0 is here!
Why other requests change your LLM’s output.
RAG vs. retriever-free RAG, clearly explained.
Harness Engineering 2.0 is here!
Tools got MCP, agent-to-agent communication got A2A, and agent interfaces got AG-UI. Now harnesses have a protocol too.
Developers just built UHP (Unified Harness Protocol), a standard interface for running agent tasks on any agent harness. HarnessRouter is its open-source server implementation.
Here’s how it works:
↳ Your backend sends a task with a harness_id.
↳ HarnessRouter starts the selected harness in its own session.
↳ The harness runs its native agent loop and streams back progress.
↳ Files, artifacts, failures, and the final output come back through the same interface.
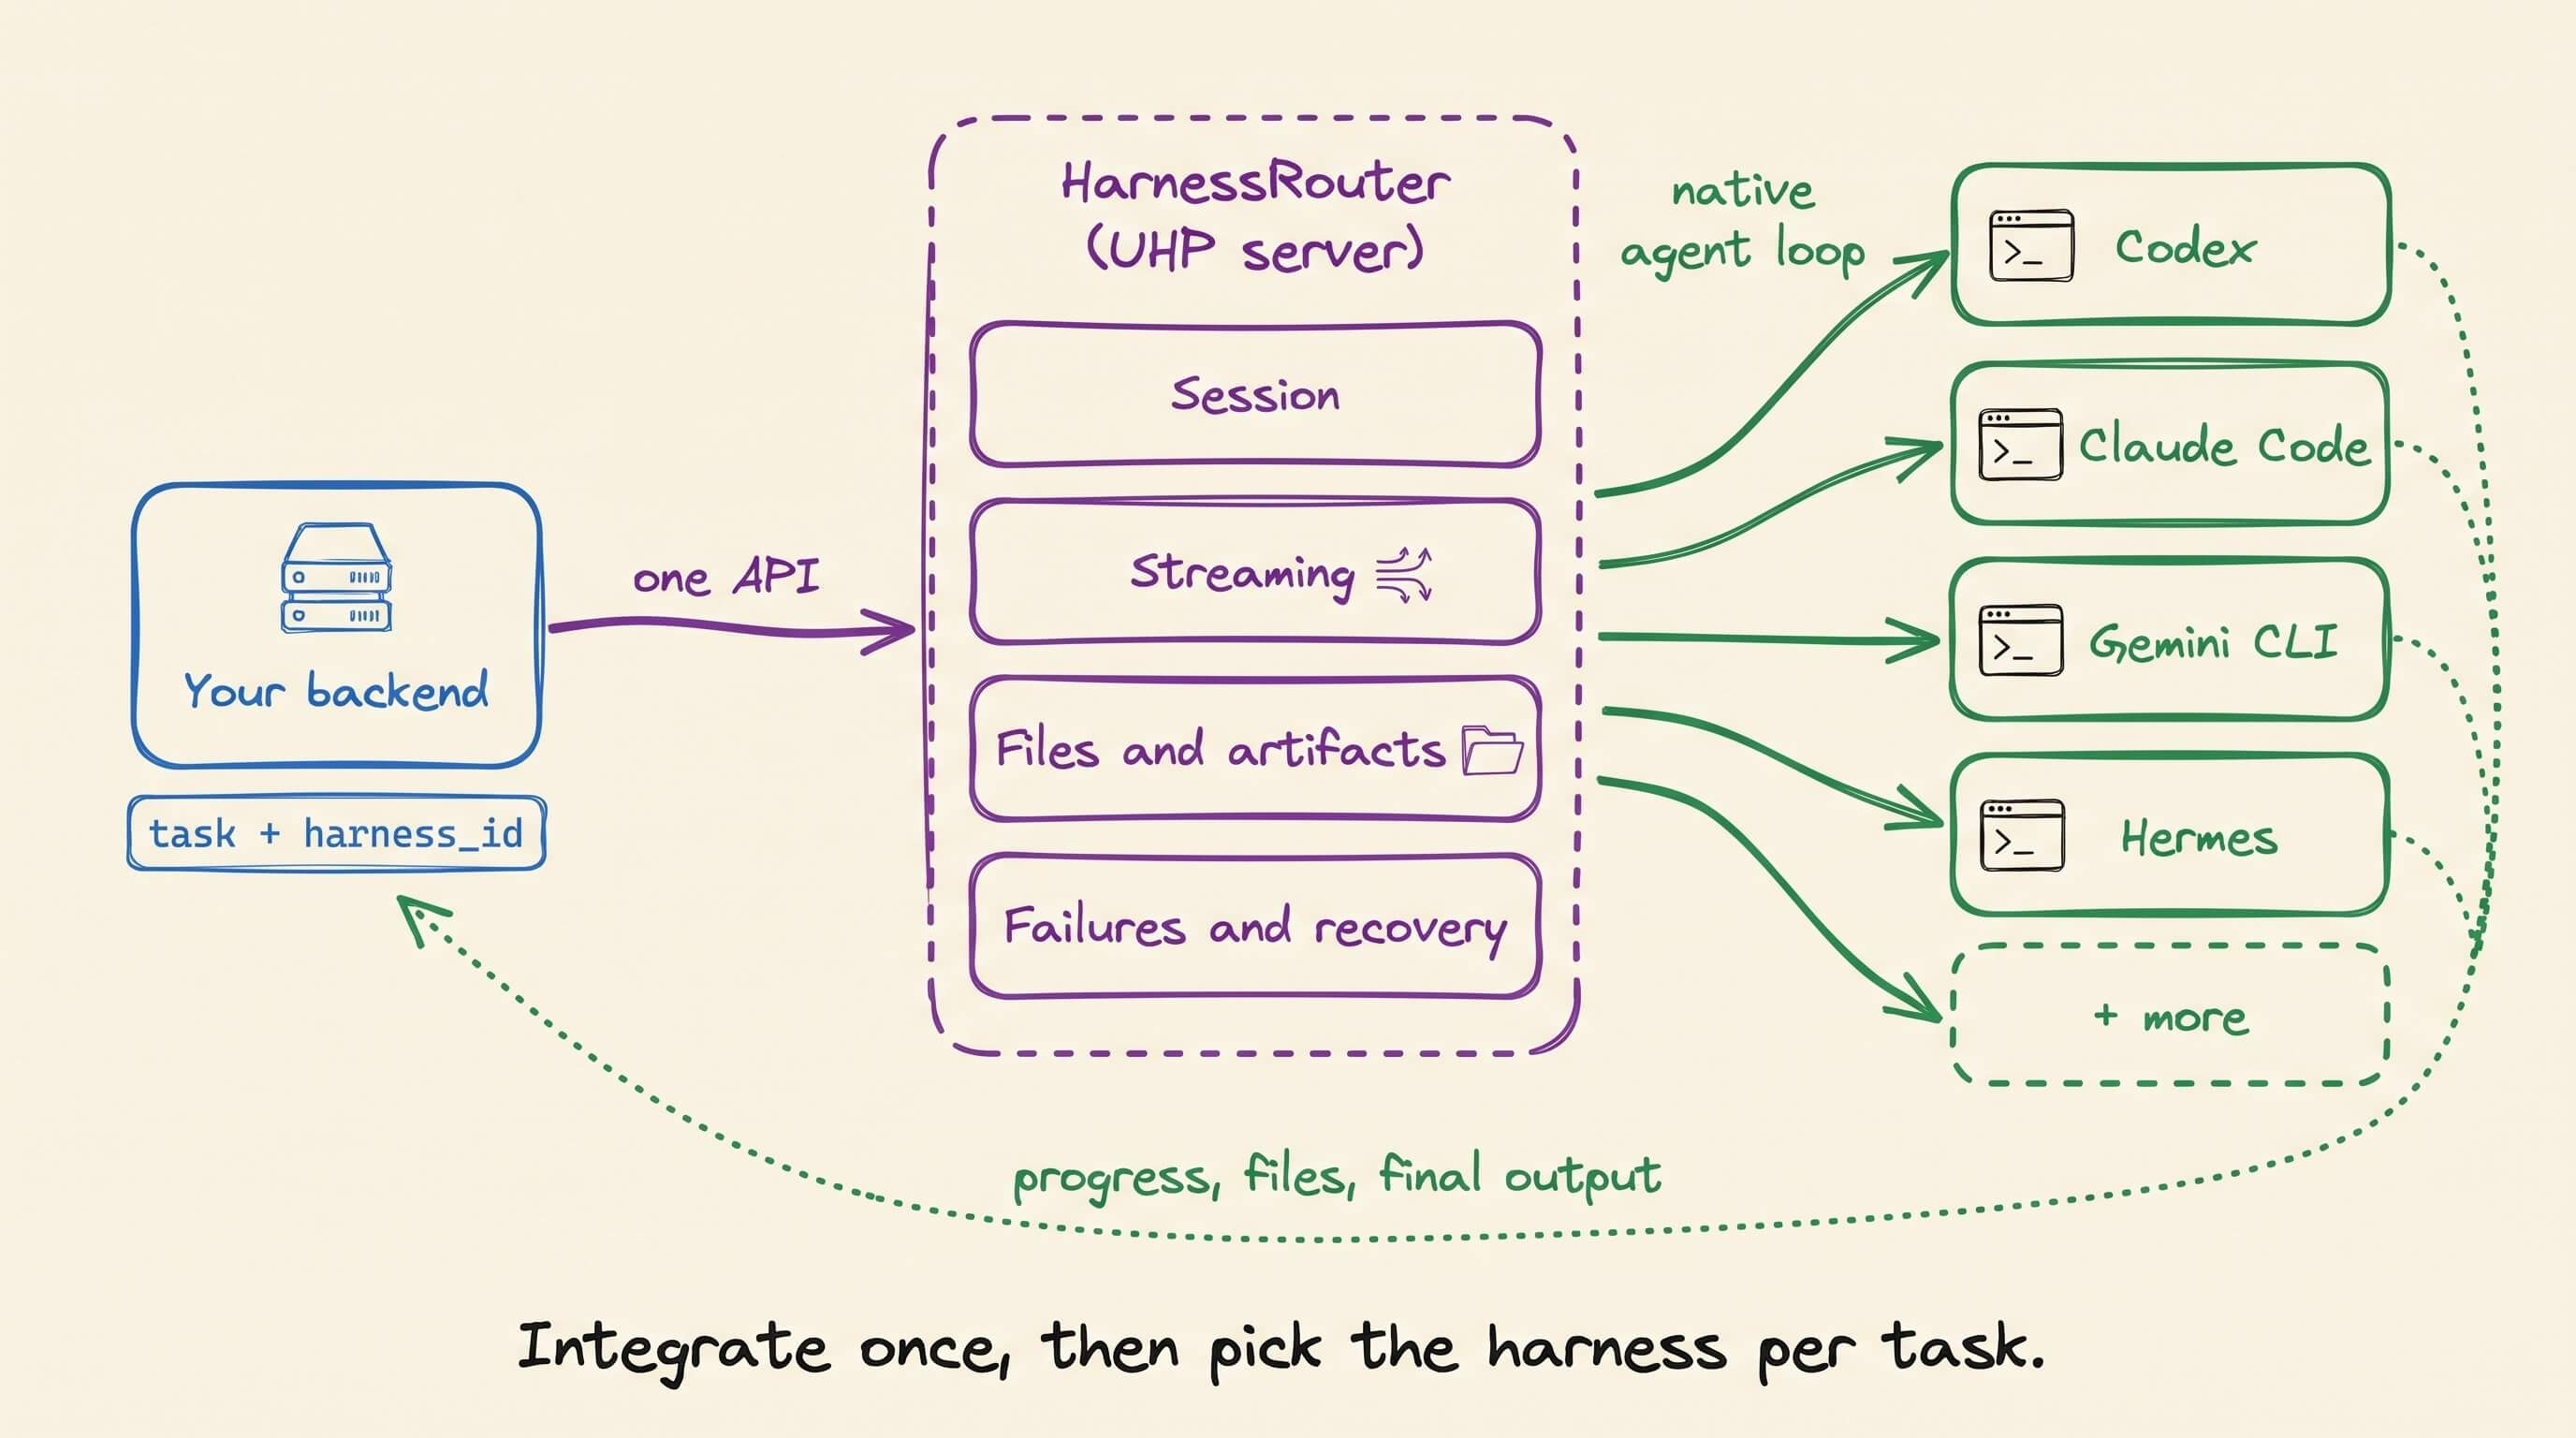
Without UHP, every harness needs its own handling for task execution, sessions, streaming, files, recovery, and output formats.
With UHP, Codex, Claude Code, Gemini CLI, Hermes, Pi, and other harnesses plug into the same product backend. Each one keeps its native tools, skills, models, and agent loop.
So developers can:
↳ Switch harnesses without rebuilding the product integration.
↳ Run the same task on different harnesses.
↳ Add new harnesses without maintaining another execution stack.
HarnessRouter supports 30 harness bases today.
The harness also changes what a task costs. In HarnessRouter’s published benchmark, keeping the model fixed and switching only the harness cut credits by 32% to 53% on the same healthcare prep task. Across all eight harness and model setups, the cheapest used 99.8% fewer credits than the most expensive.
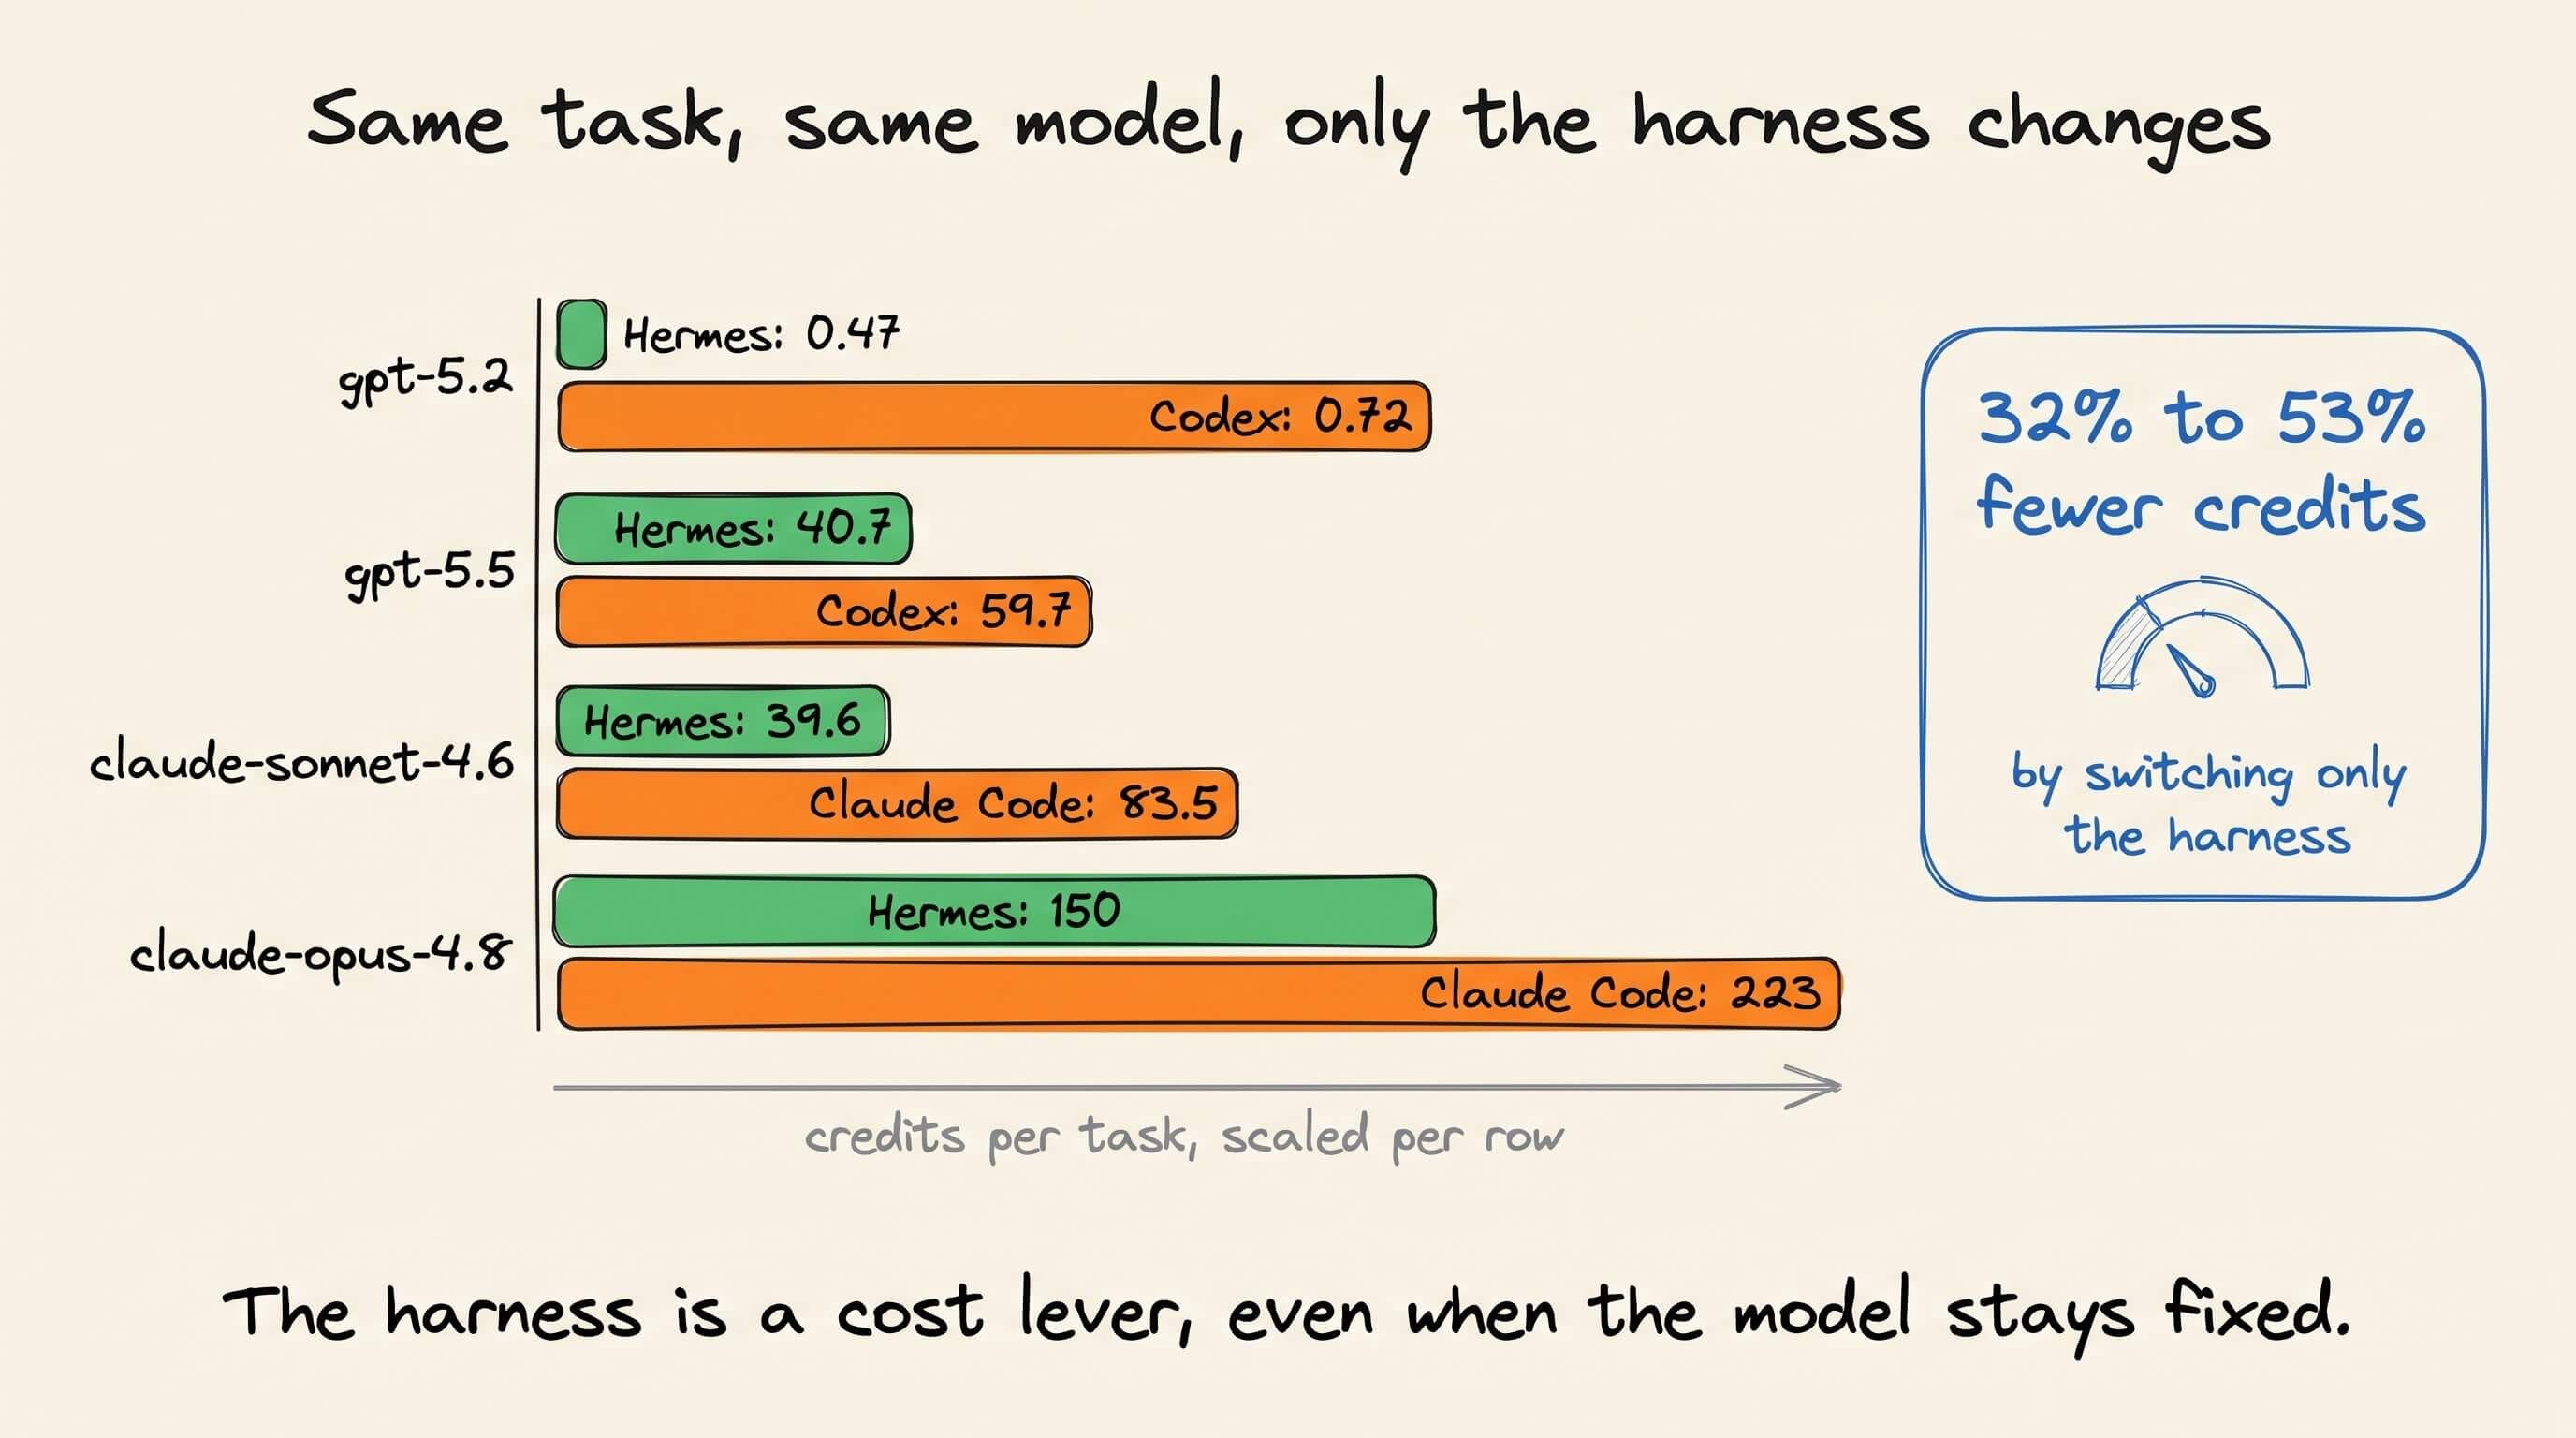
That’s one task, so your numbers will differ. Harness Arena lets you run your own workload across configurations and compare cost and latency. Alibaba’s Qoder has also adopted UHP and is available as an agent backend through the HarnessRouter API.
GitHub repo: https://github.com/HarnessRouter/harnessrouter
(don’t forget to star it ⭐)
Why other requests change your LLM’s output
Your LLM’s output depends on requests that aren’t yours.
The same prompt can produce different logits depending on how many other requests share its batch on the GPU.
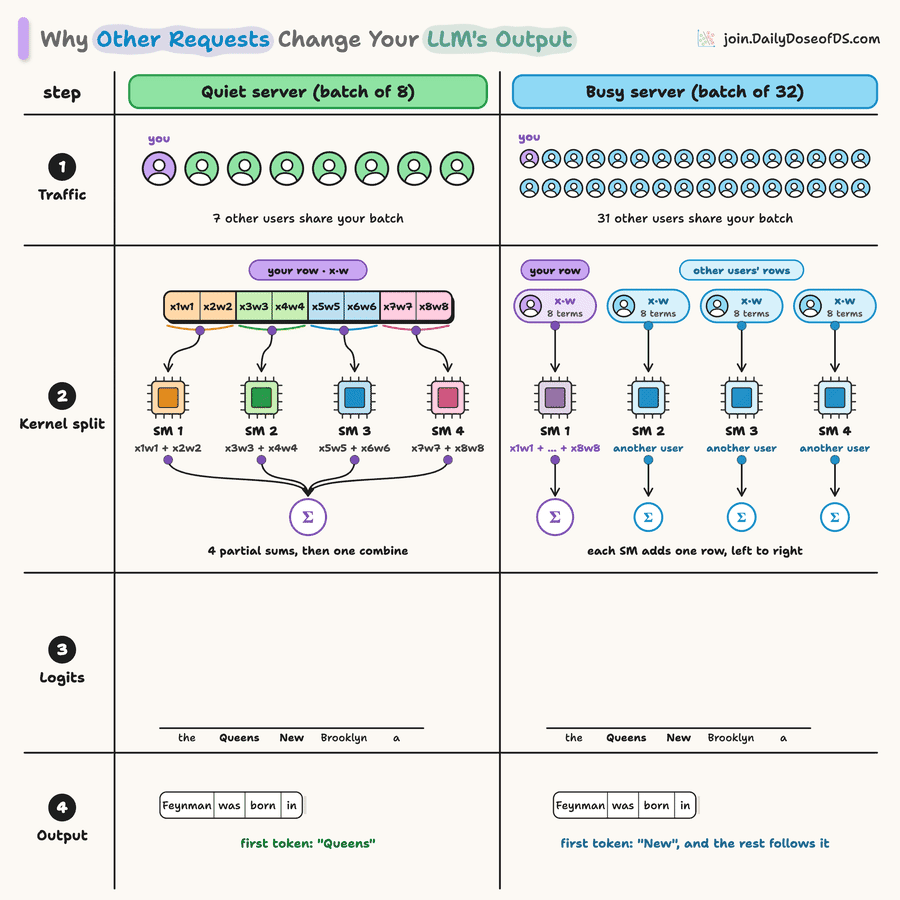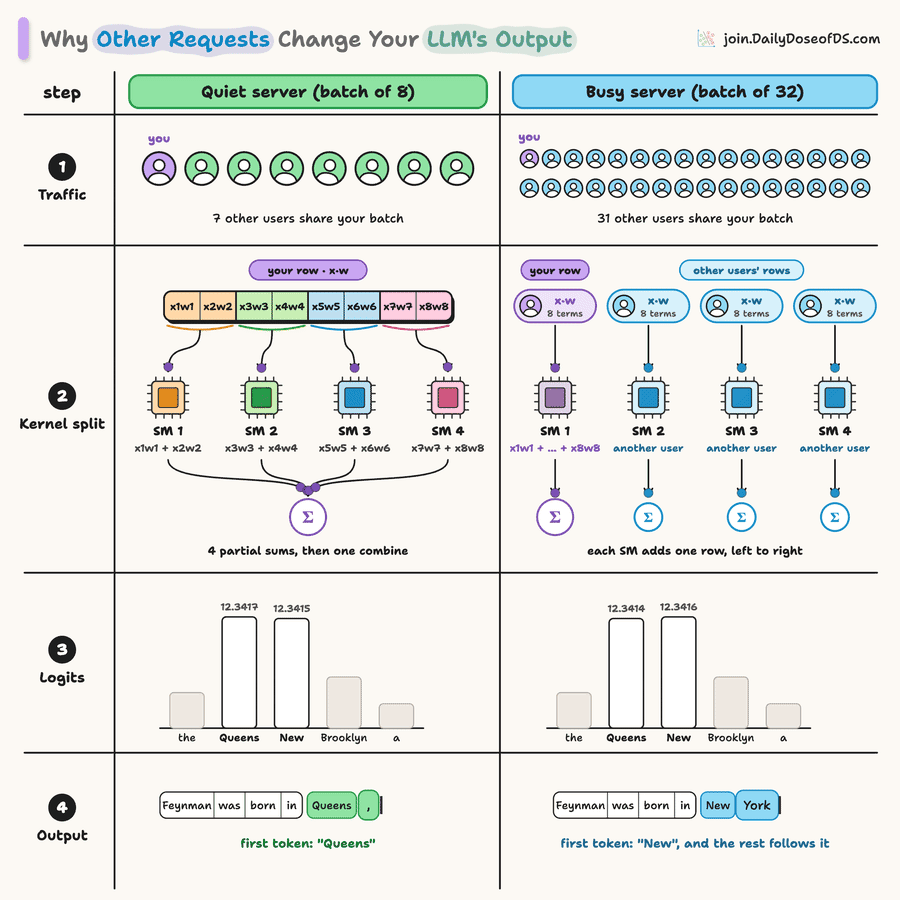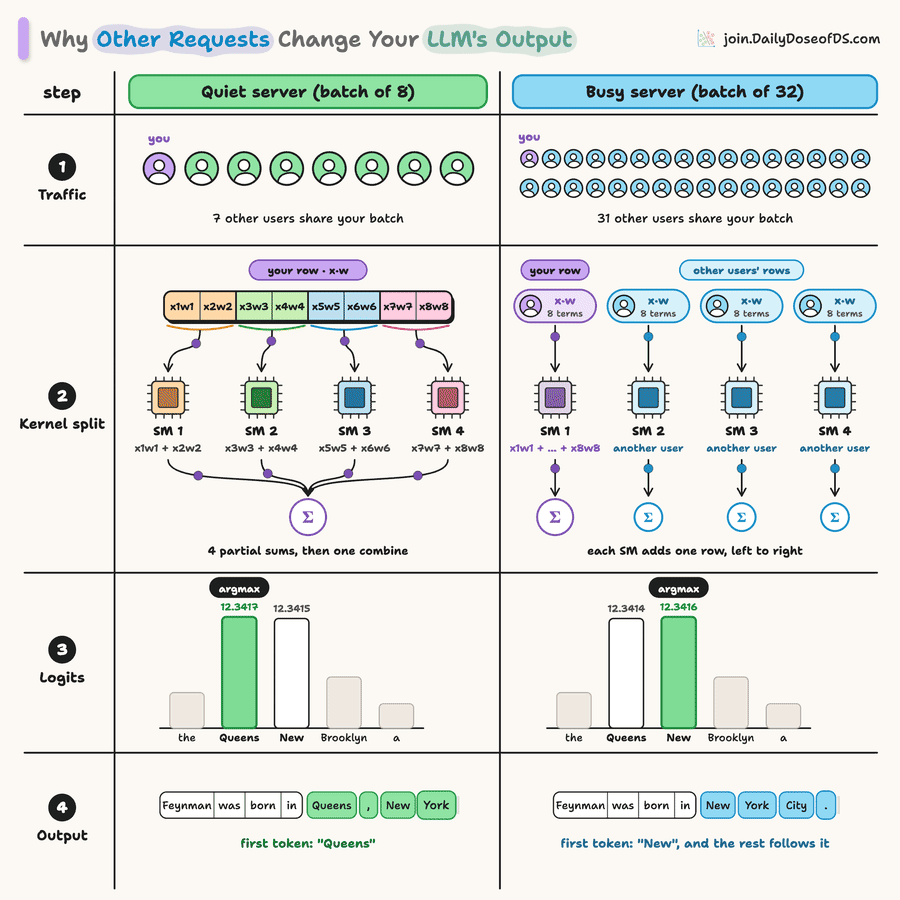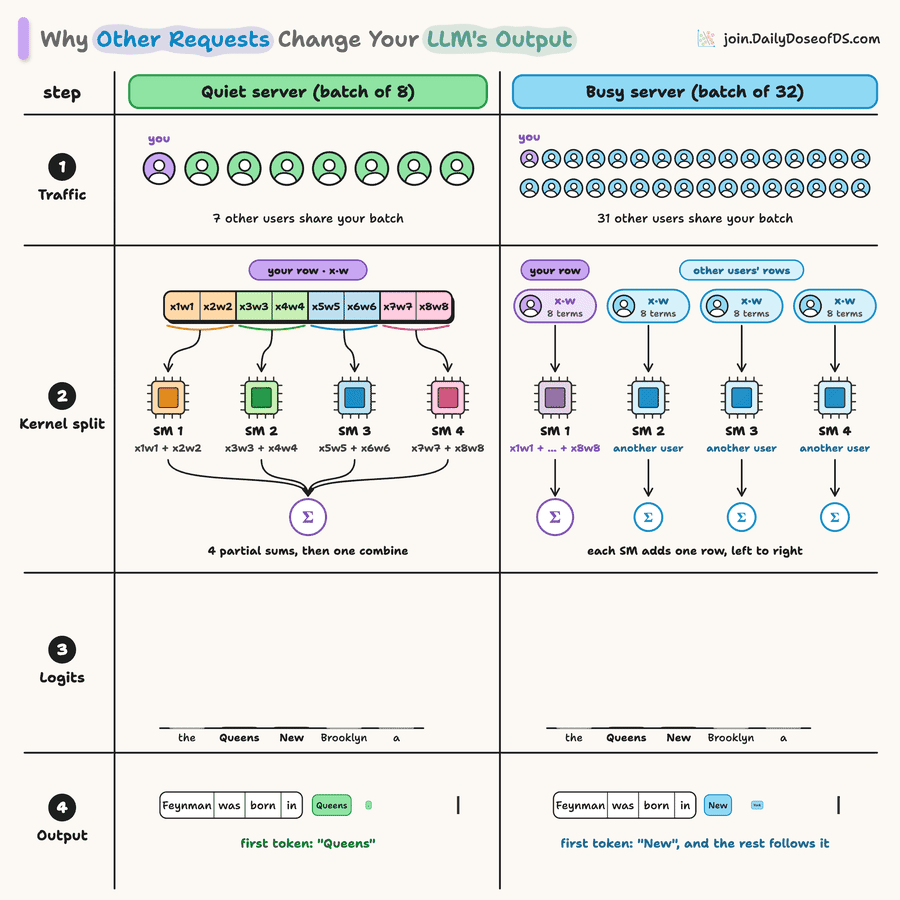
Thinking Machines Lab measured this. They sampled 1,000 completions of “Tell me about Richard Feynman” from Qwen3-235B at temperature 0 and got 80 unique completions.
All 1,000 matched for the first 102 tokens. At token 103, 992 continued with “Queens, New York” and 8 with “New York City”.
Here’s what happens inside the GPU.
Why the order of additions matters
Most of an LLM’s forward pass is spent accumulating sums. Every matmul, RMSNorm, and attention step reduces thousands of floating-point values into one output, so the order of those additions affects the result.
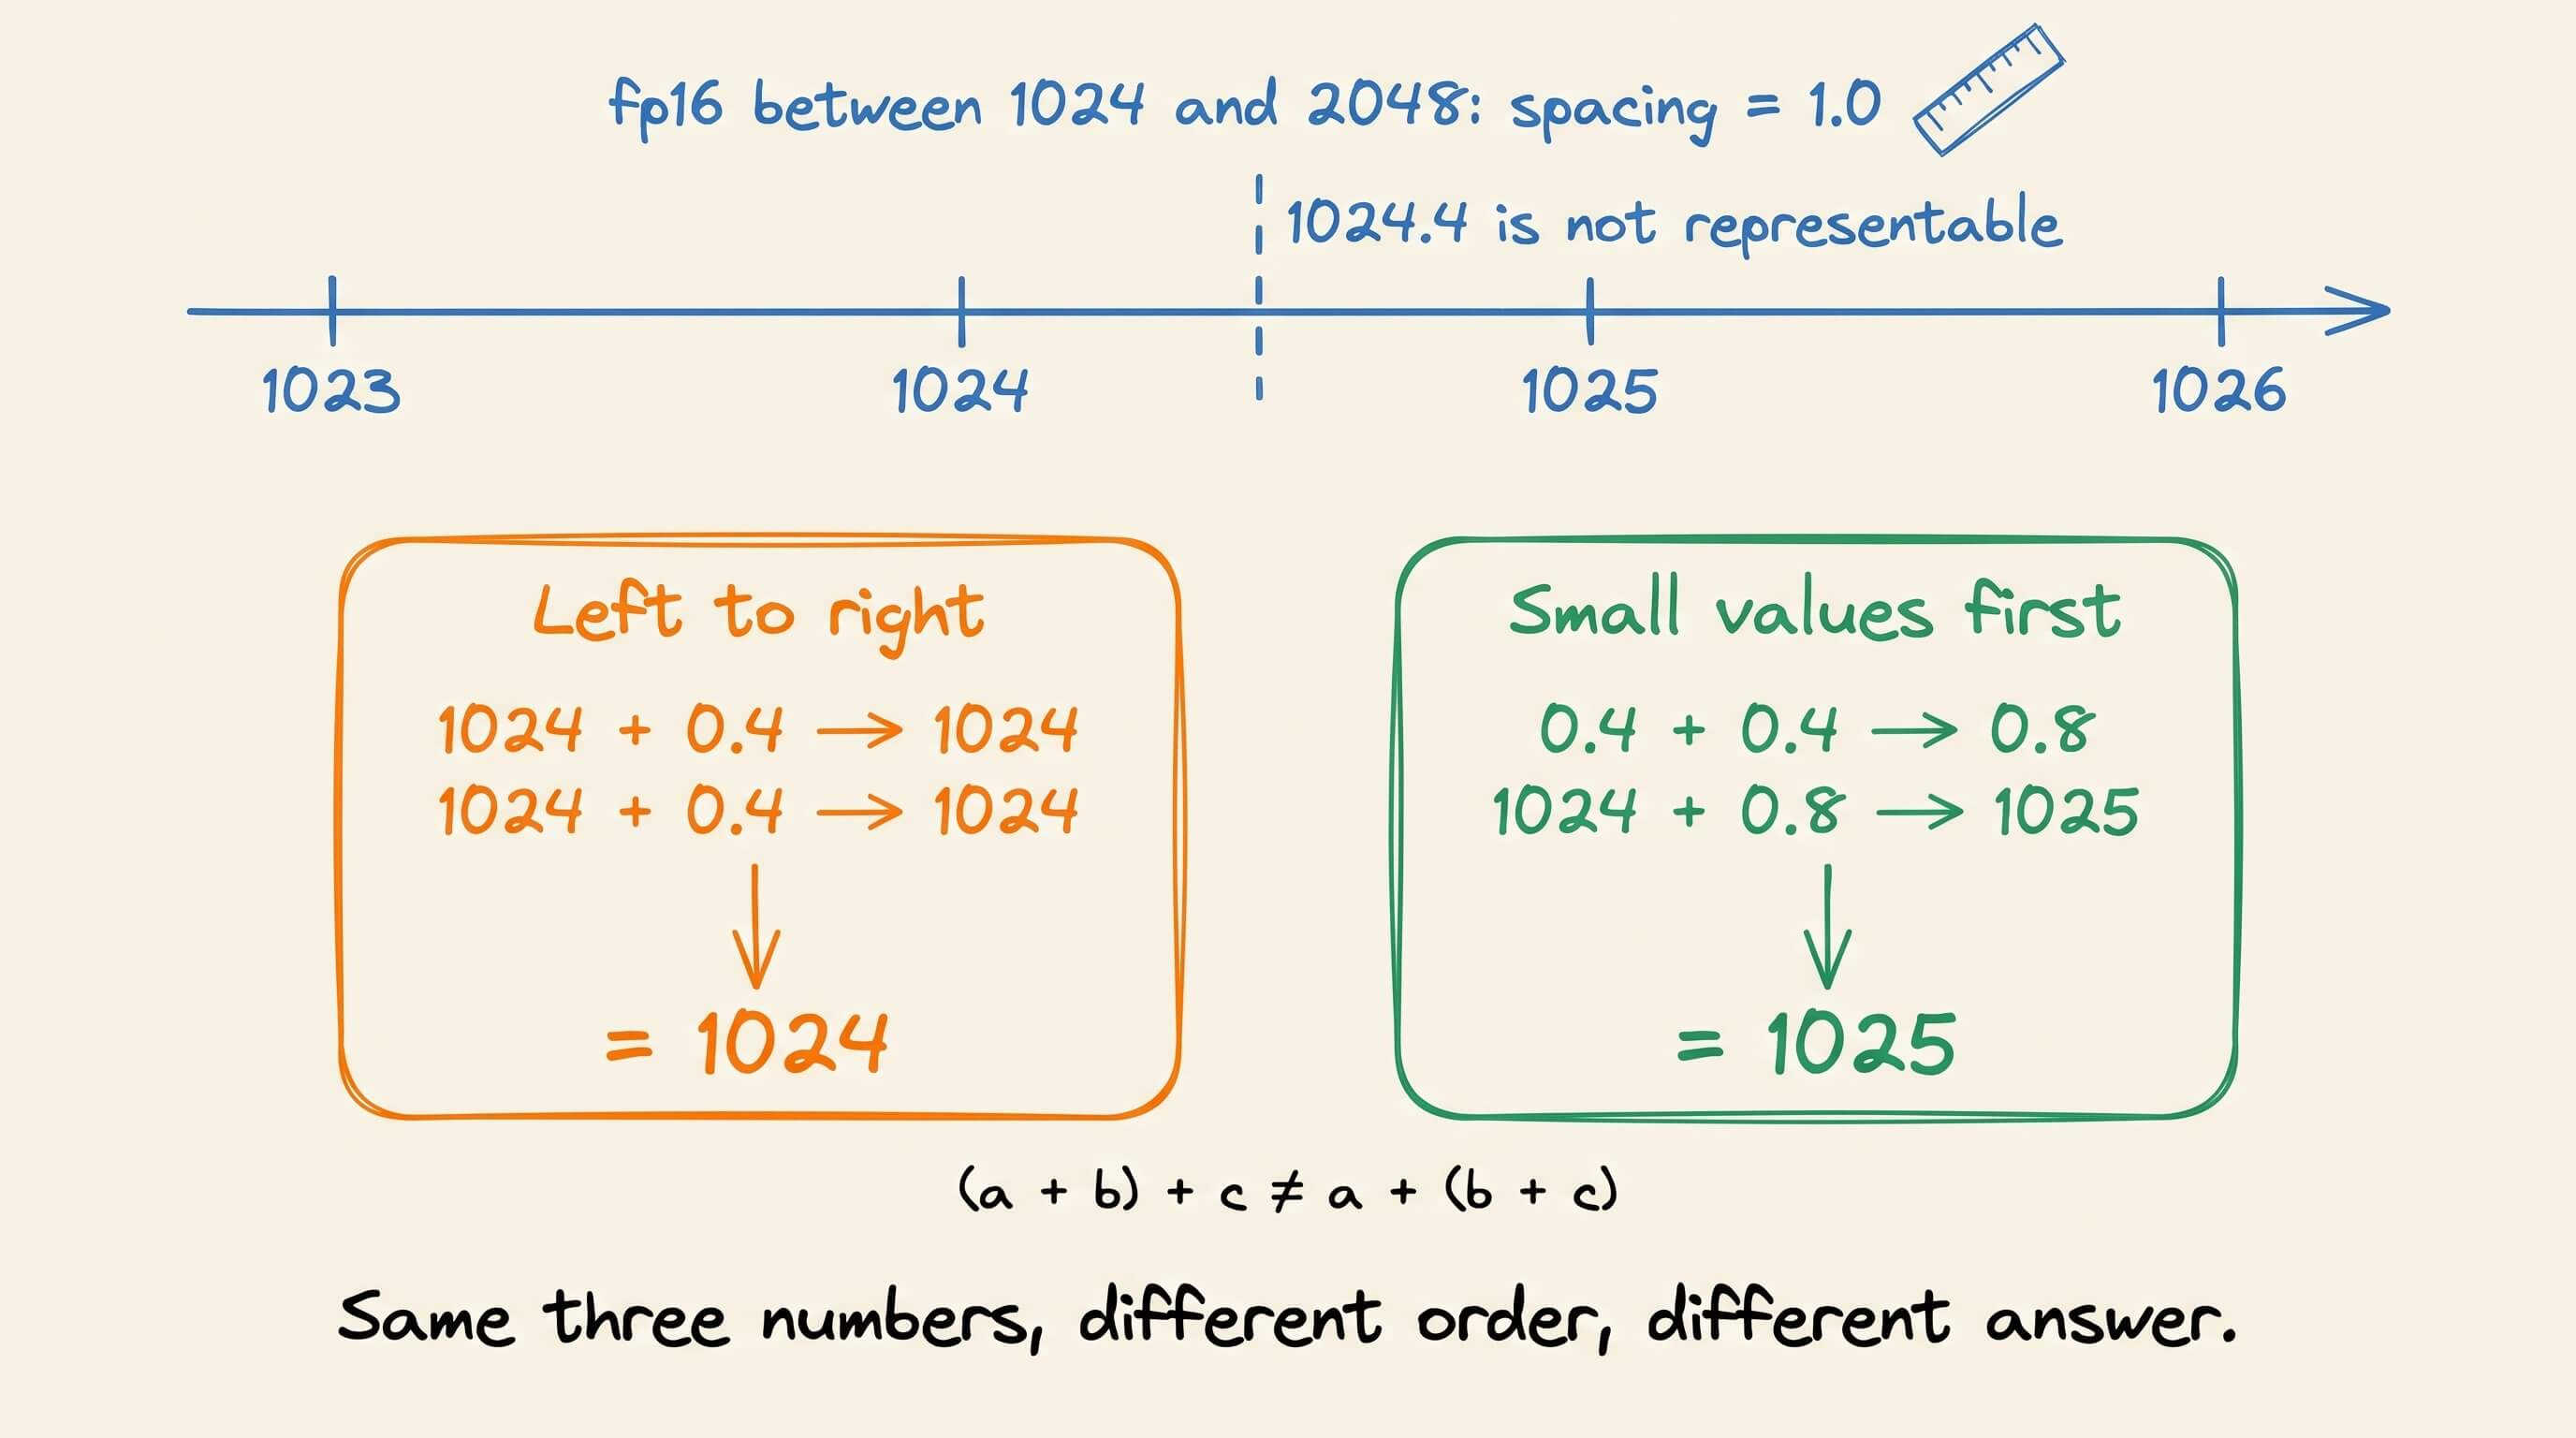
The catch is that floating-point addition isn’t associative. Every addition rounds to the nearest representable value, so (a + b) + c and a + (b + c) can differ in the low-order bits.
fp16 has an 11-bit significand, so between 1024 and 2048, representable values are 1.0 apart.
↳ Add 1024 + 0.4 + 0.4 left to right, and each step rounds back to 1024.
↳ Add the small values first, and 0.4 + 0.4 gives 0.8, then 1024 + 0.8 rounds to 1025.
Why batch size changes the order
GPU kernels pick the parallelization strategy that keeps the GPU busiest, and that choice depends on batch size.
An H100 SXM has 132 SMs, its compute units. A small batch doesn’t give each of them enough work.
So the kernel splits each long sum into chunks, adds the chunks on different SMs at the same time, then adds the partial results together. This is a split reduction, called split-K in matmuls and split-KV in attention.
A larger batch has enough rows to keep every SM busy, so each row’s sum stays on one SM and gets added in a single pass.
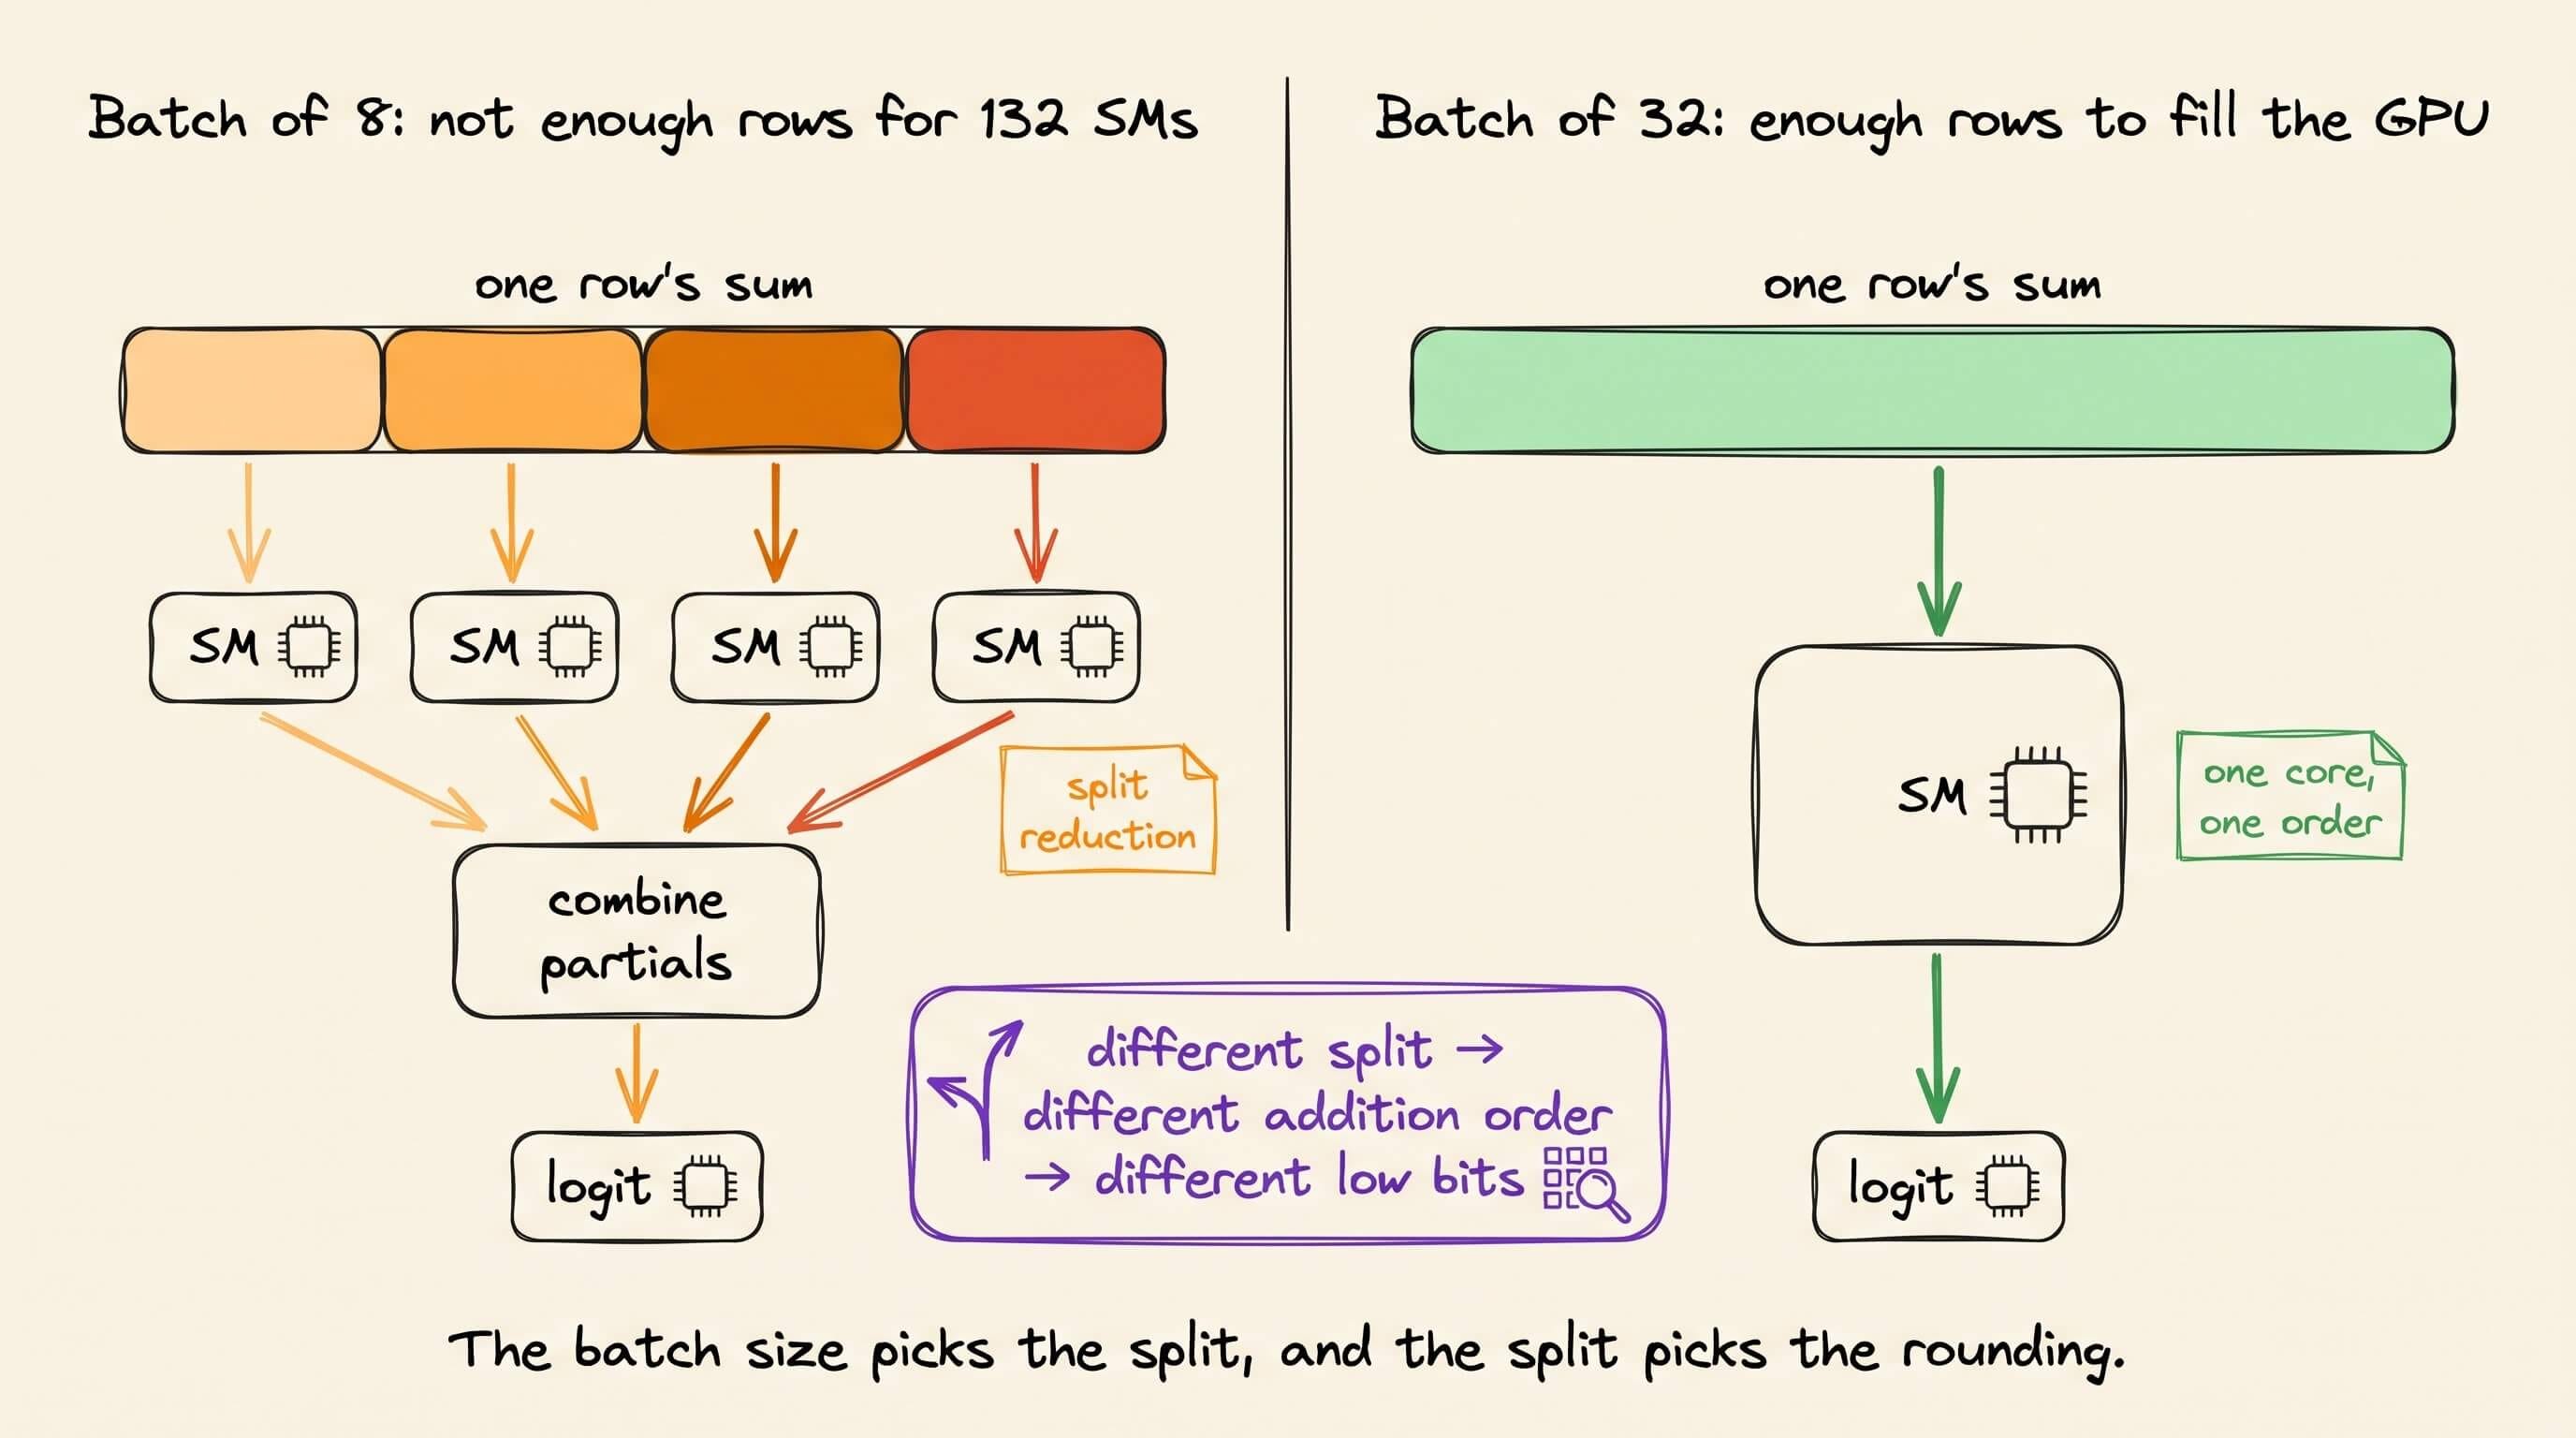
Different batch size, different split, different order of additions, slightly different logits.
This isn’t random noise. Run the exact same batch twice and you get bitwise identical results. The output only changes when the batch around your request changes.
How a tiny difference flips a token
Usually the difference is negligible. It matters when two tokens are nearly tied.
Say that in a batch of 8, “Queens” scores 12.3417 and “New” scores 12.3415. In a batch of 32, rounding shifts them to 12.3414 and 12.3416.
At temperature 0, argmax picks “Queens” in the first case and “New” in the second. Every later token is conditioned on a different prefix, so the whole completion diverges.
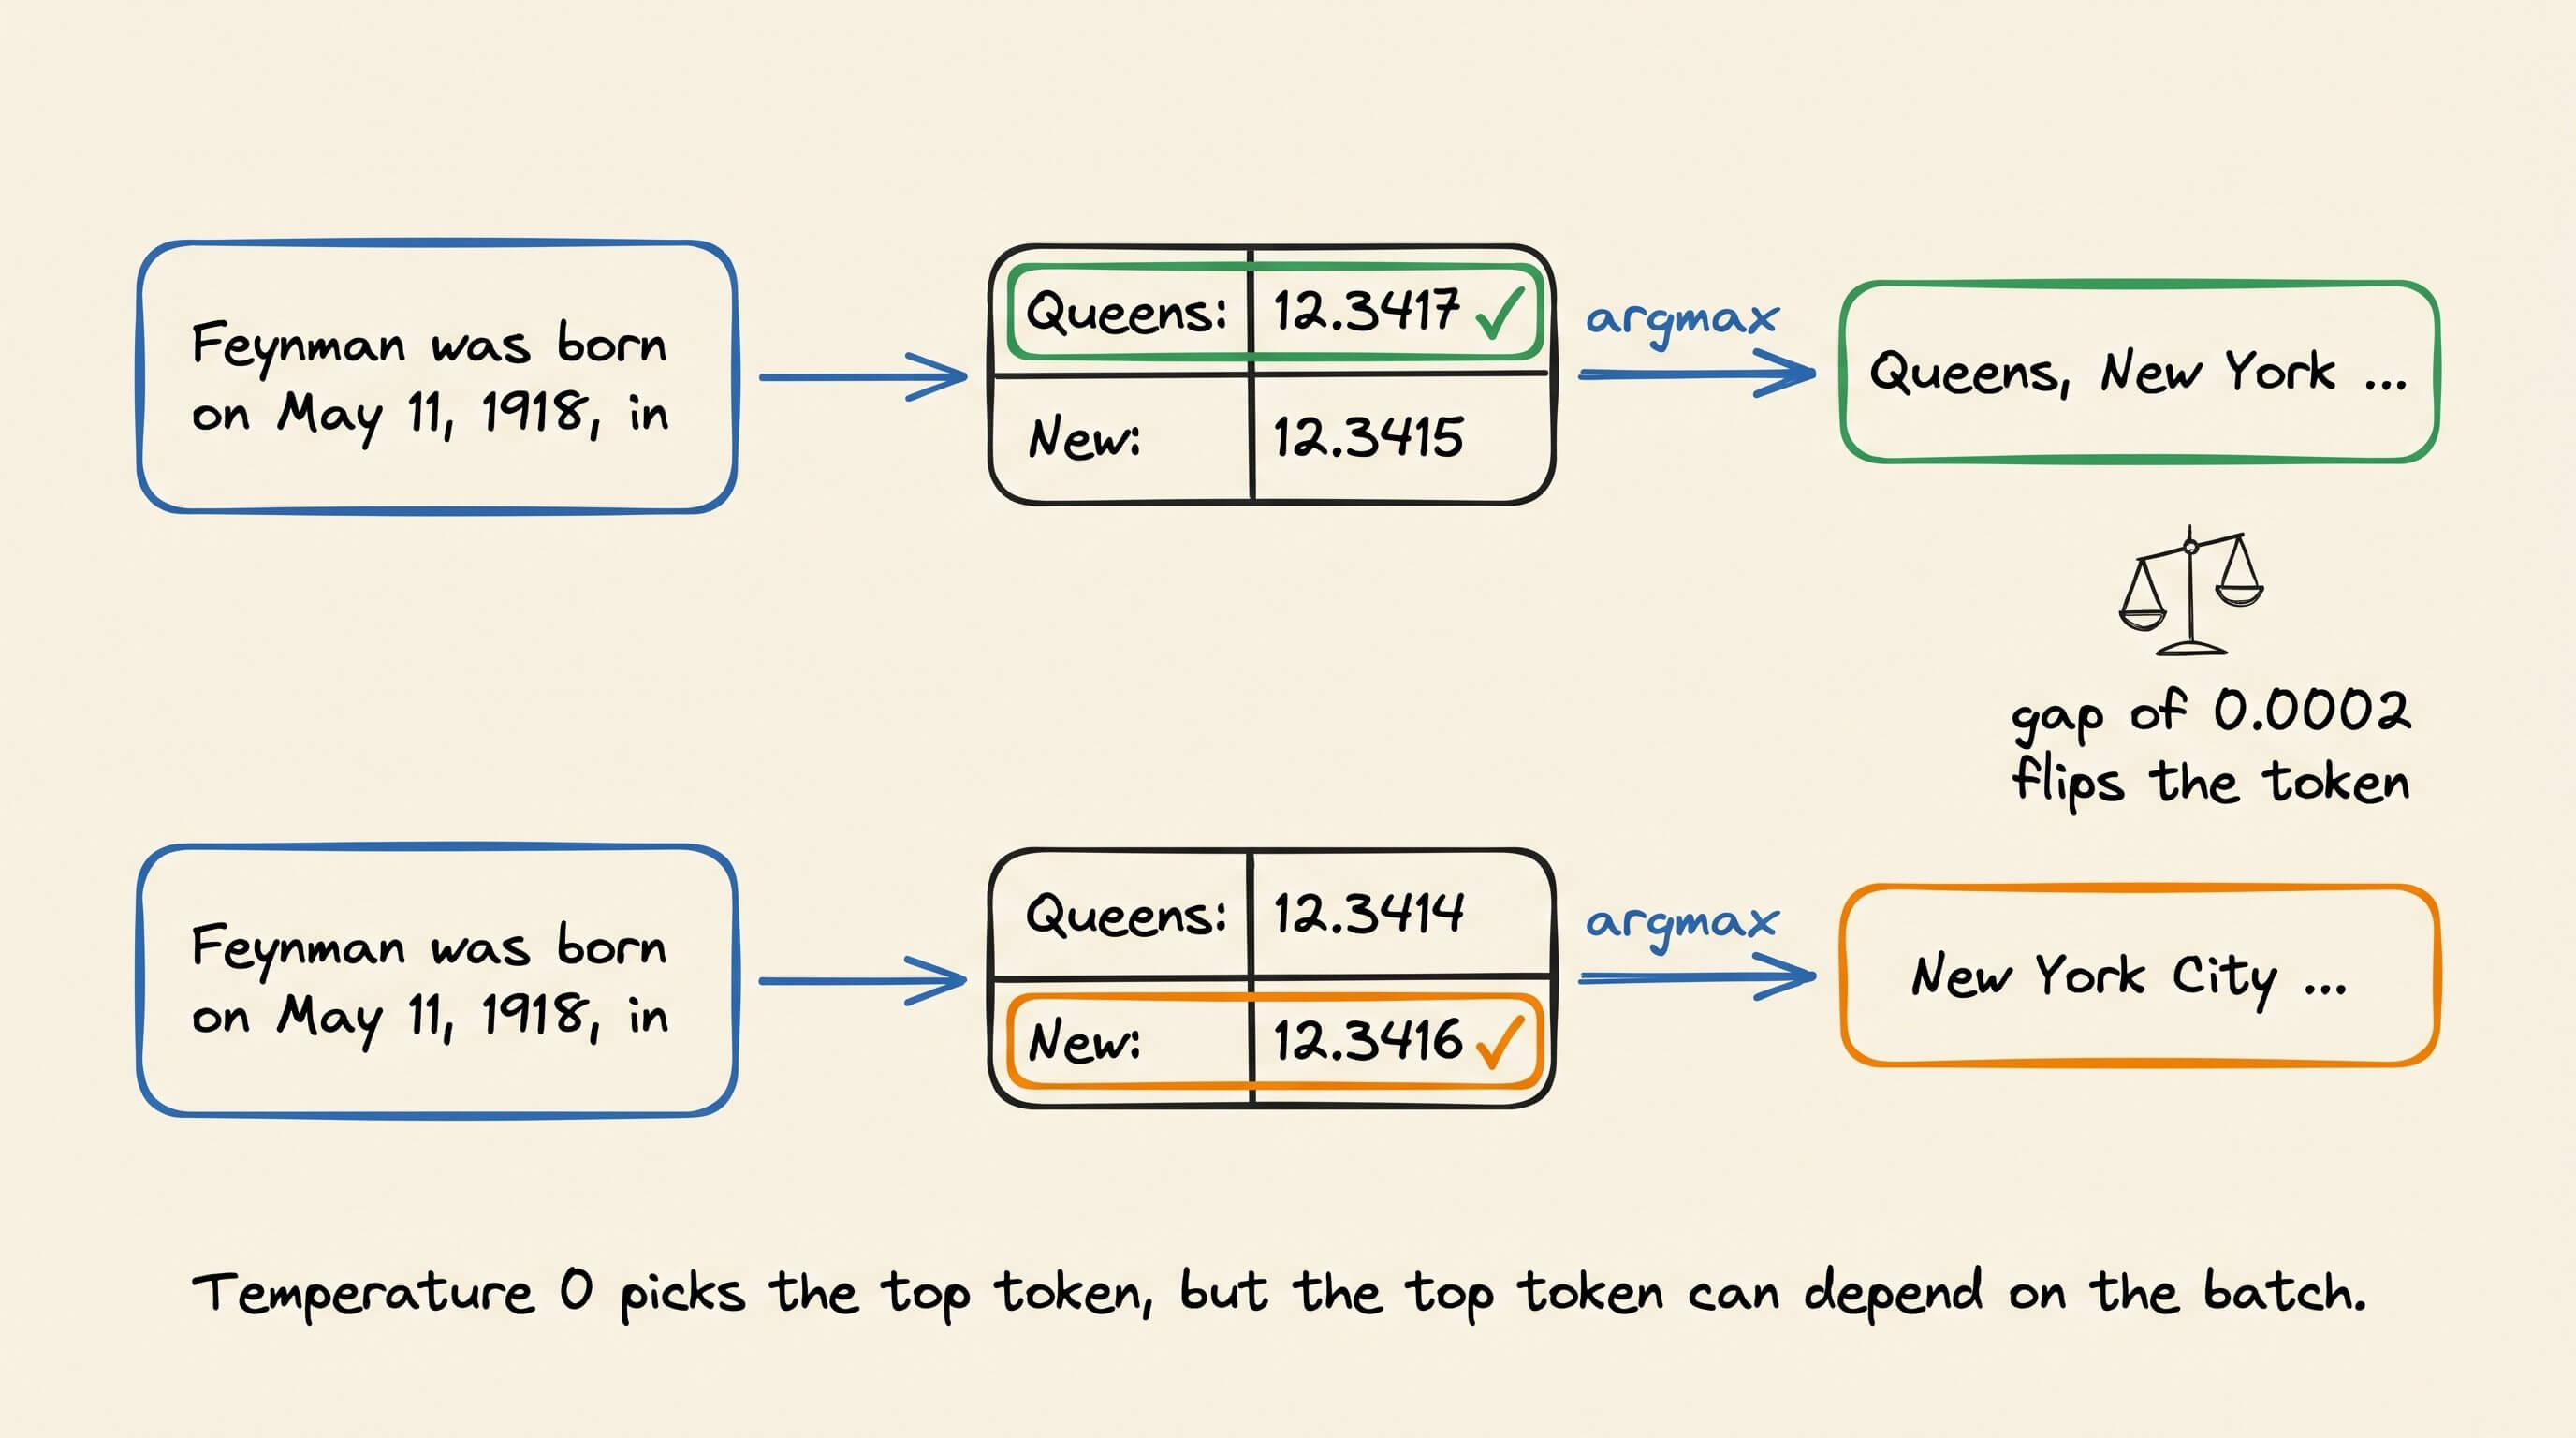
So temperature 0 doesn’t make inference deterministic. The sampler is deterministic, but it reads logits from a forward pass whose numerics depend on traffic you don’t control.
The fix: batch-invariant kernels
The fix is to make every reduction batch invariant. Each row gets reduced in the same fixed order, no matter how many rows share the batch.
This costs throughput. The kernel can no longer pick the best split for each batch size, so it uses one fixed strategy even when that leaves SMs idle.
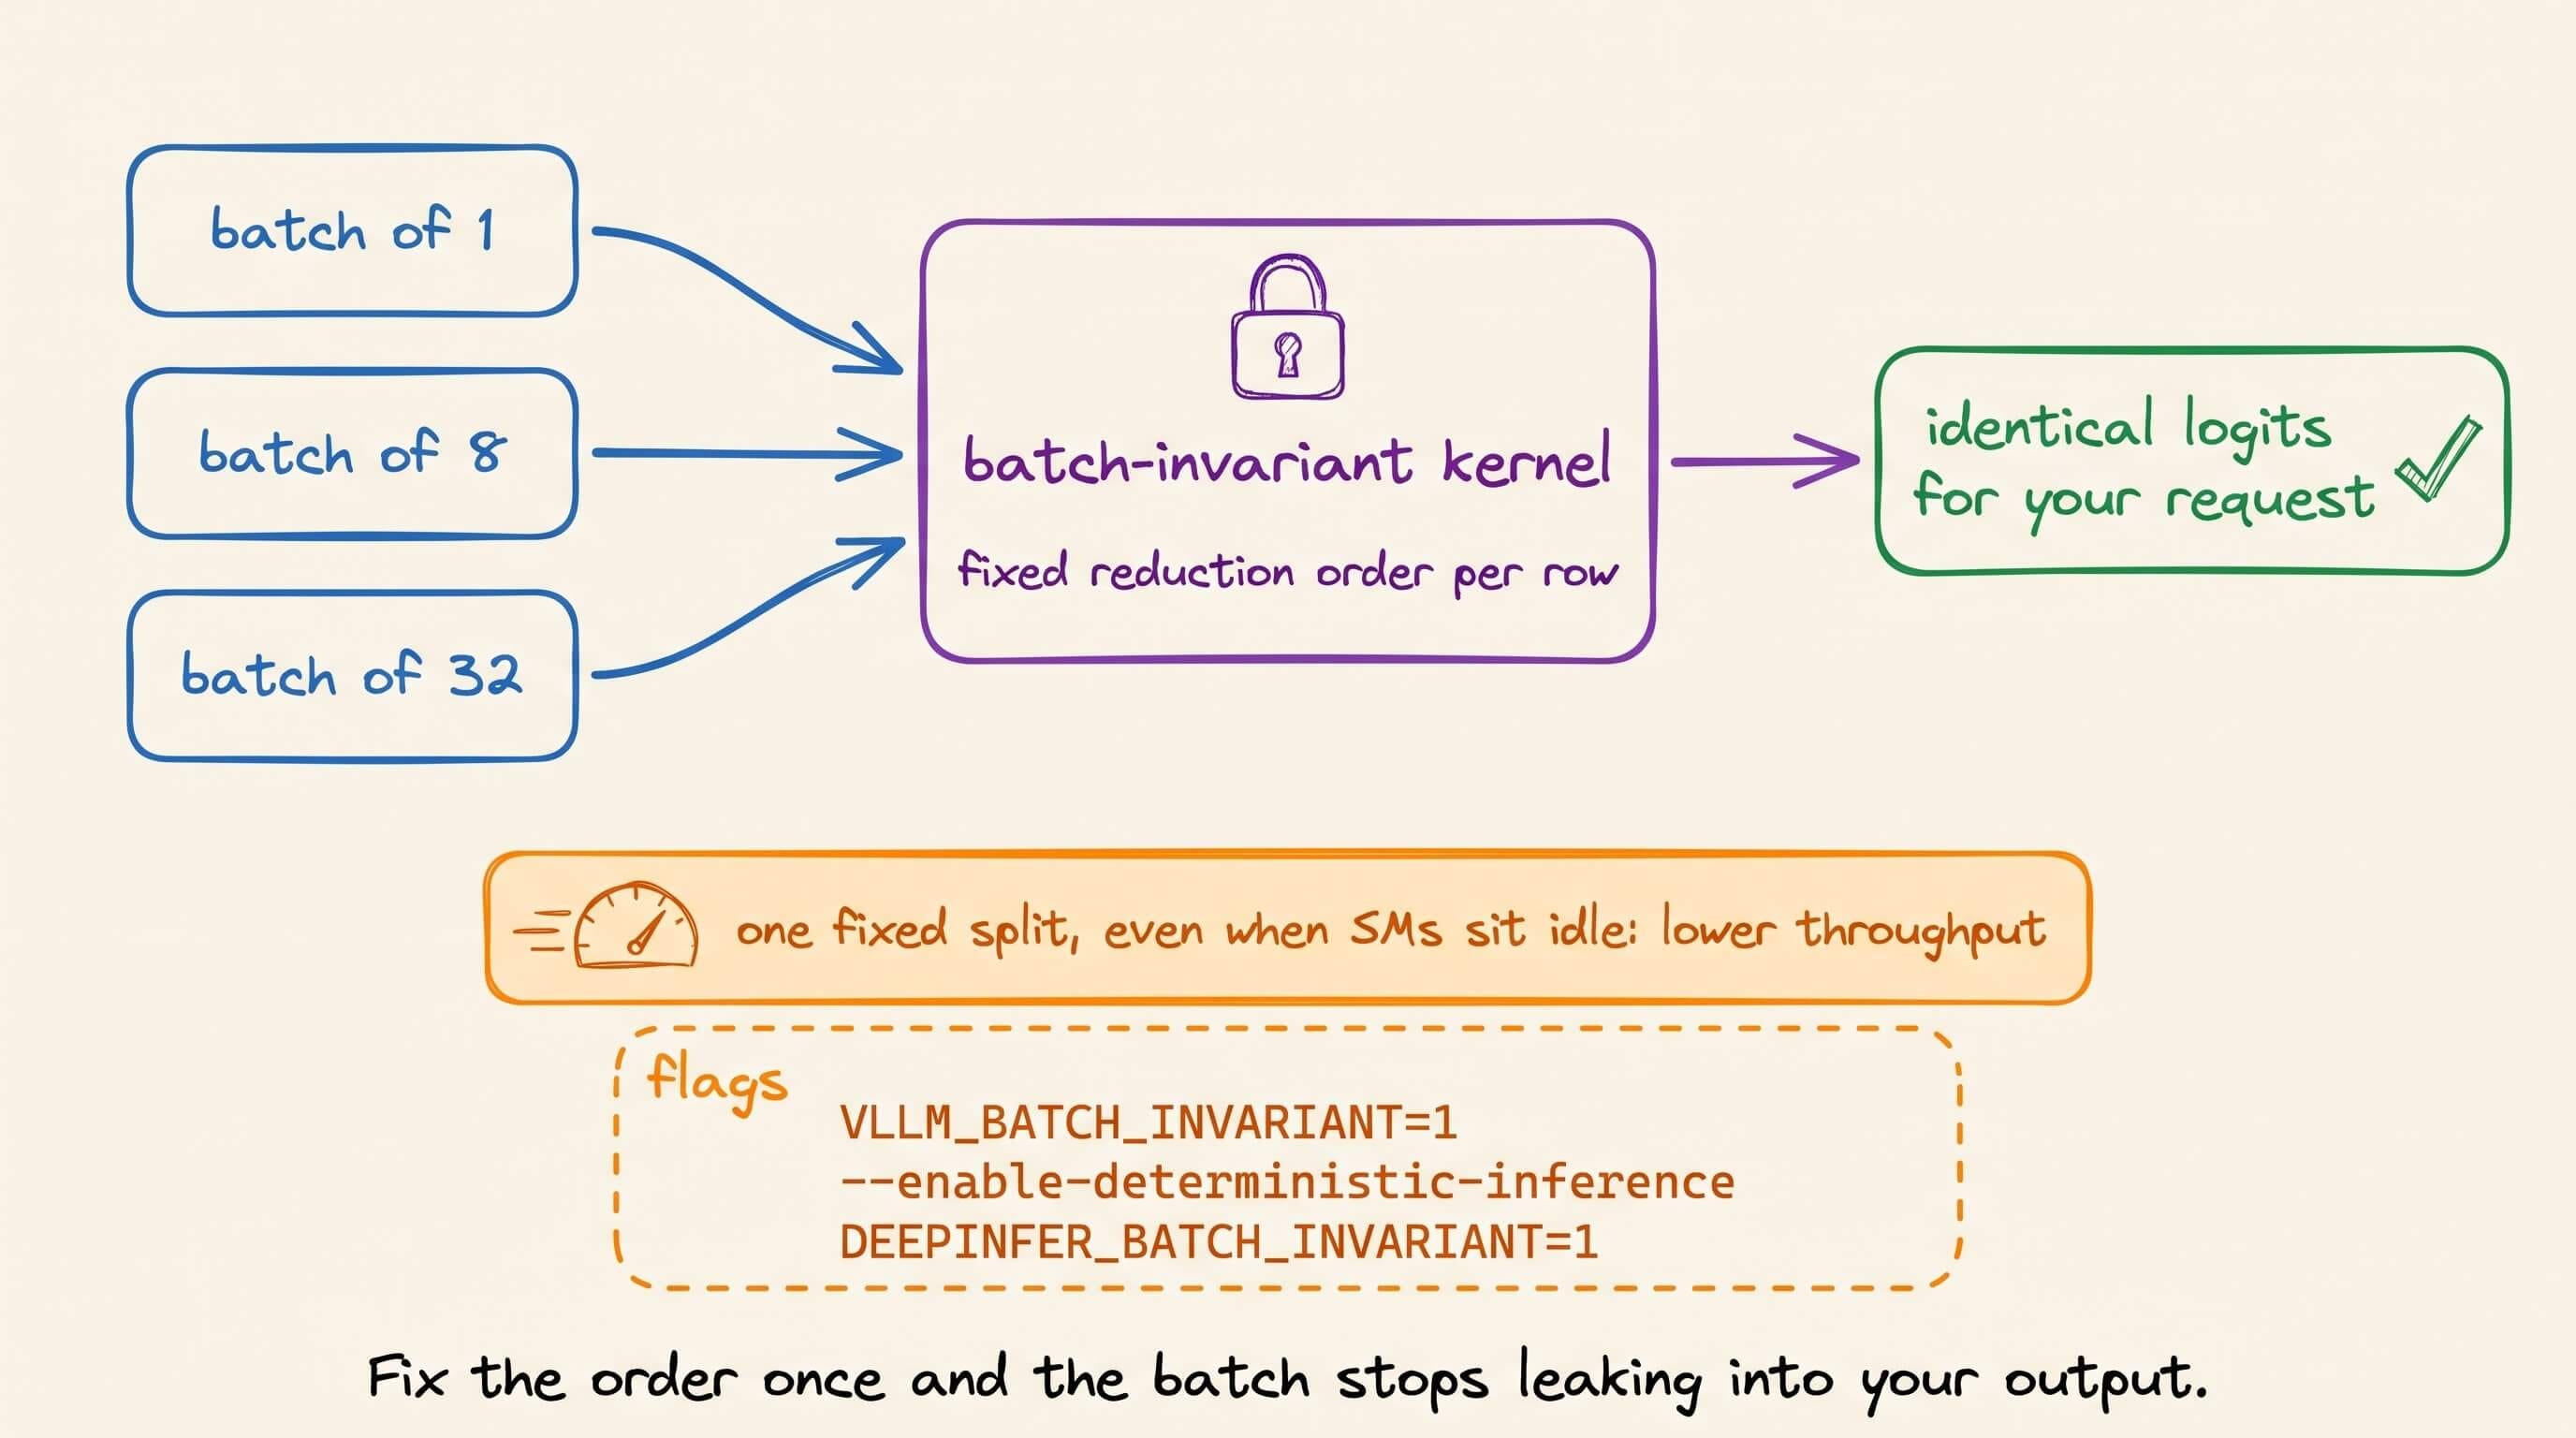
The major inference engines now expose this as a flag:
↳ vLLM has VLLM_BATCH_INVARIANT=1, still in beta.
↳ SGLang has --enable-deterministic-inference, with most slowdowns between 25% and 45% in the LMSYS benchmarks.
↳ DeepSeek’s DeepInfer has DEEPINFER_BATCH_INVARIANT=1, on NVIDIA GPUs only.
# vLLM
VLLM_BATCH_INVARIANT=1 vllm serve Qwen/Qwen3-8B

# SGLang
python3 -m sglang.launch_server --model-path Qwen/Qwen3-8B \
  --attention-backend fa3 --enable-deterministic-inference
With batch-invariant kernels on, Thinking Machines got all 1,000 Feynman completions identical.
If you run evals, RL rollouts, or anything else that needs reproducible outputs, turn it on and treat batch composition as part of your experimental setup.
RL gains the most. When the sampler and the trainer compute bitwise identical numbers, training stays truly on-policy. In the Thinking Machines run, the KL divergence between sampler and trainer stayed flat at 0.
Why production makes this worse
In production, the batch around your request never stays fixed. With continuous batching, the server adds and removes requests at every decoding step.
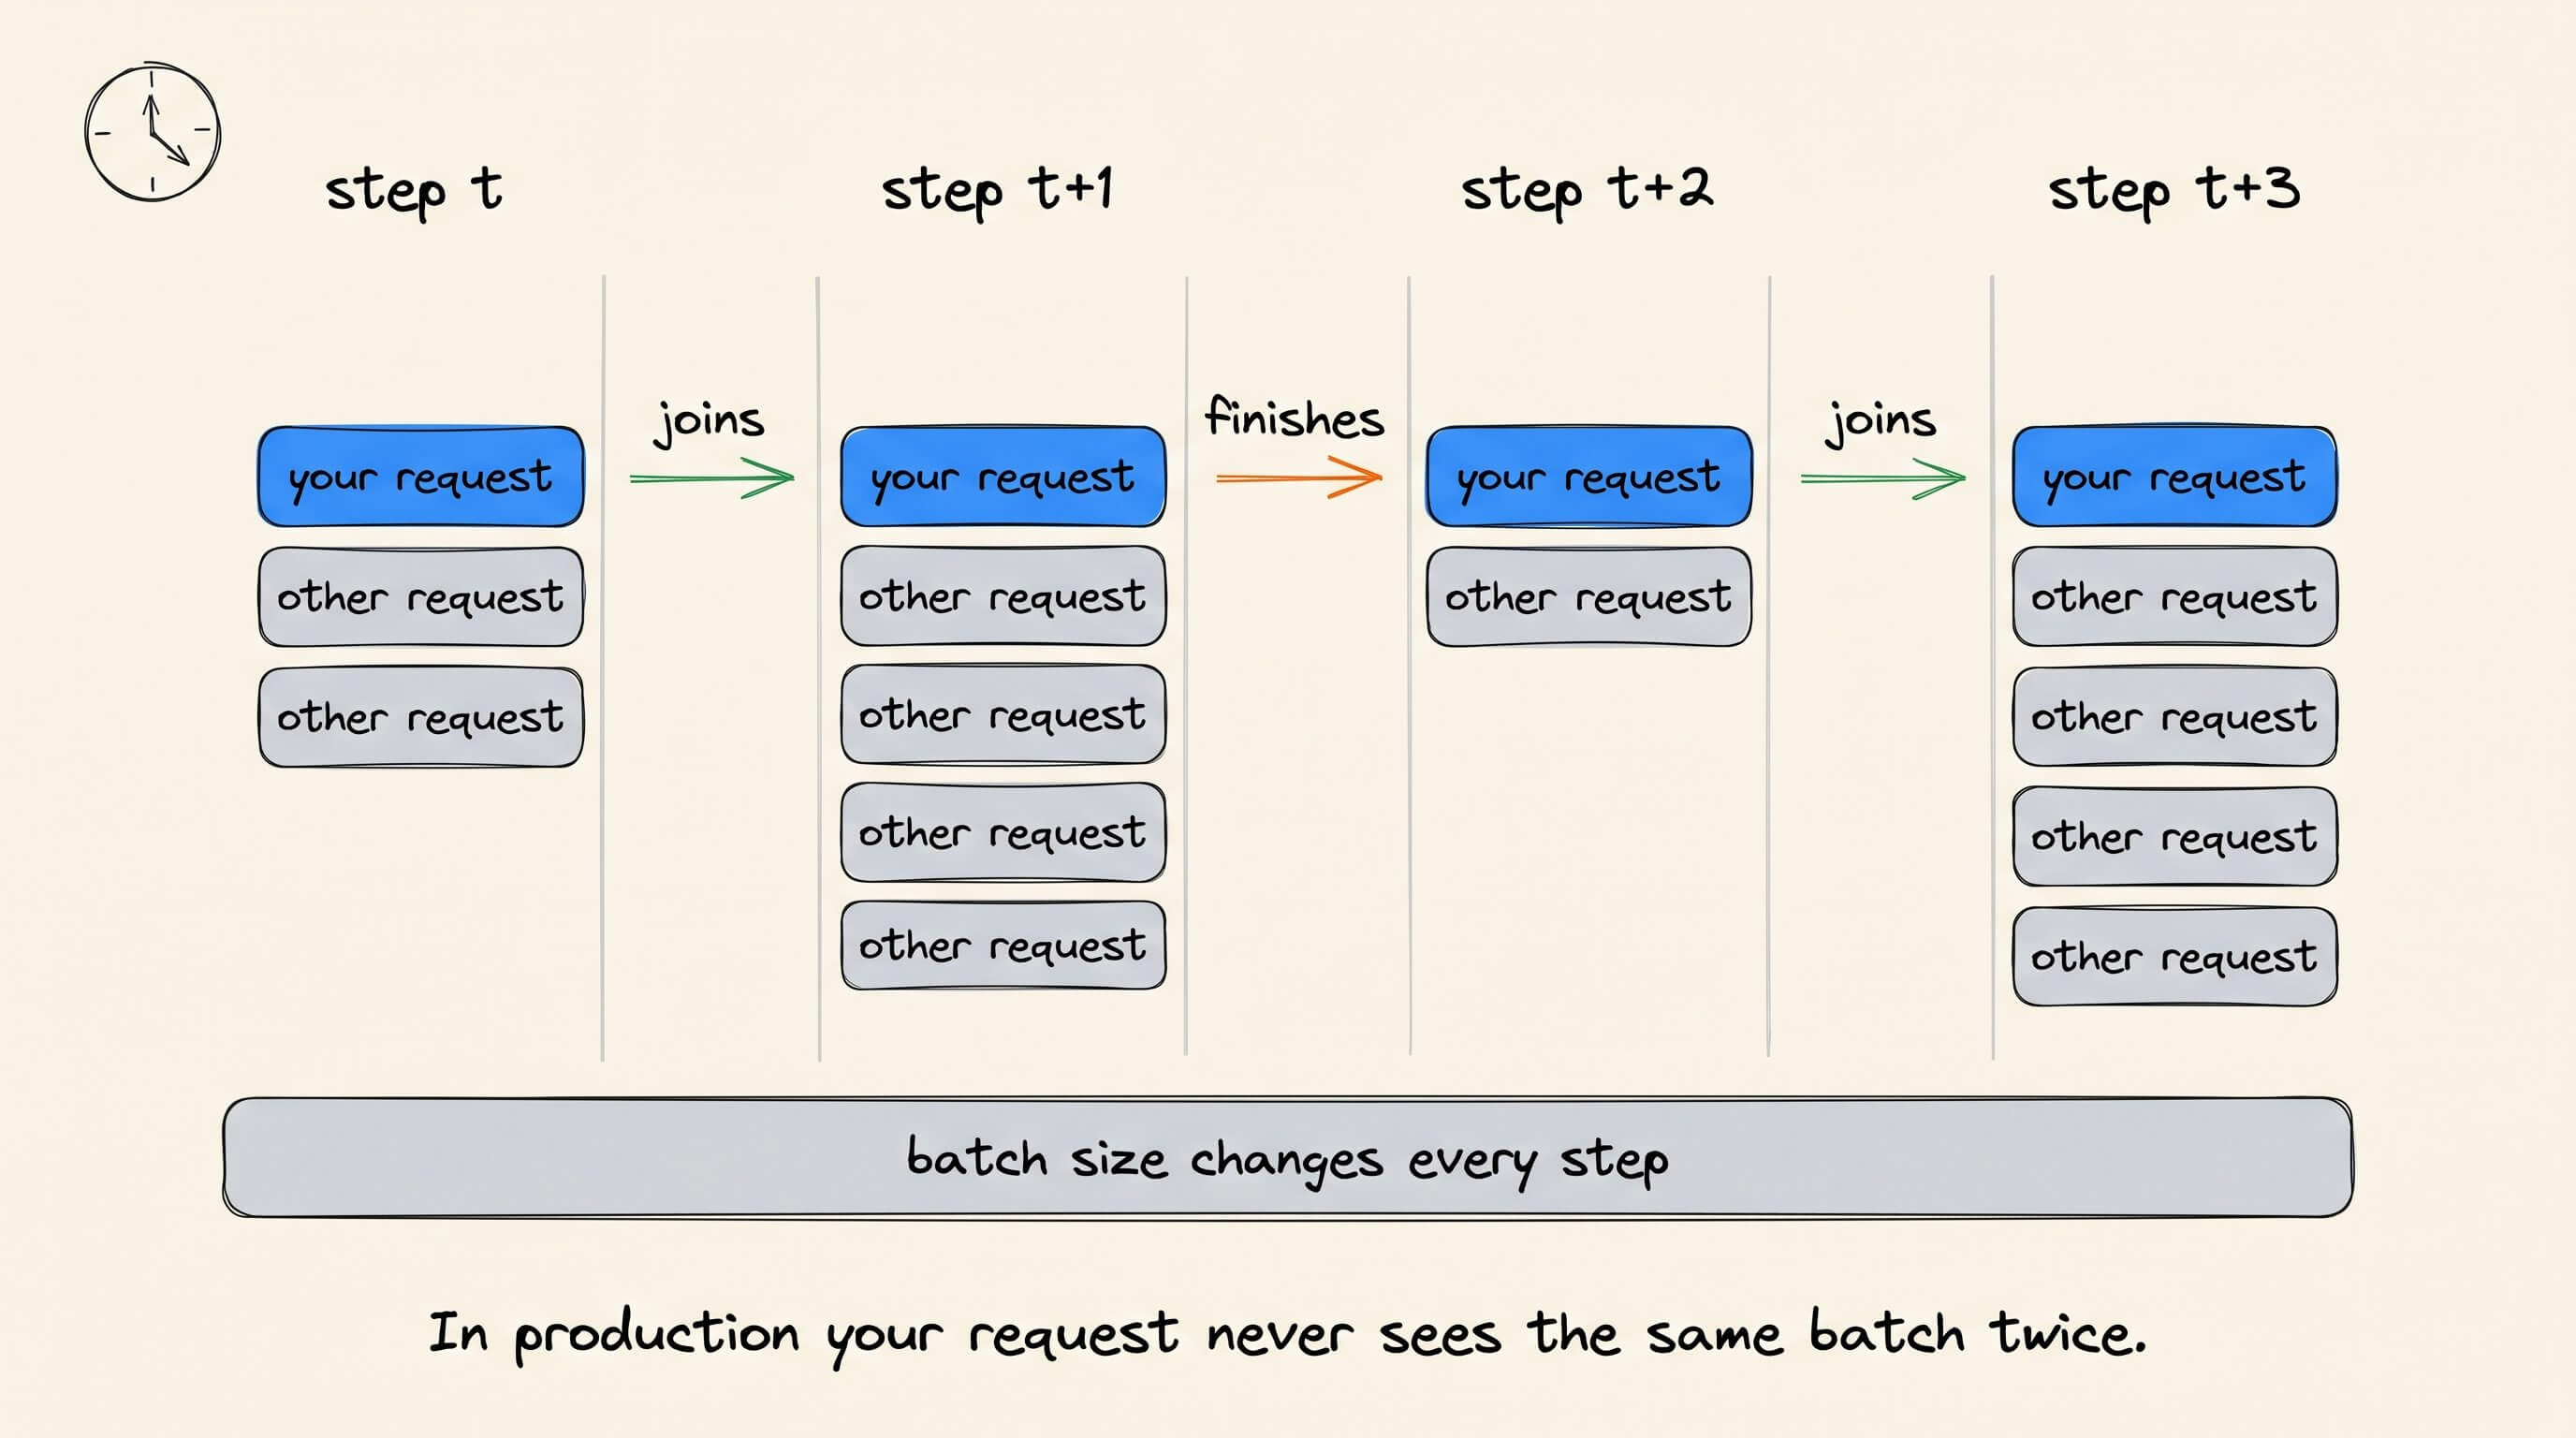
So your request can run at a different batch size for every token it generates.
RAG vs. retriever-free RAG, clearly explained!
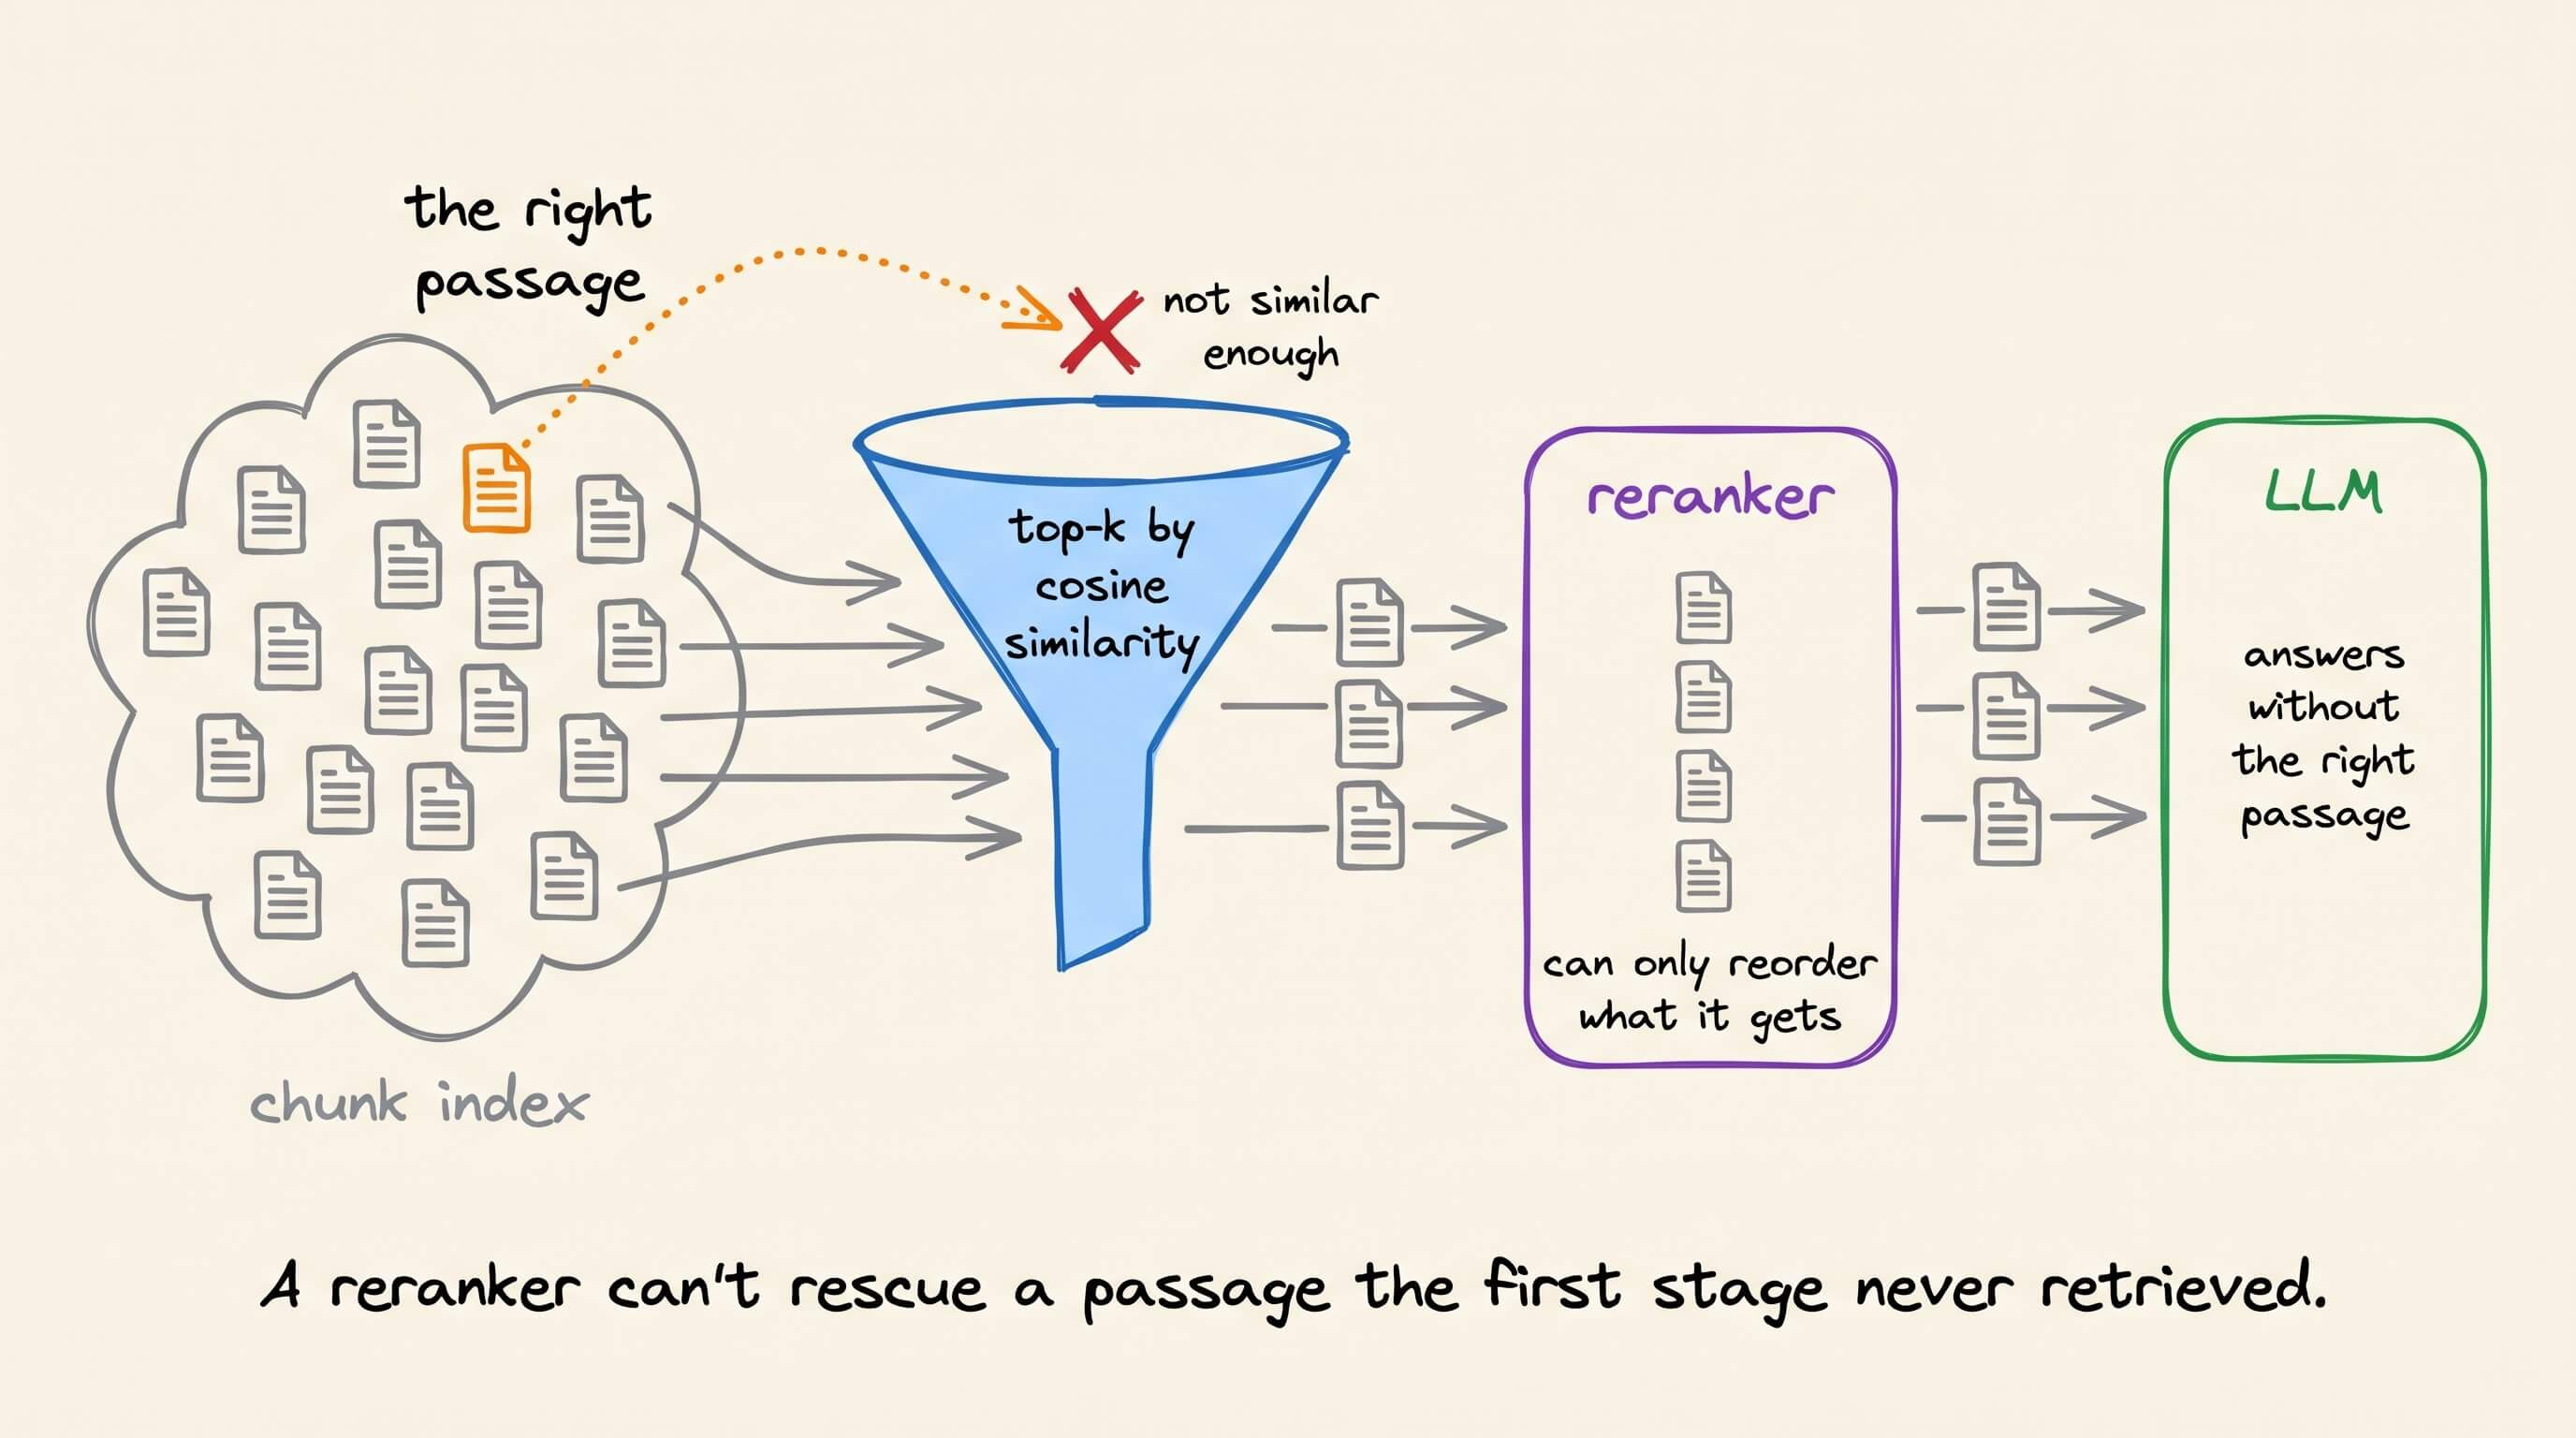
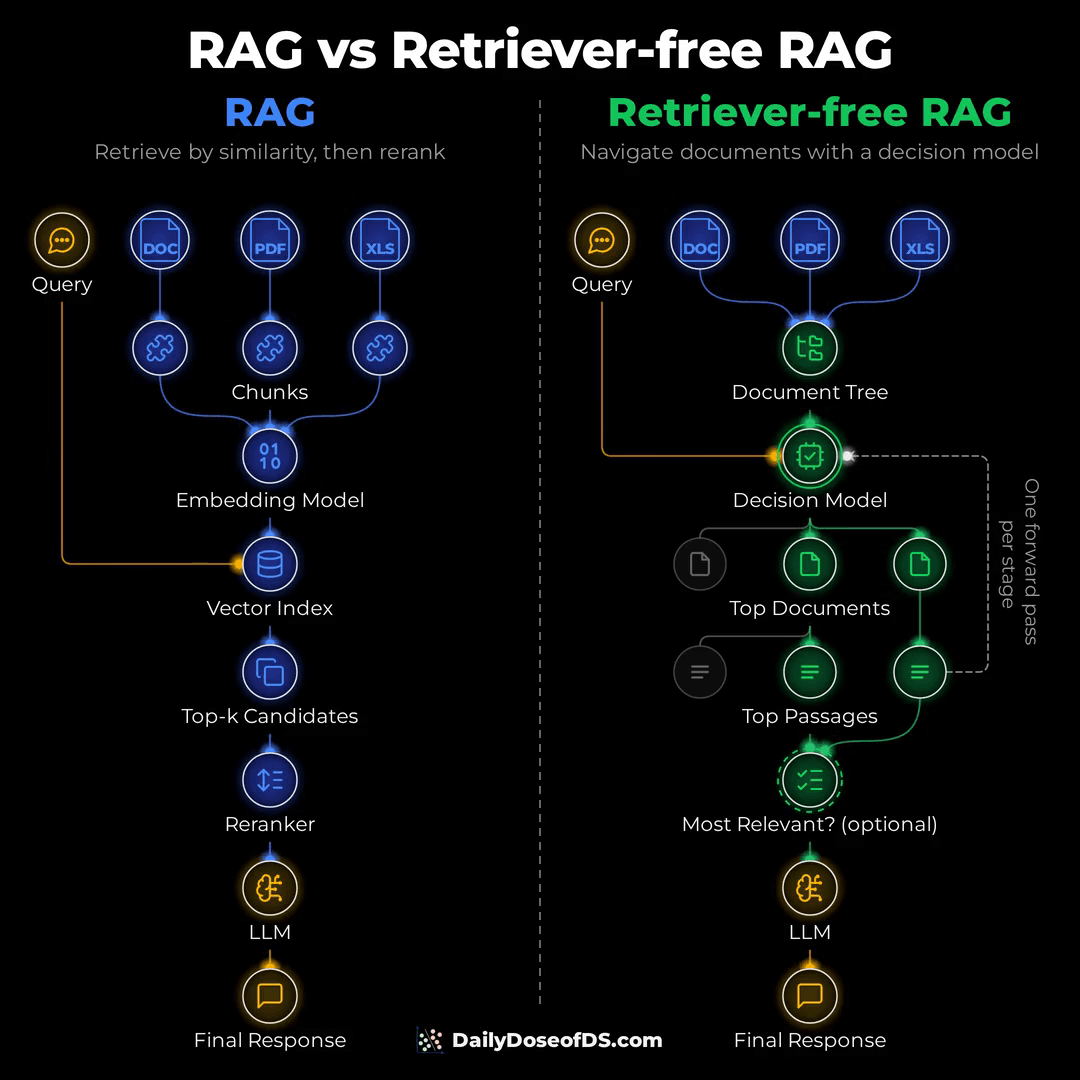
In standard RAG, similarity search decides what the LLM can ever see.
Documents are split into chunks, embedded, and stored in a vector index. When a query arrives, the system embeds it and pulls the top-k chunks with the closest vectors. A reranker reorders those candidates, and the best few go to the LLM.
If the right passage never made the top-k, nothing later in the pipeline can bring it back, not even a strong reranker.
Yesterday we covered vectorless RAG, where an LLM reads a document tree and picks sections. Retriever-free RAG, from a new Cornell and ASAPP paper, also walks a tree. But it uses a decision model to do it, not a generative LLM.
What a decision model does
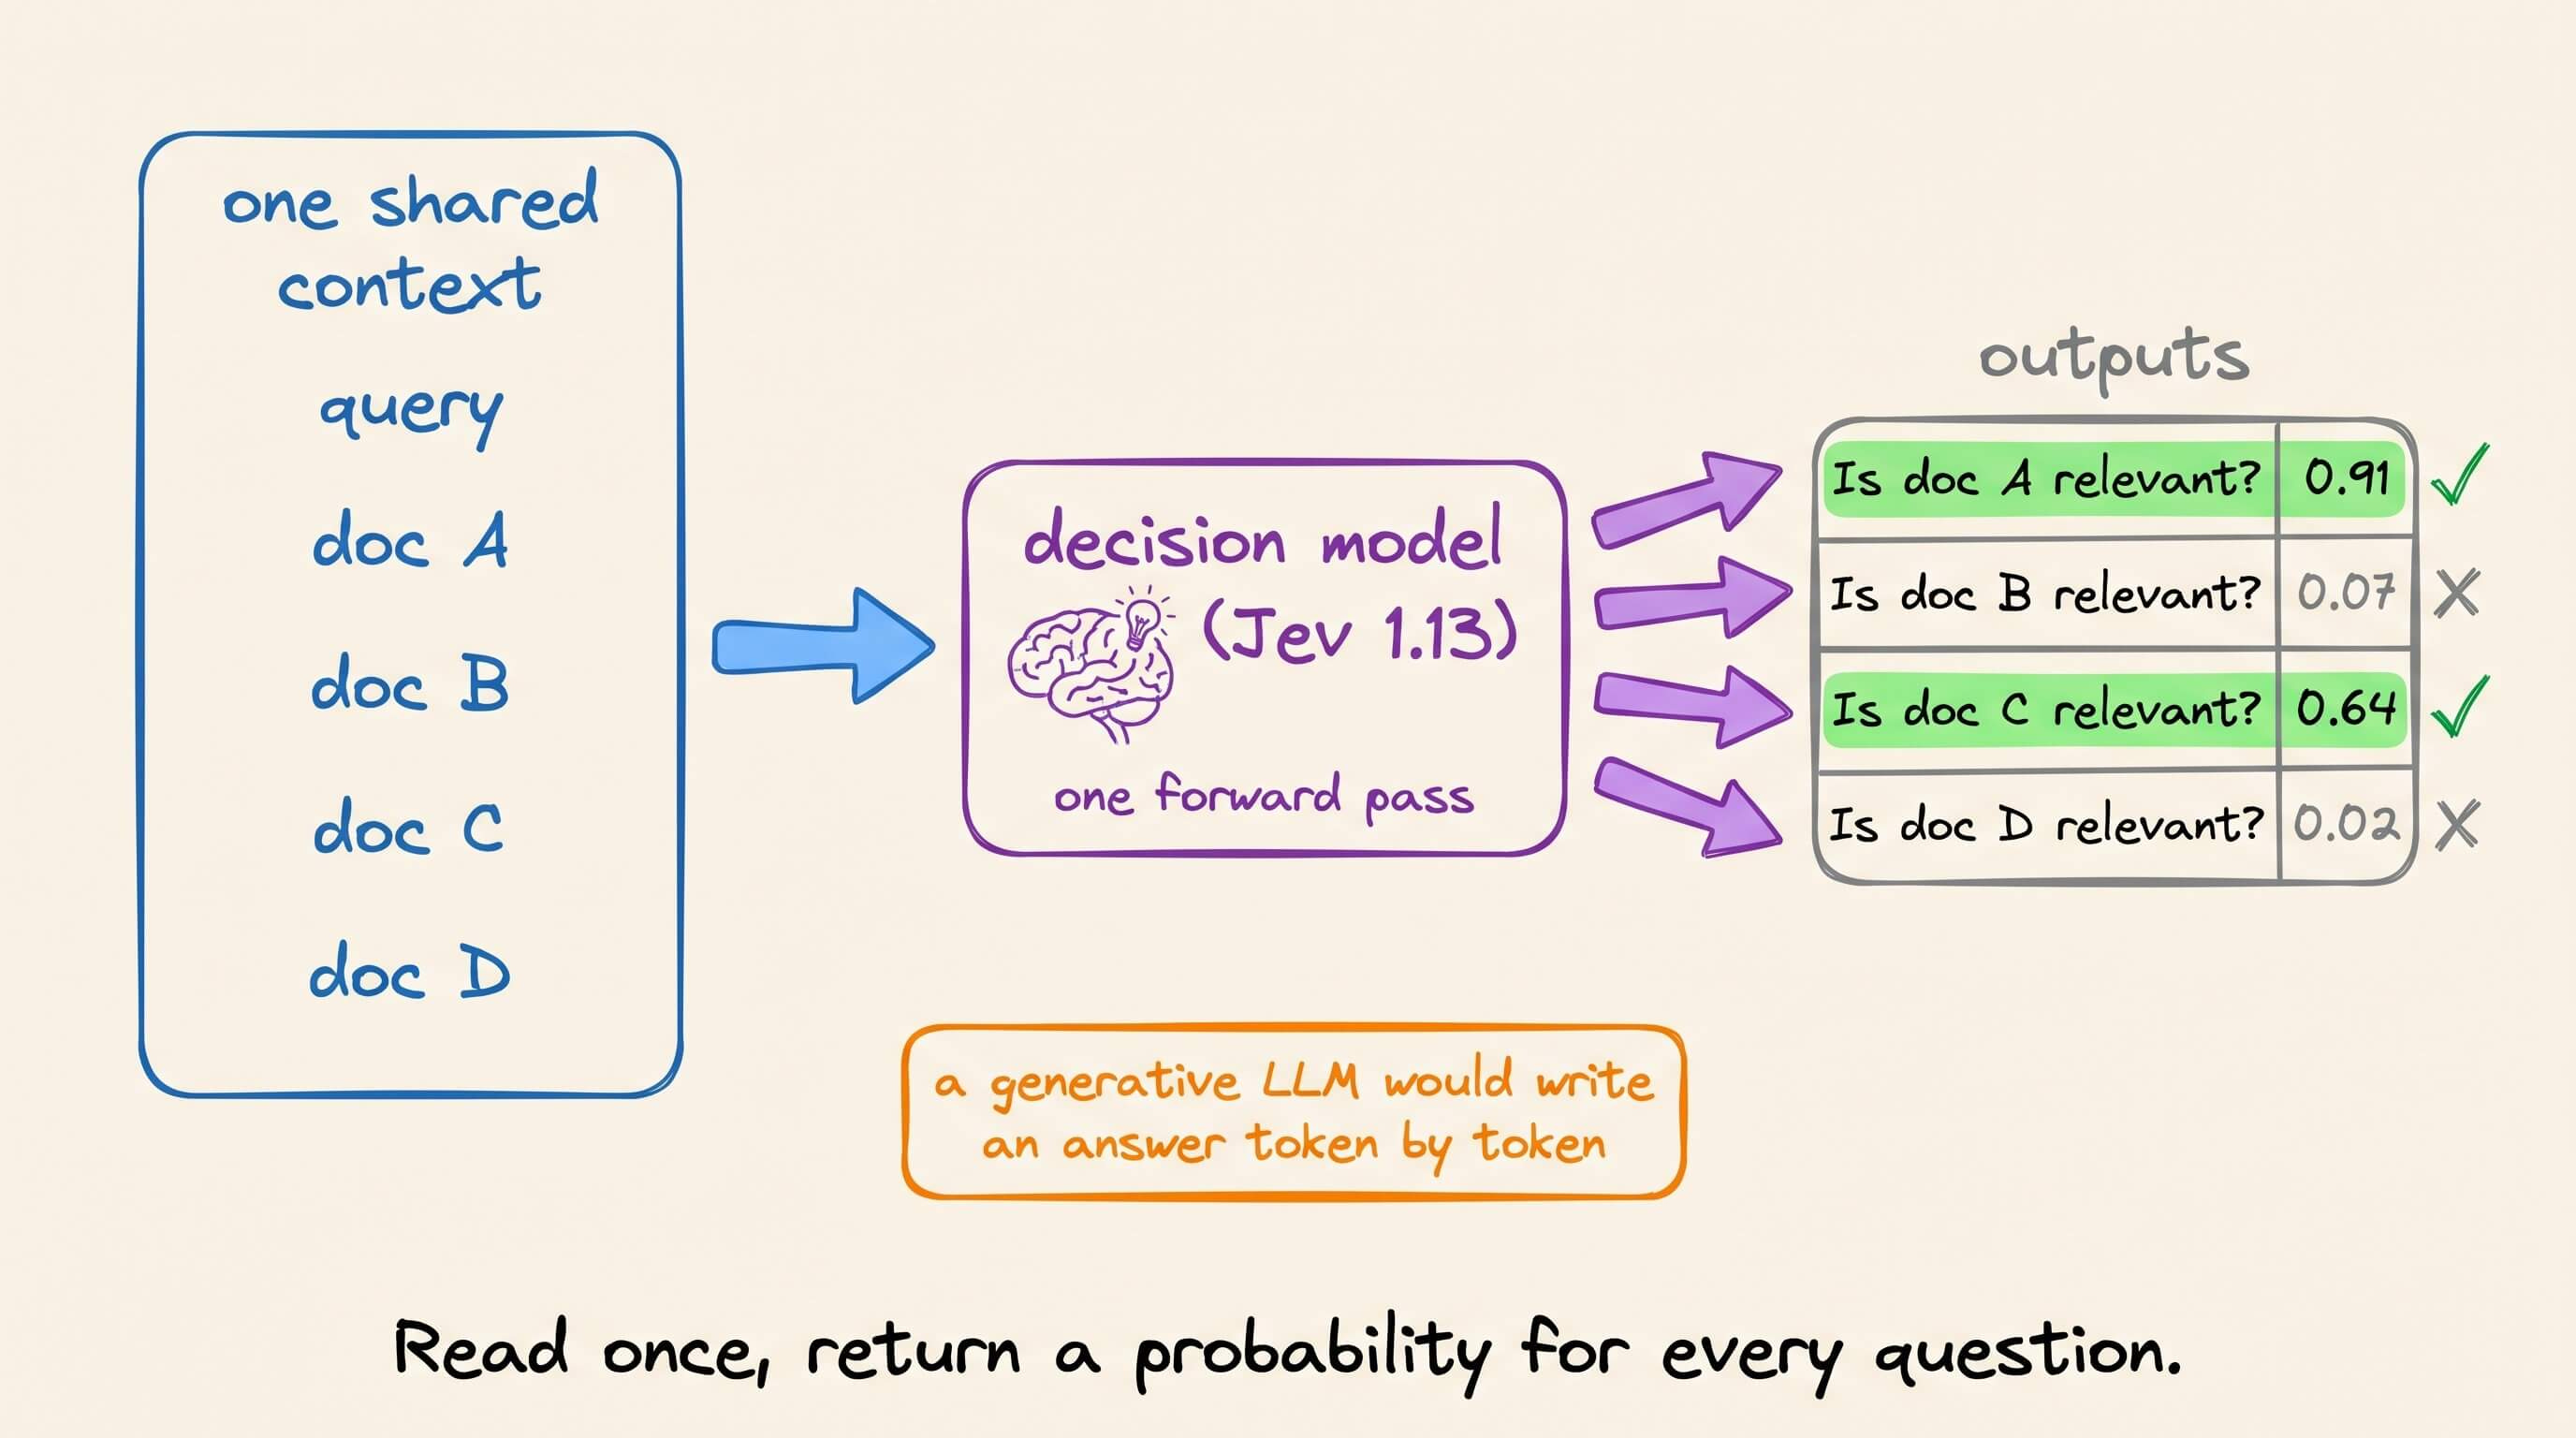
A decision model doesn’t generate text. It reads one shared context and returns a probability for every yes/no question about it, in one forward pass.
The paper uses Jev 1.13. Put the query next to every candidate document, ask “Is this relevant?” for each, and a single pass scores all of them.
How a query moves through the tree
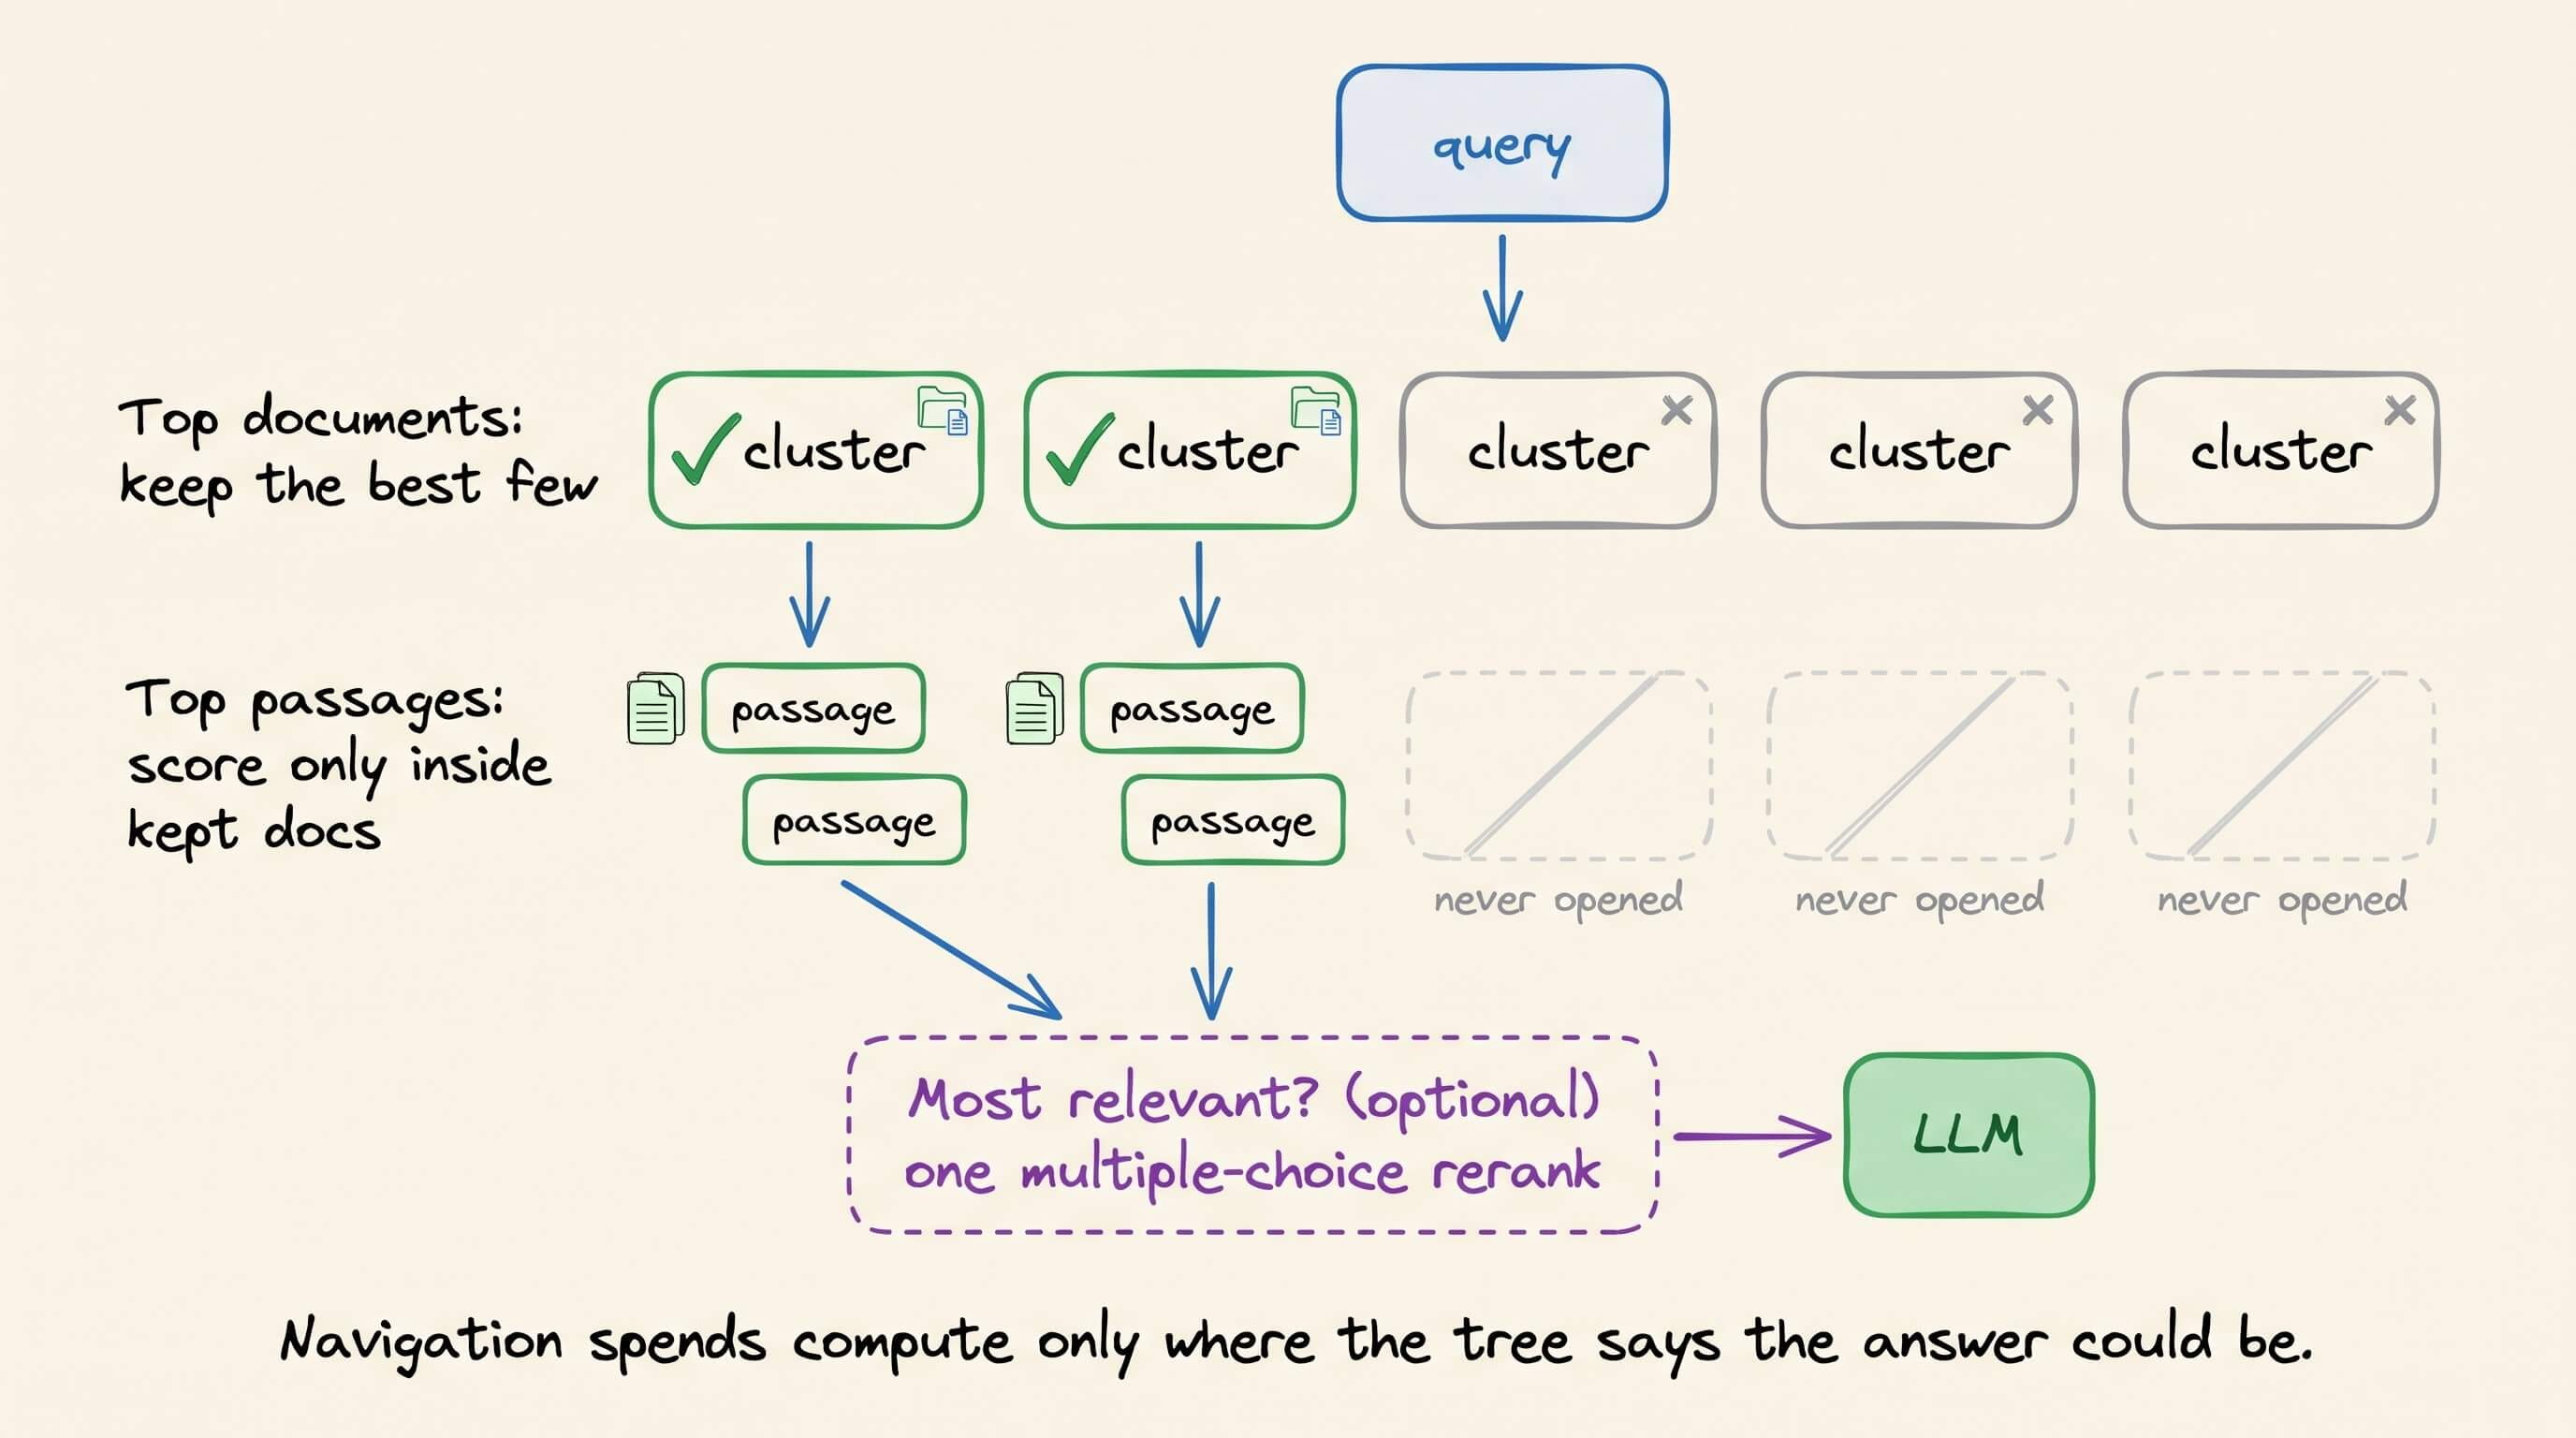
The documents are organized as a tree, like a table of contents, and the decision model walks down it:
↳ Top documents: the model reads the query next to every candidate document, asks “Is this relevant?” for each, and keeps the best few.
↳ Top passages: it opens only those documents and asks the same question for every passage inside them.
↳ Most relevant? (optional): a single multiple-choice question reorders the top 20 passages, or the top 5 on Natural Questions.
Dropped documents are never opened, so their passages are never scored.
For Wikipedia, the tree was built offline. The 2.68M paragraphs from 108,626 pages were grouped into 1,000 clusters using e5-base-v2 embeddings and k-means, and Qwen3-8B wrote the summaries.
The results
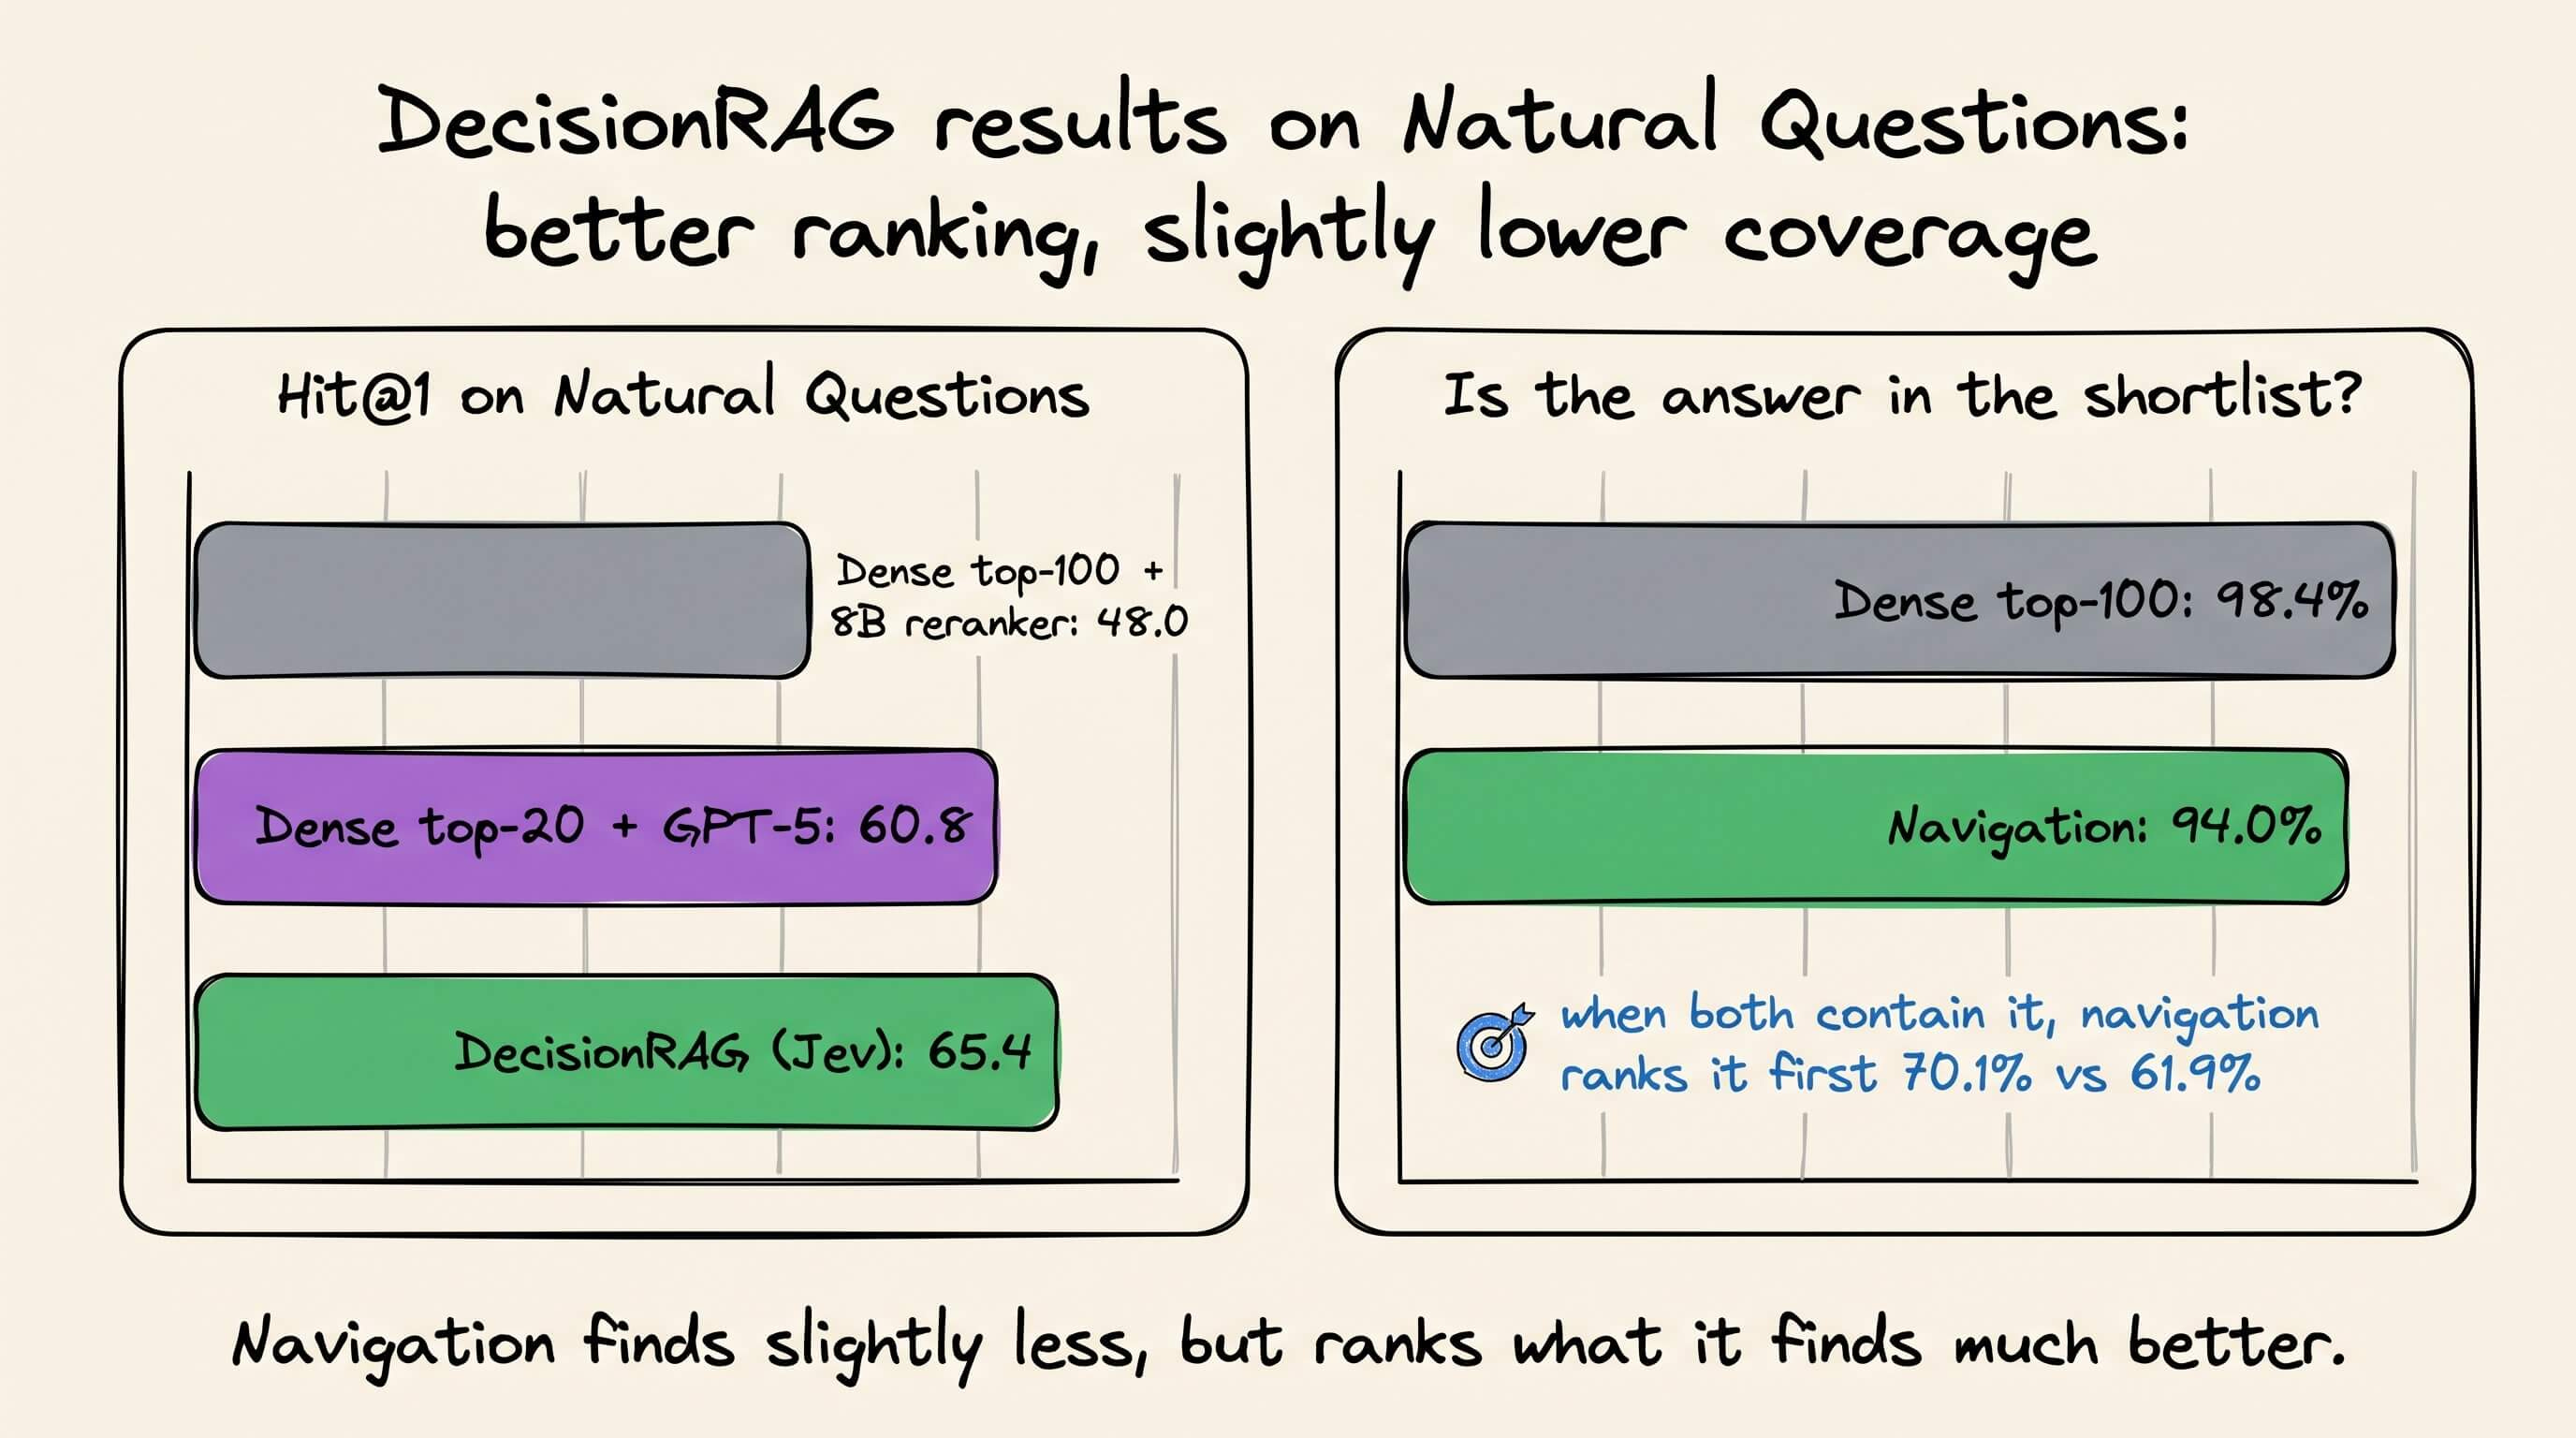
On Natural Questions, its top pick contained the answer 65.4% of the time. Embedding search plus an 8B reranker got 48.0%, and GPT-5 reranking the dense top 20 got 60.8%.
The gain comes from ranking, not coverage. Embedding search’s top 100 holds the answer more often than the navigated shortlist, 98.4% vs. 94.0%. But when both contain it, navigation puts it first 70.1% of the time vs. 61.9%.
Median retrieval takes under 2 seconds per query. Each method was timed in a different setup, though, so this isn’t a controlled speed comparison.
There are limits:
↳ It needs a sensible hierarchy.
↳ A document pruned early is gone for good.
↳ It skips embedding search only at query time, since the Wikipedia tree was built offline with embeddings.
If you’re building a RAG system, this is worth benchmarking against your current setup.
Here’s the paper: Retriever-Free Retrieval: Navigating Documents with Decision Models →
Whichever retrieval you pick, a RAG system only works when every stage holds up: chunking, embeddings, retrieval, reranking, evaluation, and latency. Our full RAG crash course covers RAG from basics to beyond:
Part 1: Build the complete RAG workflow, including chunking, embeddings, retrieval, and reranking →
Part 2: Evaluate retrieval and generation quality with RAG-specific metrics →
Part 3: Reduce RAG latency with faster retrieval and generation paths →
Part 5: Understand CLIP embeddings, multimodal prompting, and tool calling →
Part 6: Build a multimodal RAG system over real-world data →
Part 7: Use Graph RAG for relationships that ordinary chunk retrieval misses →
Part 10: Apply the first set of techniques for production RAG systems →
Part 11: Complete the production RAG techniques and implementation patterns →
Part 12: Reduce prefill latency by reusing KV caches without a shared prefix →
Part 13: Preload a corpus before queries arrive and examine the production constraints →
Part 14: Compress preloaded caches and measure where the approaches break →
Part 15: Implement Block-Attention, Cartridges, and production preloading →
👉 Over to you: Do you turn on batch-invariant mode for your evals, or accept a little drift?
Good day!
The 25% to 45% slowdown for SGLang's deterministic mode turns this into a product decision, not just an eval setting. In the 2026 Stack Overflow Developer Survey, 48% of developers said "I trust it when I can easily verify the output," and getting the same answer twice is a big part of verifying it. Do you see teams paying for batch invariance in production, or keeping it for evals and RL only?
The number I would put next to any temperature-0 golden set is where the tie broke. All 1,000 Qwen3-235B Feynman runs agreed for 102 tokens, then 8 of 1,000 took "New York City" instead of "Queens" after a batch-size change moved two logits by about 0.0002. That is not sampler noise: the same batch twice is bitwise identical, and the split only changes when other requests change how the H100 splits the reduction. I would turn on the batch-invariant flag for evals and RL rollouts, and log the batch size beside the completion, because SGLang's deterministic path is the one LMSYS measured at roughly 25% to 45% slower and you need to know which runs paid that.